解释性AI的一致性验证和解释,用于从传感器数据中预测职业棒球运动员的年度本垒打
Shohei Shibata1, Yuto Kase2, Yusuke Yoshikawa2
1Global Equipment Product Department, Mizuno Corporation, Suminoe-ku, Osaka, 559-8510, Japan. shshibat@mizuno.co.jp.
Scientific reports
|September 25, 2025

概括
职业棒球运动员可以使用分析蝙蝠速度和质量的机器学习模型来预测本垒打. 蝙蝠的最佳速度为33.3 m/s,旋转加速超过157 m/s2,蝙蝠的理想质量为0.91 kg.
科学领域:
- 运动科学 运动科学 运动科学
- 生物力学 生物力学
- 机器学习 机器学习
背景情况:
- 预测运动表现对于训练优化至关重要.
- 棒球分析越来越多地利用先进的技术和数据.
研究的目的:
- 开发和解释一个机器学习模型,用于预测每年的本垒打.
- 确定影响本垒打潜力的关键动力学和物理因素.
主要方法:
- 利用随机森林机器学习模型.
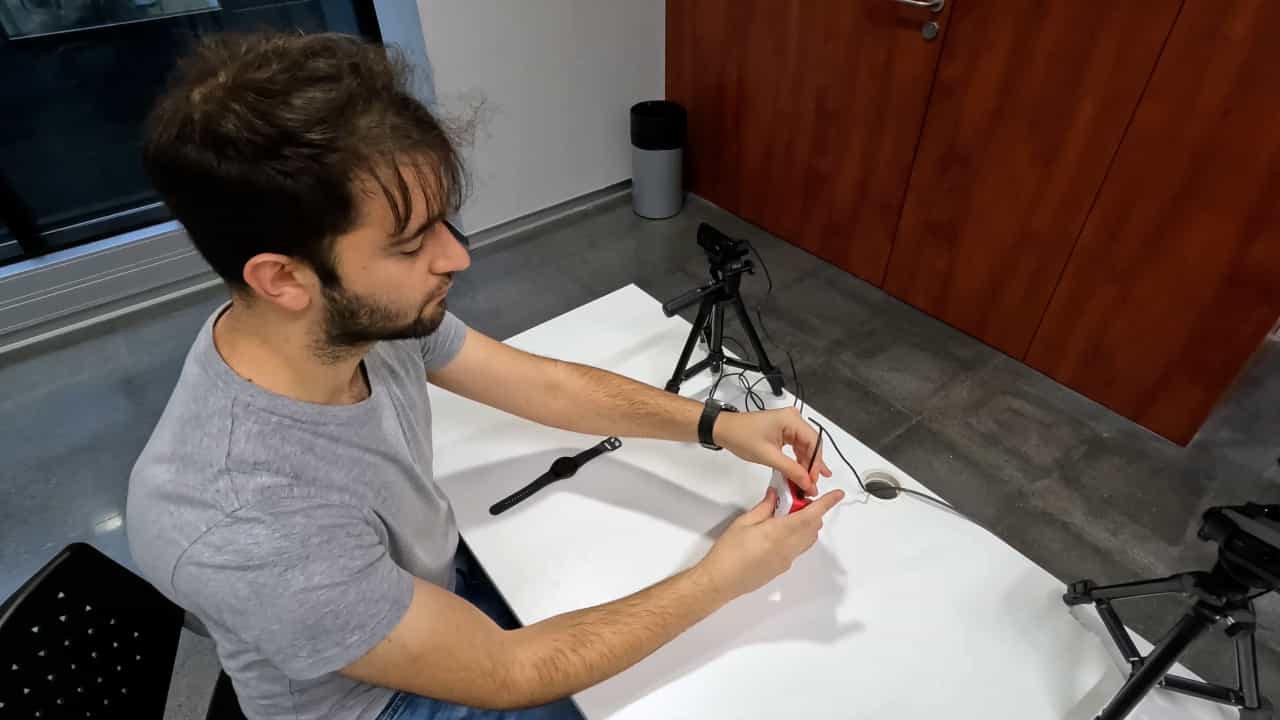
- 通过安装在蝙蝠上的传感器收集了41名职业棒球运动员的蝙蝠动力学和质量数据.
- 采用SHAP分析来解释模型和特征的重要性.
主要成果:
- 蝙蝠速度,蝙蝠质量和旋转加速被确定为关键预测因素.
- 蝙蝠的速度为33.3米/秒,旋转加速>157米/秒2与增加的本垒打预测相关.
- 建议蝙蝠的最佳质量为0.91公斤.
结论:
- 高本垒打潜力与高击球速度的挥杆加速增加有关.
- 打更多本垒打的球员应该专注于用稍重一点的蝙蝠实现高击球速度.
相关概念视频
 01:25
Multiple Regression
3.8K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.8K
 01:11
Residuals and Least-Squares Property
9.1K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
9.1K
 01:19
Variation
7.7K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
7.7K