
视觉增强对跨视角和身体表征体现技能获取的作用
IEEE transactions on visualization and computer graphics
|October 2, 2025

概括
这项研究引入了一种新的视觉反框架,用于虚拟现实中获得运动技能. 基于颜色的指导显著改善了学习和体现,特别是对于第一人称视图中的精细运动任务.
科学领域:
- 虚拟现实 (VR) 是一种虚拟现实.
- 人与计算机的交互 (HCI)
- 运动学习是指运动学习.
背景情况:
- 在VR中沉浸式实施方案显示了获得运动技能的潜力.
- 实时视觉指导在不同的视角和身体表征需要进一步探索.
研究的目的:
- 引入和评估一个以木偶为灵感的视觉反框架,用于体现式学习.
- 研究连续视觉联系 (线条,颜色,厚度) 对空间偏差外部化和运动技能的影响.
- 通过不同的视角 (第一人称,第三人称) 和运动任务类型 (精细和粗细) 来评估该框架的有效性.
主要方法:
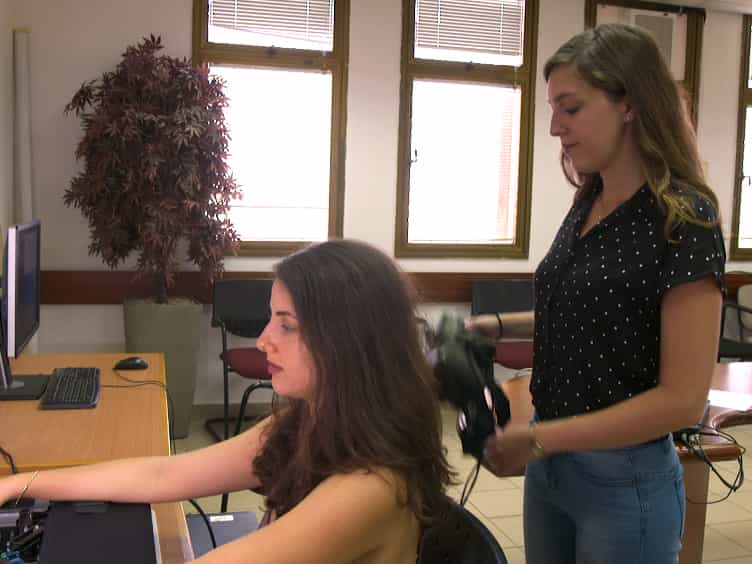
- 对40名参与者进行了一项受控的虚拟现实实验.
- 参与者执行了手势模仿任务,涉及细 (手势语言) 和粗 (航空指挥) 运动部件.
- 采用了以木偶为灵感的视觉反框架,使用线条,颜色和厚度的线索.
主要成果:
- 基于颜色的指导显著提高了模仿精度和短期学习.
- 感知体现,存在,代理和任务参与得到了改进.
- 这些好处在基于手指的任务和第一人称视角中尤为明显.
结论:
- 这种以木偶为灵感的视觉反框架有效地在VR中体现了体现的学习.
- 基于颜色的视觉线索是改善运动技能的有希望的方法,特别是在精细运动任务中.
- 未来的研究应该探索各种视觉指导策略及其对各种背景下的体现和学习的影响.

相关概念视频
 01:21
Gestalt Principles of Perception
1.1K
Gestalt principles provide a framework for understanding how humans perceive objects as unified wholes within their context. These principles are essential in explaining the cognitive processes that make sense of complex visual stimuli by organizing them into coherent groups. One fundamental principle is proximity, which posits that objects located close to each other are perceived as a collective group. For instance, when dots are positioned near one another, the visual system interprets them...
1.1K
 02:57
The Sense of Self: Reflected Self-Appraisal and Social Comparison
55.4K
According to Charles Cooley, we base our image on what we think other people see (Cooley 1902). We imagine how we must appear to others, then react to this speculation. We don certain clothes, prepare our hair in a particular manner, wear makeup, use cologne, and the like—all with the notion that our presentation of ourselves is going to affect how others perceive us. We expect a certain reaction, and, if lucky, we get the one we desire and feel good about it. But more than that, Cooley...
55.4K
 01:14
Steps in the Modeling Process
634
Albert Bandura's theory of observational learning identifies four critical processes: attention, retention, motor reproduction, and reinforcement or motivation.
Attention is the first necessary component for observational learning. It involves focusing on what the model is doing and saying. For example, if you decide to take a drawing class to enhance your skills, you need to pay close attention to the instructor's words and hand movements. The characteristics of the model significantly...
Attention is the first necessary component for observational learning. It involves focusing on what the model is doing and saying. For example, if you decide to take a drawing class to enhance your skills, you need to pay close attention to the instructor's words and hand movements. The characteristics of the model significantly...
634
 01:15
Depth Perception and Spatial Vision
1.8K
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
1.8K
 01:12
Modeling and Similitude
617
Scaled modeling is a fundamental technique in engineering, enabling the study of large and complex systems by creating smaller, manageable replicas that recreate critical characteristics of the original. In hydrology and civil infrastructure, for example, scaled models of dams help analyze water flow, turbulence, and pressure. This method allows for accurate predictions of real-world behavior within a controlled environment, significantly reducing the cost and time involved in full-scale...
617