

在马来西亚衍生品市场使用K-means集群分析分析投资者行为
Eng Hao Louis Tan1, Yaman Hamed1, Hanita Daud1
1Department of Applied Sciences, Intelligent Asset Reliability Centre, Institute of Emerging Digital Technologies, Universiti Teknologi PETRONAS, Seri Iskandar, Malaysia.
Frontiers in artificial intelligence
|October 3, 2025

概括
这项研究使用人工智能将马来西亚衍生品交易者细分为基于交易行为的五个不同的个人资料. 这些发现有助于为金融市场制定有针对性的风险管理和个性化的交易策略.
科学领域:
- * 金融市场分析分析
- * 金融领域的人工智能
- * 行为金融学
背景情况:
- *衍生品市场是复杂的,不同的交易者行为会影响市场动态.
- * 了解交易者细分对于有效的风险管理和政策制定至关重要.
- *以前的细分研究往往缺乏人工智能驱动的方法所提供的细节性.
研究的目的:
- * 用人工智能驱动的集群技术对马来西亚衍生品交易商进行细分.
- *根据关键的交易行为和经验,识别不同的交易者个人资料.
- * 为金融机构和监管机构提供可操作的见解.
主要方法:
- *利用了来自马来西亚股票交易所 (2022年1月至12月) 的FCPO和FKLI衍生品超过1100万个交易记录的综合数据集.
- * 采用K-means集群算法进行交易员细分.
- * 设计了六个关键功能:交易总额,交易总额,实现利,平均投资回报率,交易者经验和中位数持有日.
- * 应用了反向高压正弦转换,用于异常值处理和特征缩放.
- *使用决策树分类器验证集群.
主要成果:
- * 确定了五种不同的马来西亚衍生品交易员个人资料:高频/高风险/损失,保守/稳定增长,高频/高收益,保守/低收益,谨慎/低活动新手.
- *交易员细分显示了交易量,利能力,风险偏好和经验水平的显著差异.
- *决策树分析提供了可解释的规则,用于将交易者分类到已识别的配置文件中.
结论:
- *人工智能驱动的细分为理解各种衍生品交易者行为提供了强大的方法.
- * 已识别的个人资料为制定定制风险管理策略和个性化金融服务提供了基础.
- * 调查结果支持基于证据的政策制定和金融市场细分的未来研究.
相关概念视频
 01:25
First Derivative Test: Problem Solving
9
Imagine an asset price that crashes to a low point, rebounds sharply as bargain-hunters step in, and then gradually declines. Such behavior can be modeled with a smooth function whose turning points represent locally overvalued and undervalued regions. A convenient example that captures rebound followed by decay is:The high and low points of this curve are identified using the first derivative test, which determines where the function changes from increasing to decreasing or vice versa. To...
9
 01:20
Cluster Sampling Method
14.0K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
14.0K
 01:06
Skewness
17.6K
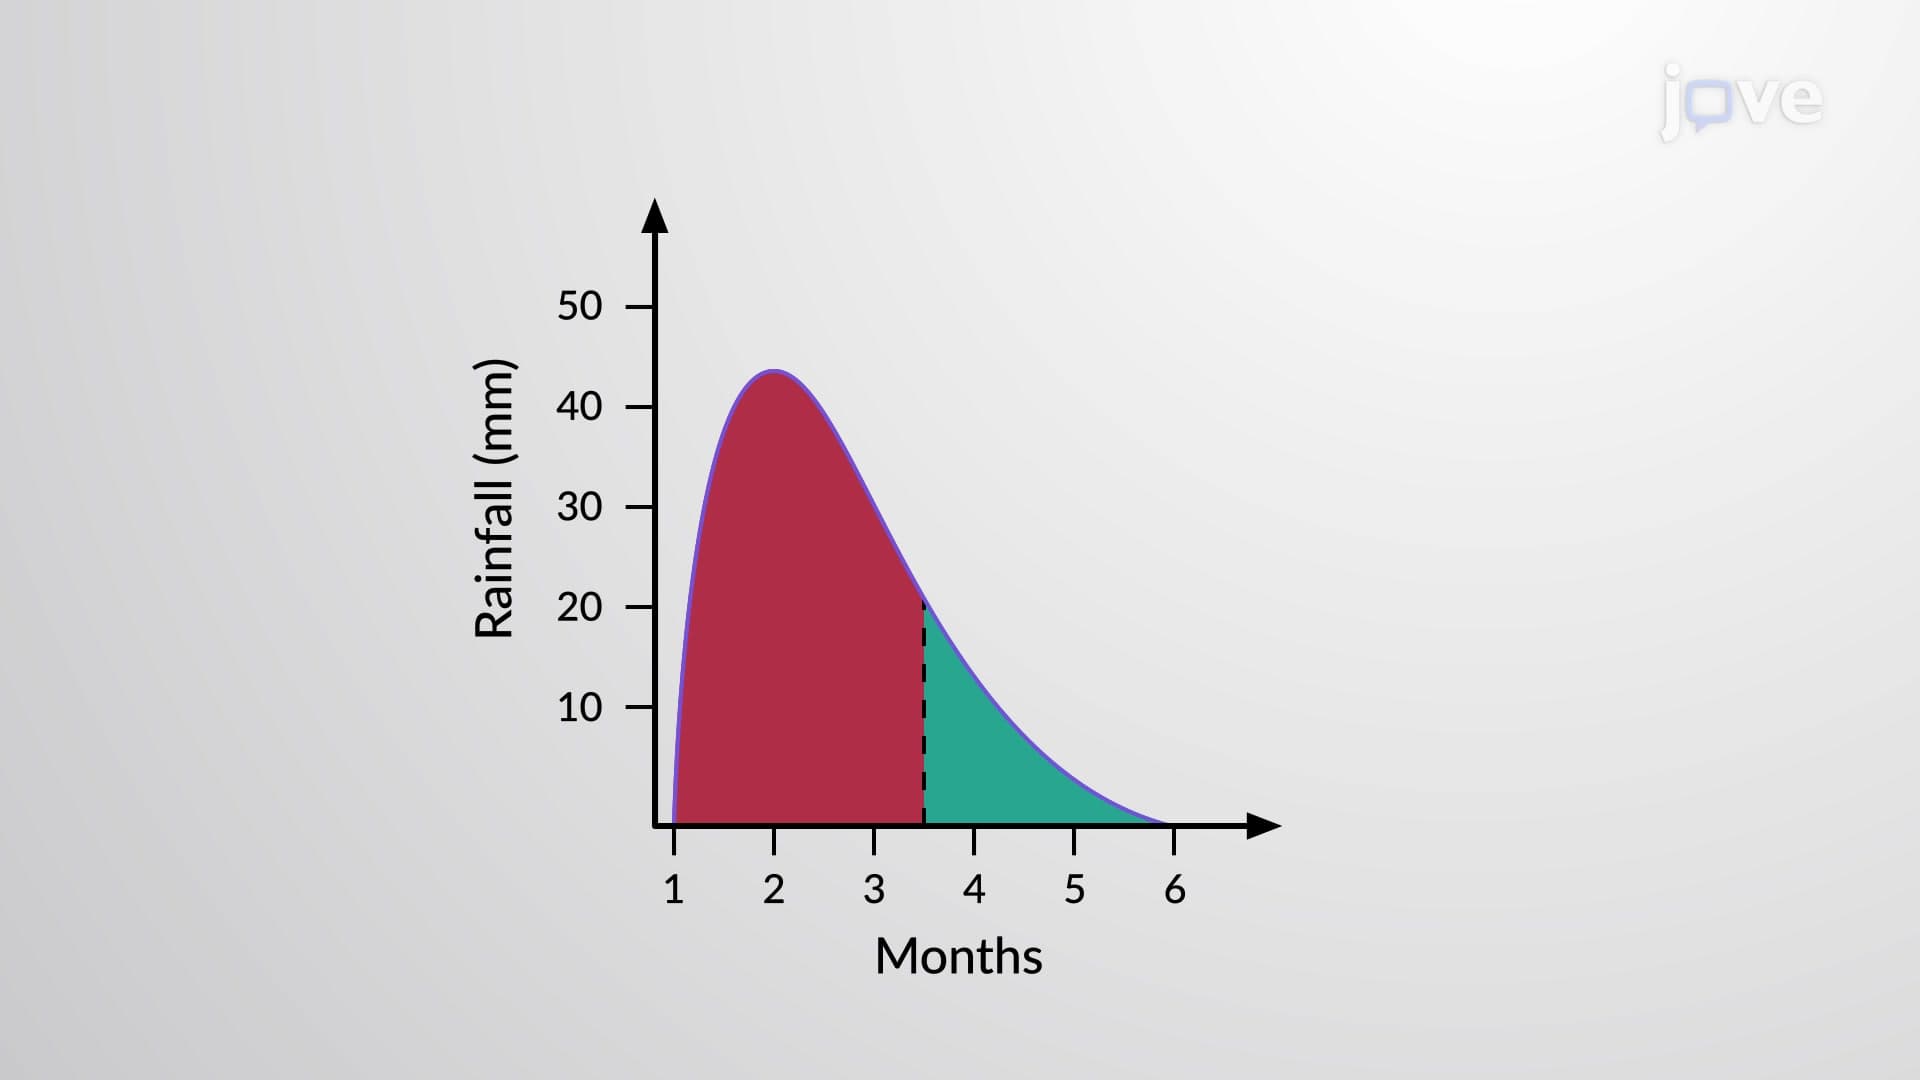
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
17.6K