使用视觉基础模型进行无偏的语义解码,用于少数镜头细分
IEEE transactions on neural networks and learning systems
|October 6, 2025

概括
本研究介绍了一种无偏的语义解码策略,用于使用分段任何模型 (SAM) 和对比语言图像预训练 (CLIP) 的少数镜头细分. 该方法增强了SAM的性能.
科学领域:
- 计算机视觉 计算机视觉
- 人工智能的人工智能
- 机器学习 机器学习
背景情况:
- 短拍细分 (FSS) 旨在对具有有限标记数据的对象进行细分.
- 最近的方法利用了对FSS的分段任何模型 (SAM),因为它具有概括能力.
- 现有的基于SAM的FSS方法由于依赖支持集提示而遭受偏差解码.
研究的目的:
- 提出一个无偏的语义解码 (USD) 策略,用于少数拍摄的细分.
- 通过整合对比性语言图像预训练 (CLIP) 语义来增强SAM对未知的类的概括性.
- 为了提高准确性和减少SAM对FSS的解码过程中的偏差.
主要方法:
- 开发了一个无偏的语义解码 (USD) 策略,集成SAM和CLIP.
- 实施的功能增强策略:全球图像层面和本地像素层面的指导.
- 引入了一个可学习的视觉文本目标提示生成器 (VTPG) 使用CLIP功能.
- 确保没有重新培训基础视觉模型.
主要成果:
- 拟议的美元战略显著改善了SAM在短暂细分方面的表现.
- 功能增强策略有效地利用CLIP进行语义对齐和目标定位.
- 该VTPG产生了信息提示,以更好地针对歧视.
- 在PASCAL-$5^i$和COCO-$20^i$数据集上取得了新的最新结果.
结论:
- 美元策略有效地克服了基于SAM的FSS中的快速偏差解码的局限性.
- 整合CLIP语义增强了SAM适应未知的类的能力.
- 该方法提供了一个强大而高性能的解决方案,用于在没有广泛的再培训的情况下进行少数拍摄细分.
相关概念视频
 01:24
Vision
59.3K
Vision is the result of light being detected and transduced into neural signals by the retina of the eye. This information is then further analyzed and interpreted by the brain. First, light enters the front of the eye and is focused by the cornea and lens onto the retina—a thin sheet of neural tissue lining the back of the eye. Because of refraction through the convex lens of the eye, images are projected onto the retina upside-down and reversed.
59.3K
 01:22
Force Classification
2.3K
Forces play a crucial role in the study of physics and engineering. They are essential in describing the motion, behavior, and equilibrium of objects in the physical world. Forces can be classified based on their origin, type, and direction of action.
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...
2.3K
 01:15
Depth Perception and Spatial Vision
1.8K
Depth perception is the ability to perceive objects three-dimensionally. It relies on two types of cues: binocular and monocular. Binocular cues depend on the combination of images from both eyes and how the eyes work together. Since the eyes are in slightly different positions, each eye captures a slightly different image. This disparity between images, known as binocular disparity, helps the brain interpret depth. When the brain compares these images, it determines the distance to an object.
1.8K
 01:20
Deconvolution
543
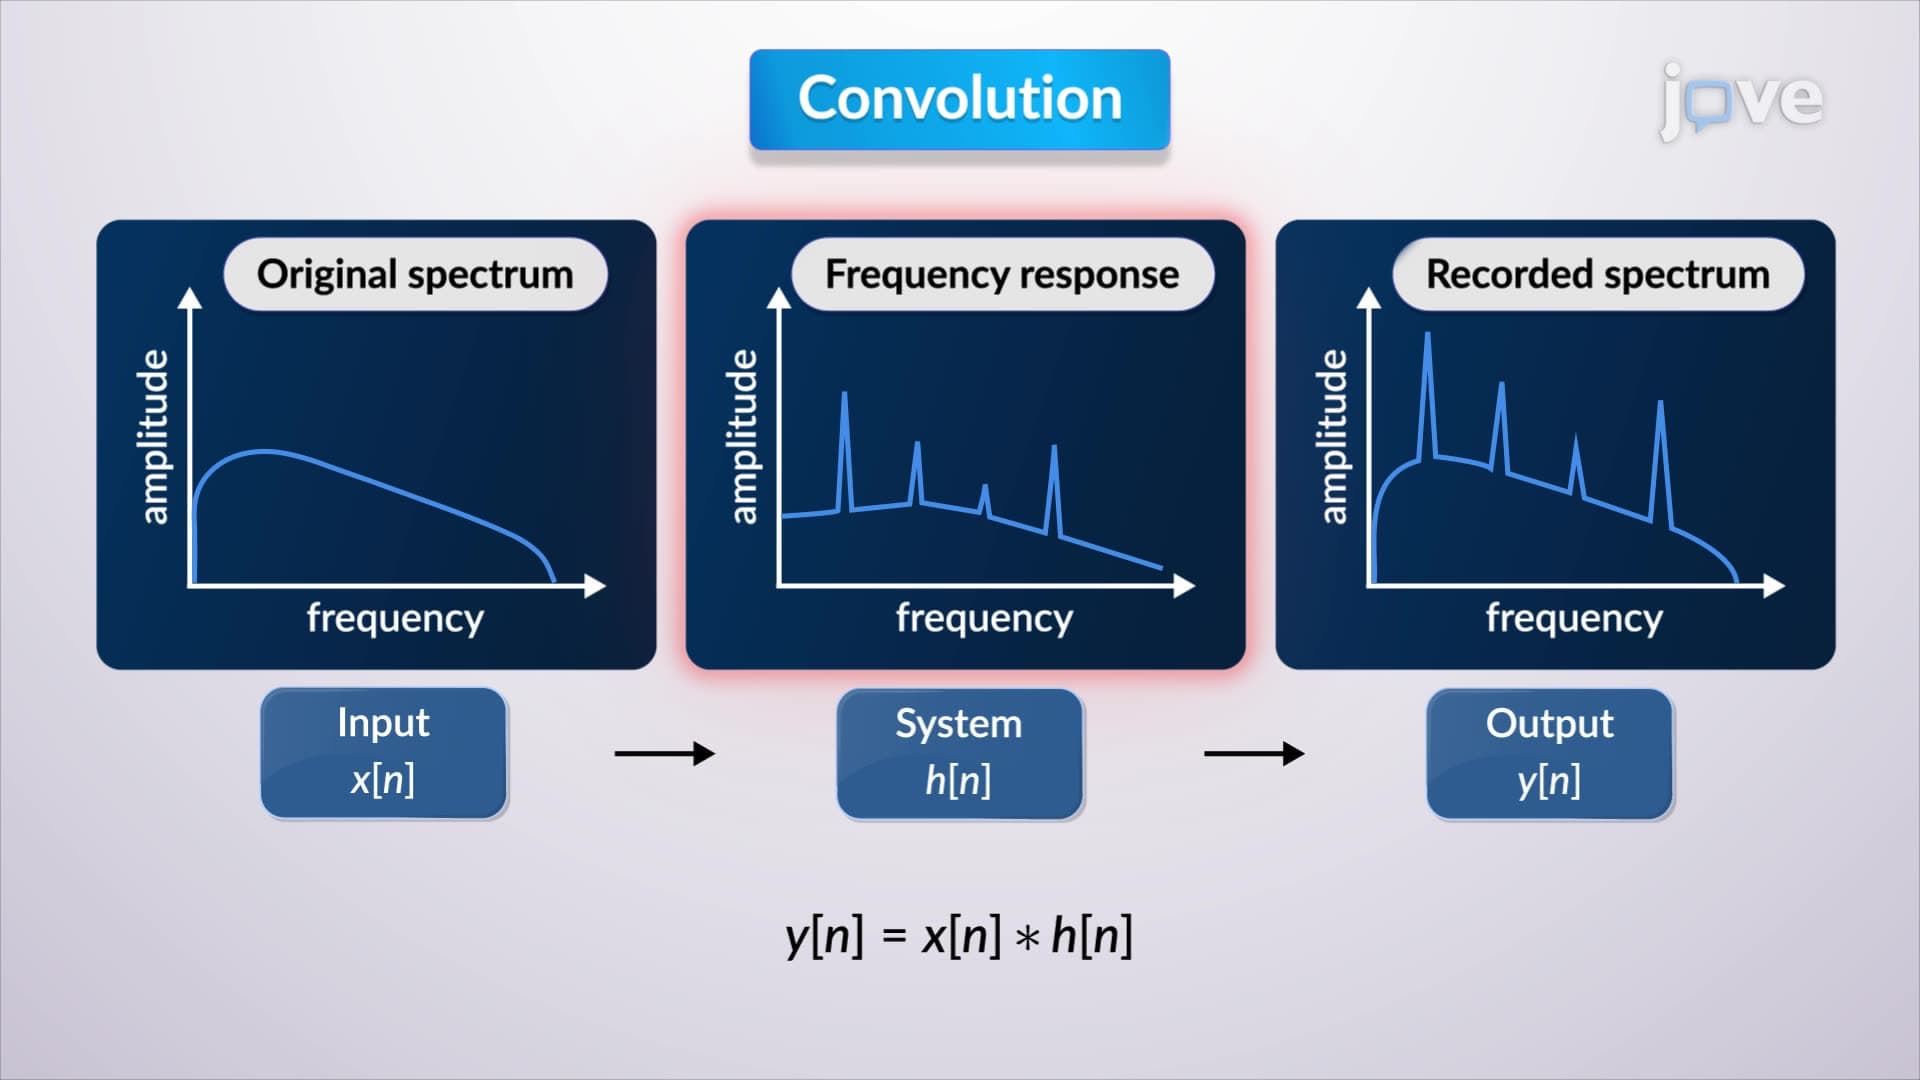
Deconvolution, also known as inverse filtering, is the process of extracting the impulse response from known input and output signals. This technique is vital in scenarios where the system's characteristics are unknown, and they must be inferred from the observable signals.
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
543