相关实验视频
Updated: Jan 12, 2026
05:37

An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.5K
贝叶斯和非贝叶斯估计的二变逆韦布尔分布参数使用排序集采样与并发变量的贝叶斯和非贝叶斯估计
Hiba Z Muhammed1, Mostafa Shaaban2
1Faculty of Graduate Studies for Statistical Research, Cairo University, Giza, Egypt.
Scientific reports
|November 7, 2025

概括
排列采集采样 (RSS) 显著改善了比简单随机采样 (SRS) 的双变量分布参数估计. 使用RSS的贝叶斯方法提供更高的效率和更低的偏差可靠性和寿命分析.
科学领域:
- 统计 统计 统计 统计
- 可能性理论概率理论.
- 可靠性工程可靠性工程
背景情况:
- 估计双变量分布参数对于配对变量依赖关系至关重要.
- 简单的随机抽样 (SRS) 对变量或资源密集型数据可能是低效的.
- 排序集采样 (RSS) 通过对测量的子集进行排序来提高效率.
研究的目的:
- 用贝叶斯式和非贝叶斯式方法估计二变逆韦布尔 (BIW) 分布参数.
- 在不同的估计技术下比较RSS和SRS的性能.
- 为了评估贝叶斯估计的有效性与结合的马先验.
主要方法:
- 使用贝叶斯式和非贝叶斯式 (最大概率估计 - MLE) 技术.
- 在二次错误损失下使用联的马先验的衍生贝叶斯估计器.
- 由于非线性概率方程,使用牛顿-拉普森技术对数值MLE解决方案.
- 在四个参数设置中进行了广泛的蒙特卡洛模拟 (1万次复制).
主要成果:
- 在平均平方误差 (MSE) 和效率 (EFF) 方面,RSS 始终优于 SRS.
- 根据RSS的贝叶斯估计表明,与MLE相比,MSE和偏差较低.
- 对于含有RSS的大型样本,MSE减少了多达50%,EFF超过10个.
- 预先选择对贝叶斯表现产生了重大影响,特别是在小参数方面.
结论:
- 对于估计BIW分布参数,RSS是一种比SRS更有效的采样技术.
- 对于可靠性和寿命分析,建议使用贝叶斯估计,特别是RSS和适当的先验值.
- 这项研究使用对男性体脂肪和胸围的真实数据集来验证这些发现.

相关概念视频
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
1.0K
Parametric survival analysis models survival data by assuming a specific probability distribution for the time until an event occurs. The Weibull and exponential distributions are two of the most commonly used methods in this context, due to their versatility and relatively straightforward application.
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
1.0K
 01:26
Distributions to Estimate Population Parameter
5.0K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
5.0K
 01:21
Friedman Two-way Analysis of Variance by Ranks
475
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
475
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
436
Statistical inference techniques, paramount in hypothesis testing, differentiate into two broad categories: parametric and nonparametric statistics.
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
436
 01:22
Estimating Population Mean with Unknown Standard Deviation
8.7K
In practice, we rarely know the population standard deviation. In the past, when the sample size was large, this did not present a problem to statisticians. They used the sample standard deviation s as an estimate for σ and proceeded as before to calculate a confidence interval with close enough results. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
William S. Gosset (1876–1937) of the...
William S. Gosset (1876–1937) of the...
8.7K
 01:02
Ranks
448
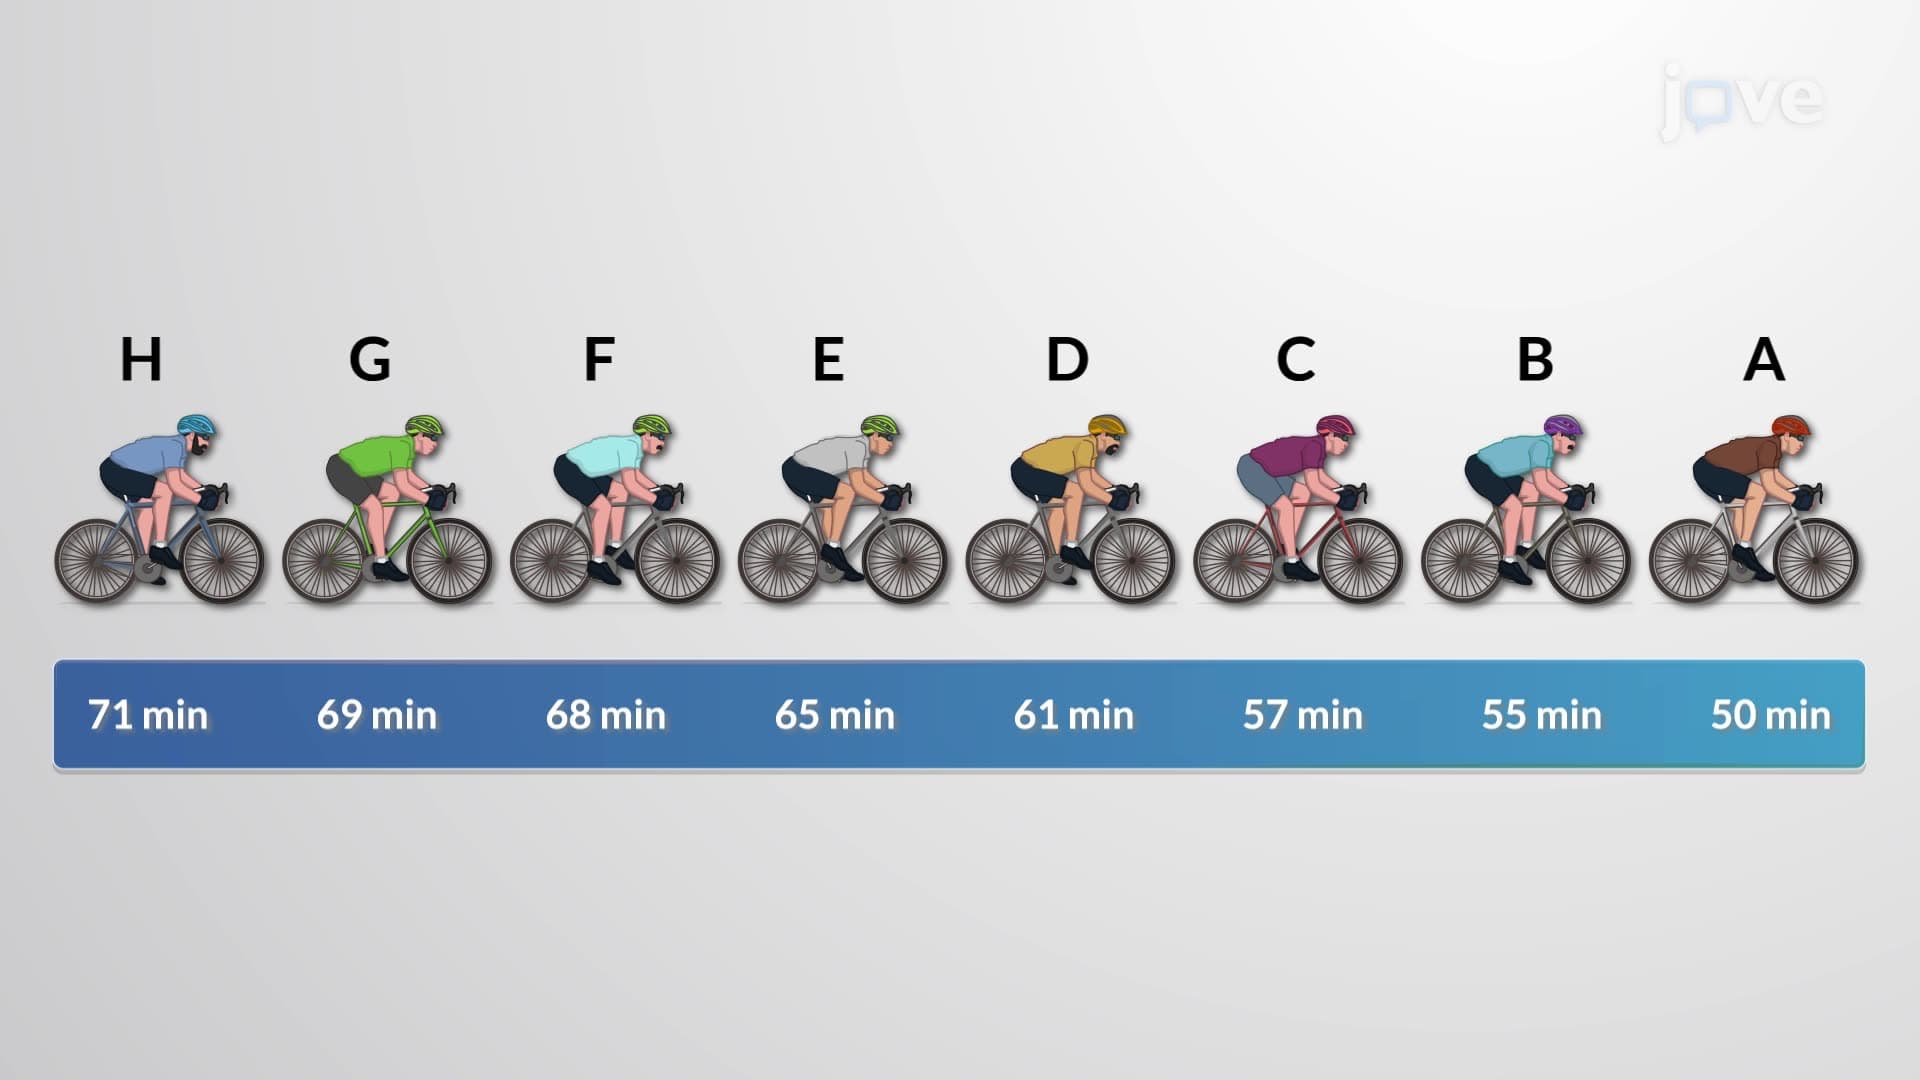
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
448