

概括
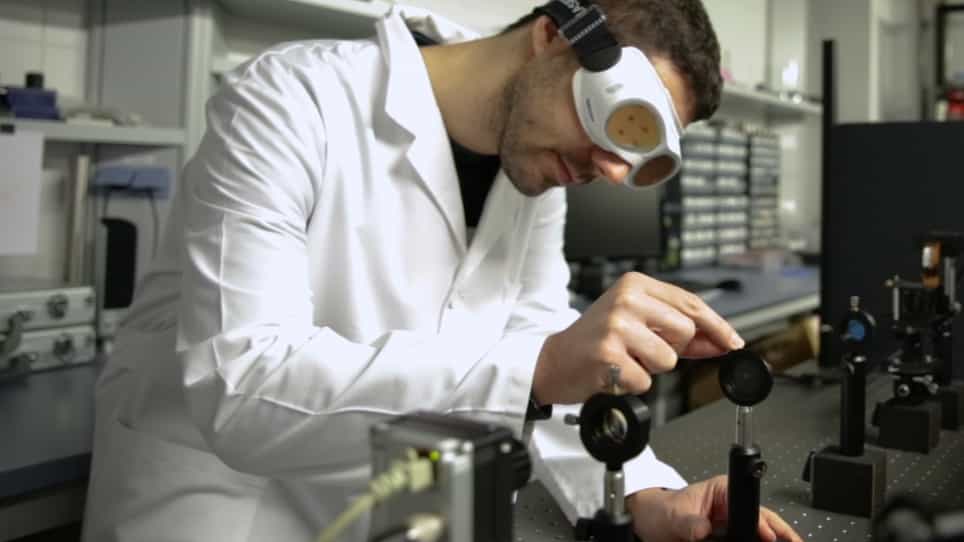
一个新的自适应阶段锁定策略增强了连贯束组合系统中的光学连贯锁定. 这种深度强化学习方法提高了同步速度和适应干扰的能力.
科学领域:
- 光学和光子学 在光学和光子学.
- 人工智能的人工智能
- 控制系统工程 控制系统工程
背景情况:
- 通过单探测器电子频率标记 (LOCSET) 锁定光学连贯性对于连贯束组合 (CBC) 系统的相锁定至关重要.
- 目前的LOCSET方法需要手动同步和超参数调整,限制性能和适应干扰的适应性.
- 由于这些手动限制,LOCSET的全部潜力仍未得到充分利用.
研究的目的:
- 使用深度强化学习在CBC系统中开发LOCSET的自适应阶段锁定策略.
- 为了使LOCSET参数在应对系统干扰时的自动同步和动态优化.
- 为了克服现有的LOCSET实现中手动控制的局限性.
主要方法:
- 提出了一个支持深度强化学习的自适应阶段锁定策略,包括一个延迟剂和一个适应剂.
- 延迟剂通过识别最佳相延迟配置,自动同步连贯解调.
- 该Ada-Agent动态调整比例系数和整合时间以应对干扰.
主要成果:
- 在四通道CBC系统中的实验验证证明了拟议策略的有效性.
- 延迟剂成功地在单个步骤中找到最佳的相延迟组合.
- 与标准LOCSET相比,Ada-Agent在各种相位干扰下实现了4.5倍的恢复速度改进.
结论:
- 拟议的基于深度强化学习的自适应阶段锁定策略显著提高了CBC系统中的LOCSET性能.
- 这种方法提供了自动同步和动态适应性,克服了手动控制的局限性.
- 该战略有可能在现场应用,以改善各种CBC系统的相锁.
相关概念视频
 01:22
Phase-lead and Phase-lag Controllers
515
Understanding the working function of different types of controllers can be illustrated with practical analogies, such as adjusting a stereo's volume equalizer. Cranking up the bass involves a phase-lead controller, which functions as a high-pass filter, while increasing the treble uses a phase-lag controller, which acts as a low-pass filter. PD controllers, similar to high-pass filters, enhance the system's response to high-frequency components. PI controllers, akin to low-pass...
515
 01:23
Reinforcement
804
Positive and negative reinforcement are key concepts in operant conditioning, a learning process where the consequences of a behavior affect the likelihood of that behavior being repeated.
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
804
 01:27
Associative Learning
1.2K
Associative learning is a fundamental concept in behavioral psychology, wherein a connection is established between two stimuli or events, leading to a learned response. This process is critical in understanding how behaviors are acquired and modified. Conditioning, the mechanism through which associations are formed, can be divided into two main types: classical conditioning and operant conditioning, each elucidating different aspects of associative learning.
Classical conditioning, also known...
Classical conditioning, also known...
1.2K
 01:24
Reinforcement Schedules
440
Positive reinforcement is a powerful method for teaching new behaviors to both animals and humans. B.F. Skinner demonstrated this with his experiments using rats in a Skinner box. When a rat pressed a lever, it received a food pellet. This immediate reward encouraged the rat to repeat the behavior. This method, where a reward follows every instance of the behavior, is known as continuous reinforcement. It is highly effective for establishing new behaviors quickly.
Once a behavior is learned,...
Once a behavior is learned,...
440
 01:12
Observational Learning
804
Albert Bandura's observational learning, also known as imitation or modeling, occurs when a person observes and imitates another's behavior. It is a quicker process than operant conditioning. A well-known example is the Bobo doll study, where children who saw an adult acting aggressively towards the doll were more likely to act aggressively when left alone, compared to those who observed a nonaggressive adult. Many psychologists view observational learning as a form of latent learning...
804
 01:15
Prismatic Beams: Problem Solving
428
In the design of a supported timber beam subjected to a distributed load, both the beam's physical dimensions and the timber's characteristics, such as its grade and species, are critical. These factors determine the allowable stress values, which are crucial for calculating the necessary beam depth to ensure structural integrity and safety.
The design begins with analyzing the beam as a free body to identify moments and force balances, thereby determining support reactions. Next, the...
The design begins with analyzing the beam as a free body to identify moments and force balances, thereby determining support reactions. Next, the...
428