相关实验视频
Updated: Jan 10, 2026
10:16

Mining Spatial Transcriptomics Datasets using DeepSpaceDB
Published on: September 5, 2025
626
SpaGene:空间基因推算的深度对抗框架
Aishwarya Budhkar1, Juhyung Ha1, Qianqian Song2
1Department of Computer Science, Indiana University Bloomington, Indiana, USA.
bioRxiv : the preprint server for biology
|November 24, 2025

概括
SpaGene是一个深度学习框架,集成了单细胞RNA测序和空间转录组学数据. 它通过赋予缺失的基因表达增强了空间转录学,为组织生物学和疾病进展提供了更深入的见解.
科学领域:
- 计算生物学 计算生物学
- 基因组学就是基因组学.
- 生物信息学是一种生物信息学.
背景情况:
- 单细胞RNA测序 (scRNA-seq) 提供高分辨率的基因表达,但缺乏空间上下文.
- 空间转录组学提供空间分辨率,但具有有限的转录组覆盖范围.
- 整合两种数据类型对于全面的组织分析至关重要.
研究的目的:
- 引入SpaGene,这是一个新的深度学习框架,用于集成scRNA-seq和空间转录组学数据.
- 使用scRNA-seq数据在空间转录组学数据集中归因缺失的基因表达.
- 为了增强来自空间转录学的生物见解.
主要方法:
- SpaGene使用了一个深度学习架构,具有编码器-解码器对,翻译器和区分器.
- 该框架将全转录组单细胞基因表达数据与空间上下文集成在一起.
- 在各种数据集中,性能与最先进的方法进行了基准测试.
主要成果:
- SpaGene实现了卓越的性能,平均比Pearson相关系数 (PCC) 高33%,结构相似度指数 (SSIM) 高21%,根平均平方误差 (RMSE) 低6.6%.
- 该模型可靠地归因于缺失的基因,提供了全面的转录基因特征.
- 对肺瘤组织的应用揭示了瘤边界的免疫细胞丰富,并限制了髓状细胞的贩运.
结论:
- SpaGene有效地集成scRNA-seq和空间转录组学数据,增强空间转录组学能力.
- 该框架为更深入的生物学理解提供了空间分辨率,增强的转录组数据.
- 这些发现为瘤与免疫相互作用以及潜在的治疗开发途径提供了新的见解.
相关概念视频
 01:11
Genome-wide Association Studies-GWAS
15.2K
Genome-wide association studies or GWAS are used to identify whether common SNPs are associated with certain diseases. Suppose specific SNPs are more frequently observed in individuals with a particular disease than those without the disease. In that case, those SNPs are said to be associated with the disease. Chi-square analysis is performed to check the probability of the allele likely to be associated with the disease.
GWAS does not require the identification of the target gene involved in...
GWAS does not require the identification of the target gene involved in...
15.2K
 02:37
Gene Duplication and Divergence
7.8K
The seminal work of Ohno in 1970 popularized the idea of gene duplication and divergence. DNA sequence comparison studies reveal that a large portion of the genes in bacteria, archaebacteria, and eukaryotes was generated by gene duplication and divergence, indicating its critical role in evolution.
The duplicated copies of the gene are called Paralogs. Paralogs with similar sequences and functions form a gene family. Across several species, a large number of gene families are...
The duplicated copies of the gene are called Paralogs. Paralogs with similar sequences and functions form a gene family. Across several species, a large number of gene families are...
7.8K
 02:07
Improving Translational Accuracy
14.0K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
14.0K
02:07Improving Translational Accuracy
3.5K
3.5K
 01:05
Single Nucleotide Polymorphisms-SNPs
17.9K
A single nucleotide polymorphism or SNP is a single nucleotide variation at a specific genomic position in a large population. It is the most prevalent type of sequence variation found in the human genome. Point mutations that occur in more than 1% of the population qualify as SNPs. These are present once every 1000 nucleotides on an average in the human genome. Replacement of a purine with another purine (A/G) or a pyrimidine with another pyrimidine (C/T) is known as a transition. In contrast,...
17.9K
 02:34
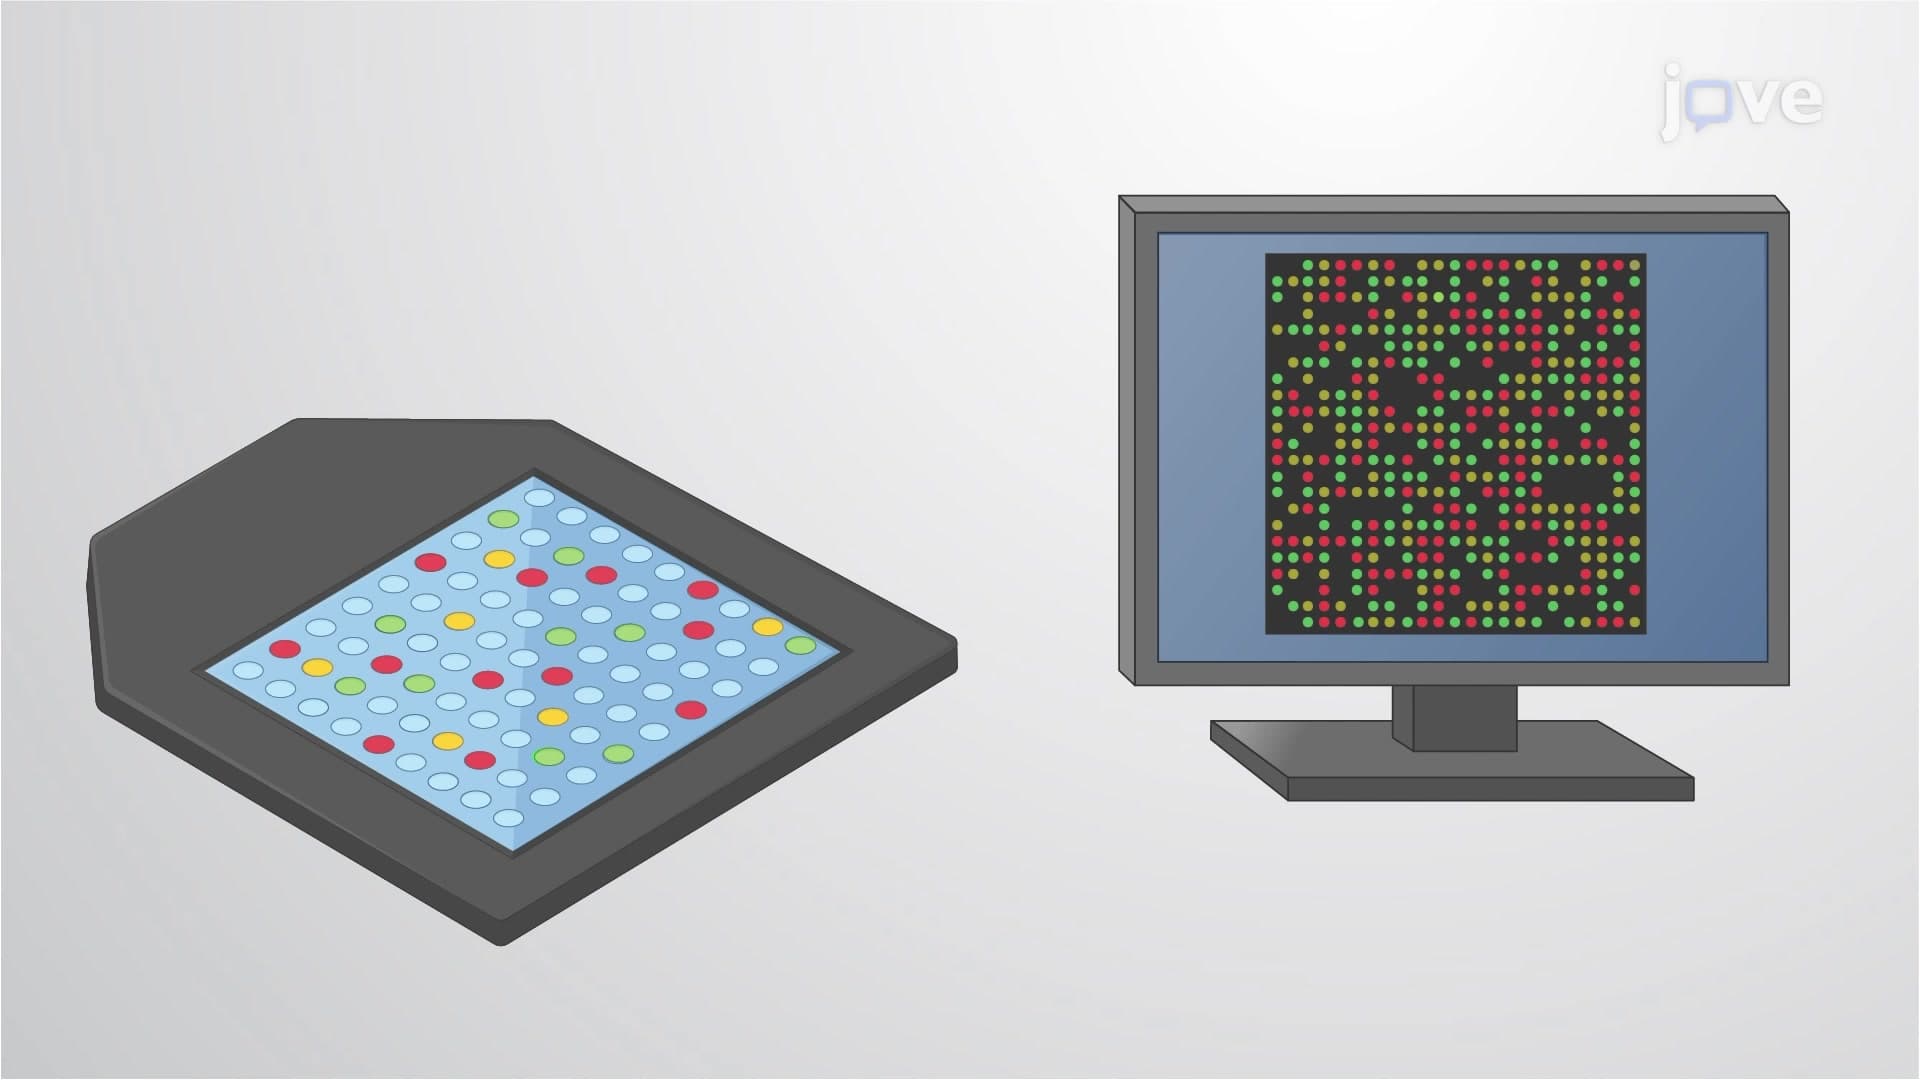
DNA Microarrays
20.6K
Microarrays are high-throughput and relatively inexpensive assays that can be automated to analyze large quantities of data at a time. They are used in genome-wide studies to compare gene or protein expression under two varied conditions, such as healthy and diseased states. Microarrays consist of glass or silica slides on which probe molecules are covalently attached through surface functionalization. Most commonly, the slides are prepared through the chemisorption of silanes to silica...
20.6K