
什么时候项目细微差别在组织中对预测有用? 比较项目级,规模级和整体机器学习模型的有效性
Chen Tang1, Louis Hickman2, Q Chelsea Song3
1Kogod School of Business, American University.
The Journal of applied psychology
|December 15, 2025

概括
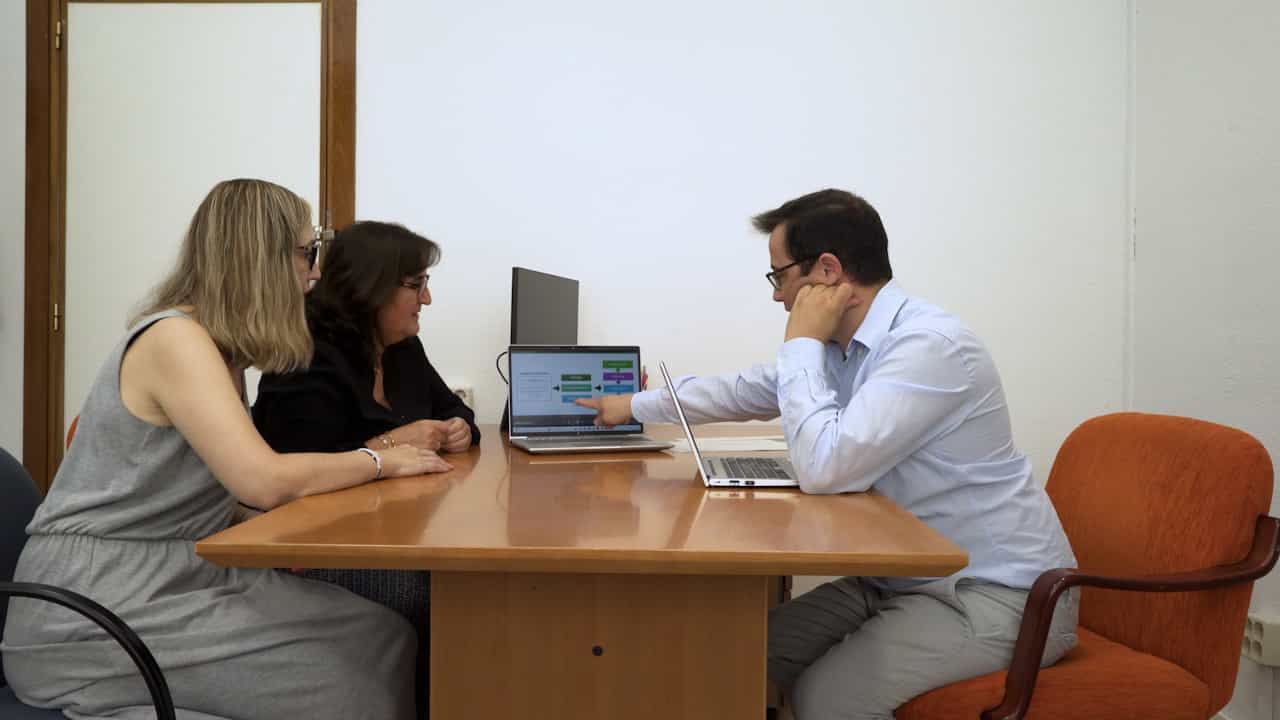
项目级预测模型比规模级模型提供更高的准确性,特别是当满足特定条件时,如高内部一致性和大样本大小. 这些模型捕获了在聚合得分中丢失的细微数据.
科学领域:
- 组织心理学 组织心理学
- 预测建模预测建模
- 心理测量 心理测量 心理测量
背景情况:
- 传统的预测模型使用尺度得分,可能会失去有价值的项目特定差异.
- 项目级预测模型显示,在组织环境中提高准确性是有前途的.
- 优于项目级与规模级模型的条件仍然不清楚.
研究的目的:
- 调查项目级或规模级模型何时更适合于组织实践中的预测.
- 确定项目细微差别影响预测有效性的条件.
- 为了比较项目和规模级预测模型的与标准相关的有效性.
主要方法:
- 检查了现实世界的组织数据集,以确定项目细微差别.
- 进行了蒙特卡洛模拟,对细微差别分布,效果大小,内部一致性和样本大小进行了变化.
- 分析了项目级和规模级模型的与标准相关的有效性.
主要成果:
- 当很少有项目有细微差别,细微差别效果大小很大,内部一致性很高,训练样本大小很大时,建议使用项目级模型.
- 有利于项目级模型的条件在组织数据中很常见.
- 当模型选择模糊时,合并模型是可行的替代方案.
结论:
- 在特定条件下,项目级模型可以在组织预测中优于传统规模级模型.
- 了解和利用项目细微差别对于准确的预测建模至关重要.
- 该研究提供了实施各种预测模型的实际建议和R代码.
相关概念视频
 01:13
Sensitivity, Specificity, and Predicted Value
1.2K
In healthcare diagnostics, laboratory tests play a crucial role in identifying and diagnosing a wide range of medical conditions. However, interpreting test results is not always straightforward. An abnormal test result does not always confirm the presence of a disease, just as a normal result does not guarantee its absence. To assess the reliability of these diagnostic tools, healthcare practitioners rely on two key statistical indicators: sensitivity and specificity.
Sensitivity is the...
Sensitivity is the...
1.2K
 01:29
Reliability and Validity
13.7K
Reliability and validity are two important considerations that must be made with any type of data collection. Reliability refers to the ability to consistently produce a given result. In the context of psychological research, this would mean that any instruments or tools used to collect data do so in consistent, reproducible ways.
13.7K
 00:55
Ordinal Level of Measurement
31.8K
The way a set of data is measured is called its level of measurement. Correct statistical procedures depend on a researcher being familiar with levels of measurement. For analysis, data are classified into four levels of measurement—nominal, ordinal, interval, and ratio.
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
31.8K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
7.0K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
7.0K
 01:16
Goodness-of-Fit Test
8.1K
The goodness-of-fit test is a type of hypothesis test which determines whether the data "fits" a particular distribution. For example, one may suspect that some anonymous data may fit a binomial distribution. A chi-square test (meaning the distribution for the hypothesis test is chi-square) can be used to determine if there is a fit. The null and alternative hypotheses may be written in sentences or stated as equations or inequalities. The test statistic for a goodness-of-fit test is given as...
8.1K
 01:22
Self-Report Tests of Personality
729
Self-report inventories are objective personality assessments that use multiple-choice items or numbered scales, typically ranging from 1 (strongly disagree) to 5 (strongly agree). They are often called Likert scales after Rensis Likert. These inventories are widely used due to their ease of administration and cost-effectiveness. One of the most prominent examples is the Minnesota Multiphasic Personality Inventory (MMPI), initially developed in the 1940s to assess abnormal personality traits.
729