

冬季小麦产量预测使用基于无人机的多变量时间序列数据和变量独立的标记化
Yan Ge1,2, Zhichang Zhu1, Shichao Jin3
1College of Artificial Intelligence, Nanjing Agricultural University, Nanjing, 210095, China.
Plant phenomics (Washington, D.C.)
|December 19, 2025

概括
使用无人机数据准确预测小麦产量对于粮食安全至关重要. 我们改进的变压器模型通过处理各种特征来提高预测准确性,加速选择高产小麦品种.
科学领域:
- 农业科学 农业科学
- 计算机科学 计算机科学
- 遗传学 是一个遗传学.
背景情况:
- 高产小麦育种对于全球粮食安全至关重要.
- 目前基于无人机的产量预测模型由于简单的数据集成而缺乏准确性.
- 需要先进的方法来利用多变量时间序列数据进行精确的小麦产量估计.
研究的目的:
- 开发一种改进的以变压器为基础的模型,用于准确地图级小麦产量预测.
- 加强多变量时间序列数据的整合,包括植被指数和形态特征.
- 加快选择适应气候,高产的小麦品种.
主要方法:
- 为变压器模型提出了一种新的变量独立的代币化方法.
- 整合了14个植被指数和28个形态特征,使用特征维度嵌入.
- 应用了多变量注意力机制来捕捉各种相关性和贡献.
主要成果:
- 实现了0.862的R2的最佳预测性能,超过了现有模型.
- 证明了结合植被指数和形态特征的优势,产生了4%的性能增长.
- 在各种实验条件 (处理,年份,品种) 中验证了模型的有效性.
结论:
- 改进的变压器模型提供了一种新的,准确的方法,用于定量地块层面的小麦产量预测.
- 变量独立的标记化和多变量注意力增强了复杂时间序列数据的利用.
- 这种方法有助于快速选择优质的小麦品种,有助于繁殖计划和粮食安全.
相关概念视频
 02:16
Light Acquisition
9.3K
In order to produce glucose, plants need to capture sufficient light energy. Many modern plants have evolved leaves specialized for light acquisition. Leaves can be only millimeters in width or tens of meters wide, depending on the environment. Due to competition for sunlight, evolution has driven the evolution of increasingly larger leaves and taller plants, to avoid shading by their neighbors with contaminant elaboration of root architecture and mechanisms to transport water and nutrients.
9.3K
 01:25
Multiple Regression
3.7K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.7K
 01:03
Prediction Intervals
3.1K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.1K
 01:11
Variability: Analysis
421
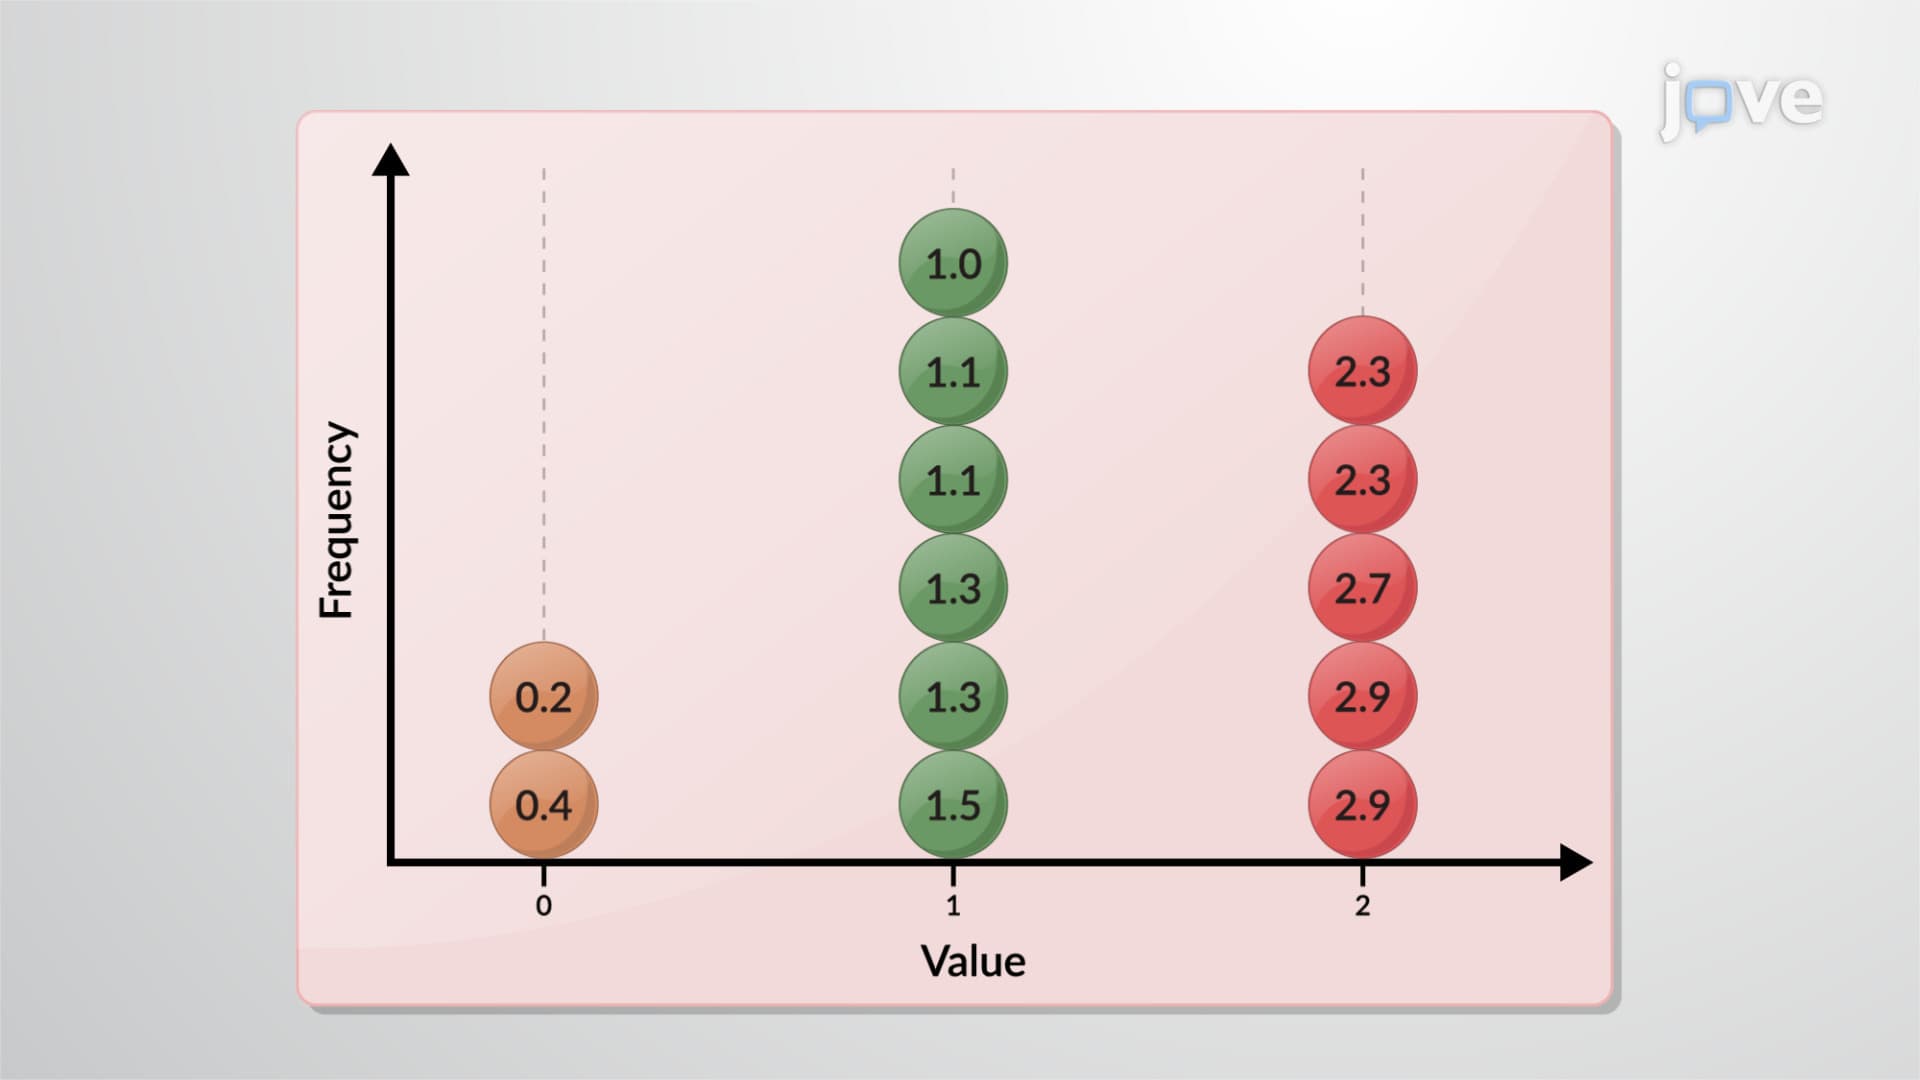
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
421