
为高维的马回归进行信息化的协同数据学习
Claudio Busatto1, Mark A van de Wiel2
1Department of Statistics, Computer Science, Applications "G. Parenti,", University of Florence, Florence, Italy.
Biometrical journal. Biometrische Zeitschrift
|December 30, 2025

概括
我们介绍了信息化的马回归 (infHS),这是一个贝叶斯模型,通过结合先前知识 (共同数据) 来改进高维回归. 这种方法提高了基因组学中的变量选择和预测准确性.
科学领域:
- 基因组学就是基因组学.
- 生物统计学 生物统计学
- 计算生物学 计算生物学
背景情况:
- 高维数据在临床基因组学中很常见,用于识别特征预测因素.
- 结合先前的知识 (共同数据) 可以提高预测模型的性能.
研究的目的:
- 开发一个新的贝叶斯回归模型,用于高维数据,集成共数据.
- 通过利用外部信息来提高变量选择和预测准确性.
主要方法:
- 开发了信息化的马回归 (infHS) 模型.
- 实现了适度尺寸的吉布斯采样器和大规模数据的变量近似.
- 在共同数据变量上的回归参数的回归先前变量.
主要成果:
- 模拟研究表明了包括共同数据的好处.
- 在两个基因组学应用中,infHS模型与现有方法相比显示出更高的性能.
- 变量近似允许对非常大的数据集进行高效的分析.
结论:
- infHS模型有效地将共同数据纳入高维回归.
- 这种方法在基因组学中提供了改进的变量选择和预测性能.
- infHS为不同的数据尺度和推断目标提供灵活的计算工具.
相关概念视频
 01:25
Multiple Regression
3.7K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.7K
 01:11
Regression Analysis
7.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
7.7K
 01:03
Prediction Intervals
3.1K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.1K
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
414
Statistical inference techniques, paramount in hypothesis testing, differentiate into two broad categories: parametric and nonparametric statistics.
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
414
 00:53
Correlation and Regression
3.0K
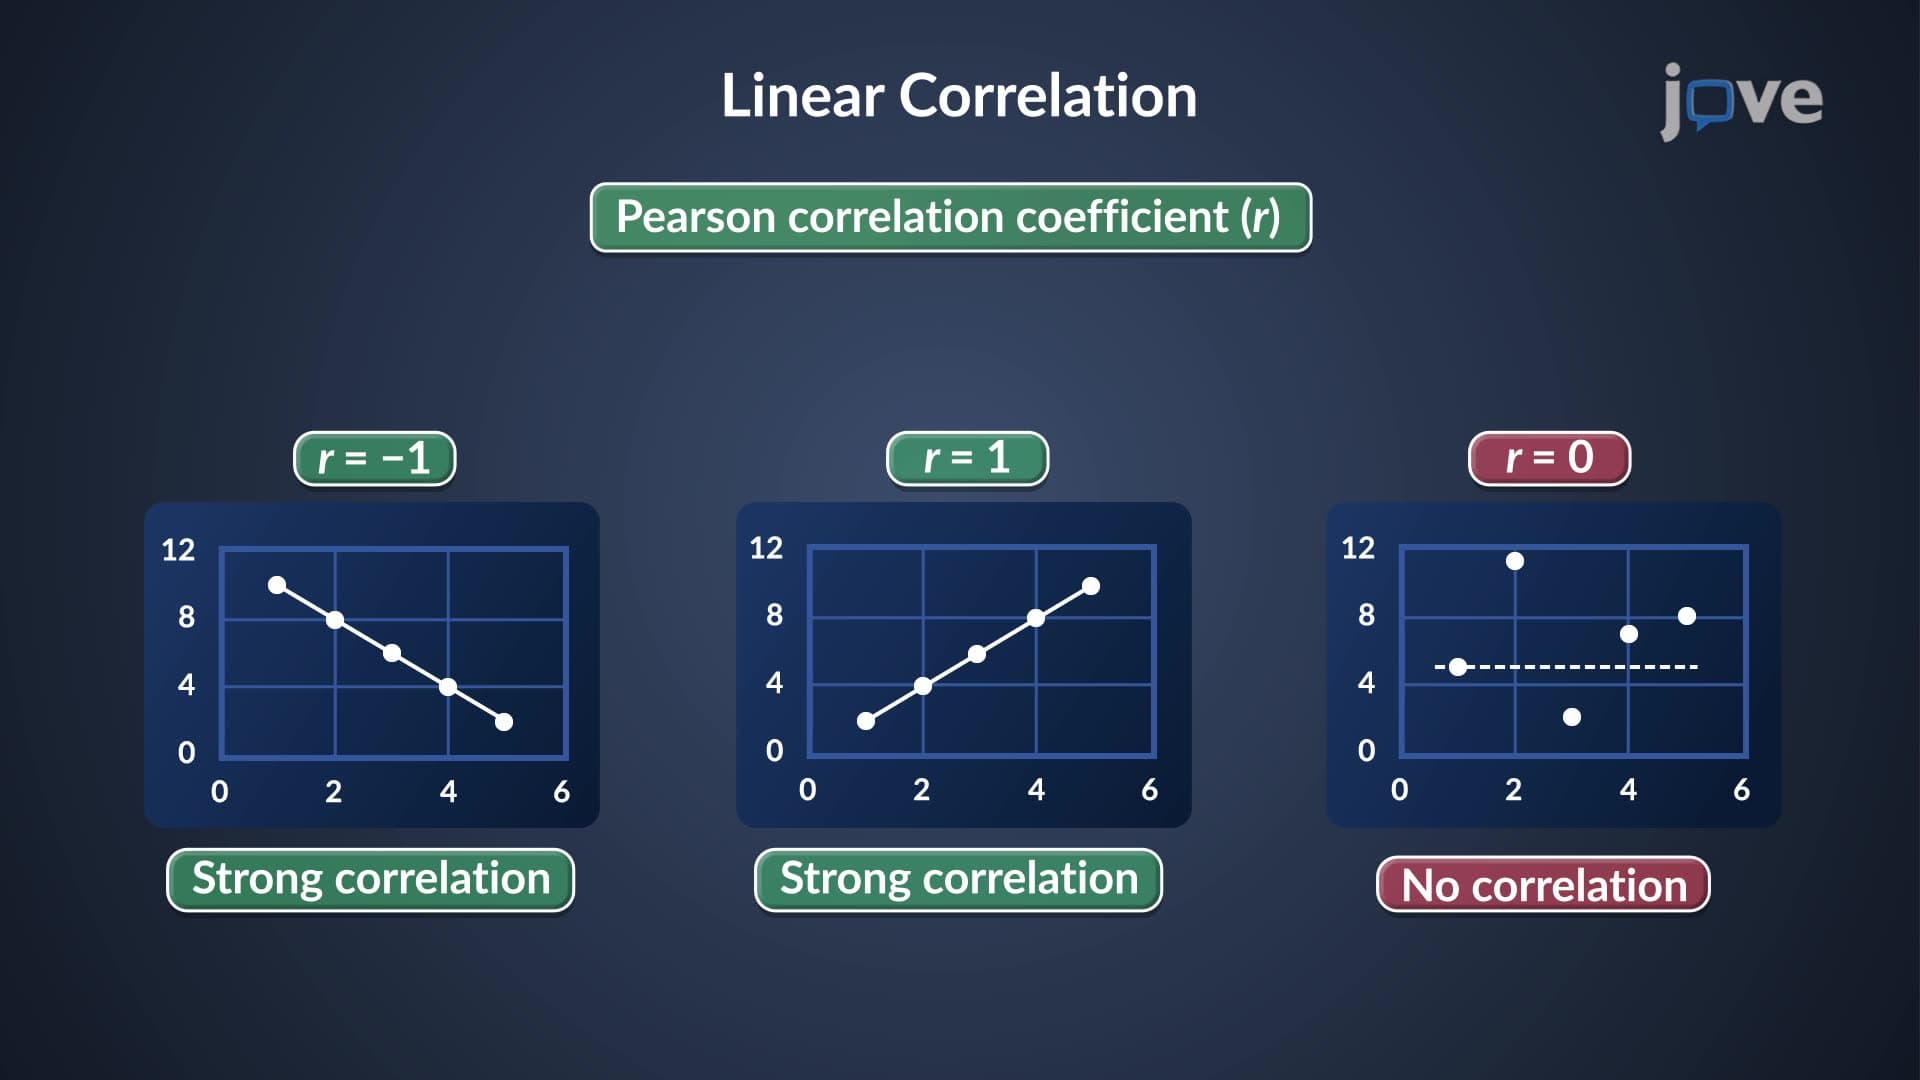
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
3.0K
 01:11
How Data are Classified: Categorical Data
42.4K
A variable, usually notated by capital letters such as X and Y, is a characteristic or measurement that can be determined for each member of a population. Data are the actual values of variables. They may be numbers, or they may be words. Datum is a single value.
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
42.4K