
一致的因子得分回归:为未经纠正的因子得分回归提供更好的替代方案?
Jasper Bogaert1, Wen Wei Loh2, Yves Rosseel1
1Ghent University, Belgium.
Educational and psychological measurement
|January 9, 2026

概括
一致的因子得分回归 (cFSR) 为分析潜在变量关系提供了一个更简单,更准确的替代方法,而不是未经纠正的因子得分回归 (UFSR). 该方法提供了公正的估计和有效的推断,使其成为行为,教育和社会科学研究的理想选择.
科学领域:
- 行为科学 行为科学
- 教育科学教育科学教育科学
- 社会科学 社会科学 社会科学
背景情况:
- 结构方程建模 (SEM) 是潜在变量分析的标准.
- 使用共同的因子得分的未经纠正的因子得分回归 (UFSR) 可以导致偏差的估计和无效的推断.
- 在因子得分回归 (FSR) 中最近的进展旨在提高准确性.
研究的目的:
- 重新审视和评估一致因素得分回归 (cFSR).
- 将cFSR与其他FSR和SEM方法进行比较.
- 要突出cFSR在隐性变量分析方面的优势.
主要方法:
- 进行了广泛的模拟研究.
- 将cFSR与UFSR和其他FSR/SEM方法进行比较.
- 根据收率,偏差,效率和I型错误率来评估业绩.
主要成果:
- 与UFSR相比,cFSR表现出了优越的表现.
- cFSR保持了UFSR的概念简单性.
- cFSR提供了公正的估计和有效的推断.
结论:
- cFSR是行为,教育和社会科学研究人员推的UFSR替代方案.
- 研究人员应该采用cFSR而不是UFSR来进行更可靠的潜变量分析.
- cFSR提供了准确性和简单性的平衡,作为SEM的可行替代品.
更多相关视频
 08:51
Author Spotlight: Integrated Multi-Omics Analysis for Unveiling Multicellular Immune Signatures in Clinical Heart Attack Cohorts
Published on: September 20, 2024
2.0K
 06:48
Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
9.7K
相关概念视频
 01:19
Variation
7.7K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
7.7K
 01:22
Compacting Factor test
538
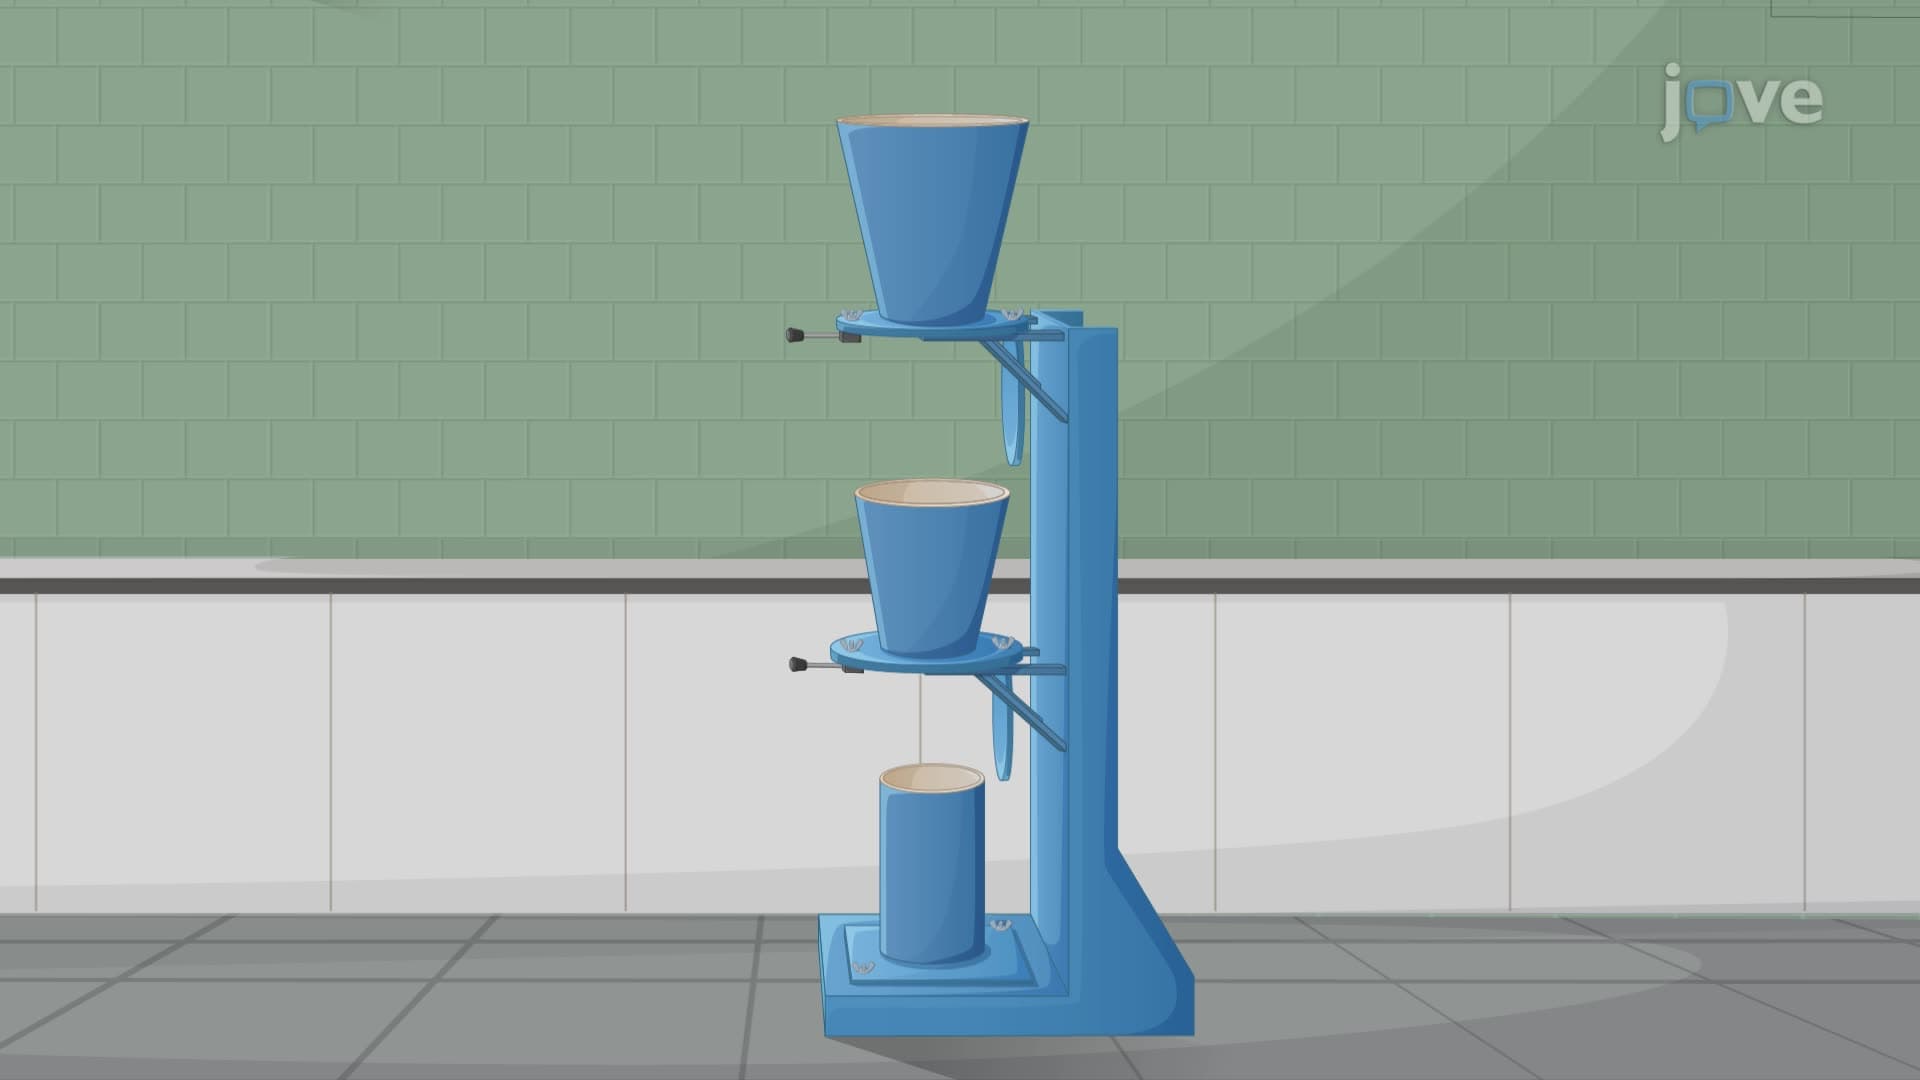
The compacting factor test is a method used to assess the workability of concrete. It is especially suitable for concrete mixes containing aggregates up to one and a half inches in size. This test involves specialized equipment consisting of two truncated cone-shaped hoppers and a cylinder, all with polished interior surfaces to minimize friction.
The procedure begins by placing concrete into the upper hopper without any compaction. Once filled, the bottom door of this hopper is opened,...
The procedure begins by placing concrete into the upper hopper without any compaction. Once filled, the bottom door of this hopper is opened,...
538
 02:01
Factorial Design
13.7K
Factorial Analysis is an experimental design that applies Analysis of Variance (ANOVA) statistical procedures to examine a change in a dependent variable due to more than one independent variable, also known as factors. Changes in worker productivity can be reasoned, for example, to be influenced by salary and other conditions, such as skill level. One way to test this hypothesis is by categorizing salary into three levels (low, moderate, and high) and skills sets into two levels (entry level...
13.7K
 01:25
Multiple Regression
3.7K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.7K
 01:52
Regression Toward the Mean
6.8K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.8K
 01:11
Residuals and Least-Squares Property
9.0K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
9.0K