
在新foundland和拉布拉多的声音日志的交叉井机器学习预测
Bahare Zare1, Mohammad Mojammel Huque2, Lesley A James2
1Department of Computer Science, Memorial University of Newfoundland, St. John's, NL, Canada.
Scientific reports
|January 15, 2026

概括
使用非声波日志预测压缩缓慢 (DTCO) 可以节省成本并改善现场规划. XGBoost模型实现了准确的盲目交叉井预测,证明了无泄漏特征工程的有效性.
科学领域:
- 地质物理学 地质物理学
- 石化物理学 石化物理学
- 机器学习在地球科学中的应用
背景情况:
- 压缩速度缓慢 (DTCO) 对于地震解释和水库表征至关重要.
- 获取声音日志是昂贵的,可能会导致数据缺口.
- 从非声波日志预测DTCO提供了一个具有成本效益的替代方案和数据缺口填补解决方案.
研究的目的:
- 为了评估盲目交叉井DTCO预测,使用严格的无泄漏,只有特征的策略.
- 为了比较随机森林 (RF),极端梯度增强 (XGBoost) 和BiLSTM模型的性能.
- 确定推动成功跨井DTCO预测的关键因素.
主要方法:
- 开发了一个无泄漏的预测管道,使用非声波日志的因果滞后窗口,不包括声波数据.
- 实现了确定性深度调节,相对深度特征,多尺度深度衍生和等级聚合特征选择.
- 采用了时间意识验证,并比较了RF,XGBoost和BiLSTM模型家族.
主要成果:
- 使用20个预测器和10个样本滞后的调整XGBoost实现了R2的[公式:见文本],MAE的[公式:见文本]和RMSE的[公式:见文本]用于交叉井预测 (井1到井2).
- 在反向方向 (井2到井1) 的表现较低,表明井间分布的转移.
- 射频显示出竞争性表现,而BiLSTM在这些数据集上表现不佳.
结论:
- 严格的泄漏控制,深度感知特征工程和原则性的特征选择对于准确的交叉井DTCO预测至关重要.
- 像XGBoost这样的基于树的合集为伪声波日志预测提供了强大的,数据效率高的基线.
- 这种方法支持通过可靠的DTCO预测降低收购成本和加强现场规划.
更多相关视频
 06:22
Machine Learning-Based Cough Tone Classification: Diagnostic Exploration of Chronic Obstructive Pulmonary Disease and Respiratory Tract Infections
Published on: September 19, 2025
435
 05:48
Author Spotlight: Investigating the Impact of Emotional Prosodies on Voice Recognition and Perception
Published on: August 9, 2024
2.0K
相关概念视频
 01:03
Prediction Intervals
3.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.3K
 01:30
Classification of Signals
1.3K
In signal processing, signals are classified based on various characteristics: continuous-time versus discrete-time, periodic versus aperiodic, analog versus digital, and causal versus noncausal. Each category highlights distinct properties crucial for understanding and manipulating signals.
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
1.3K
 01:16
Estimating Population Mean with Known Standard Deviation
9.6K
To construct a confidence interval for a single unknown population mean μ, where the population standard deviation is known, we need sample mean as an estimate for μ and we need the margin of error. Here, the margin of error (EBM) is called the error bound for a population mean (abbreviated EBM). The sample mean is the point estimate of the unknown population mean μ.
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
The confidence interval estimate will have the form as follows:
(point estimate - error bound, point estimate +...
9.6K
 01:07
End Point Prediction: Gran Plot
1.2K
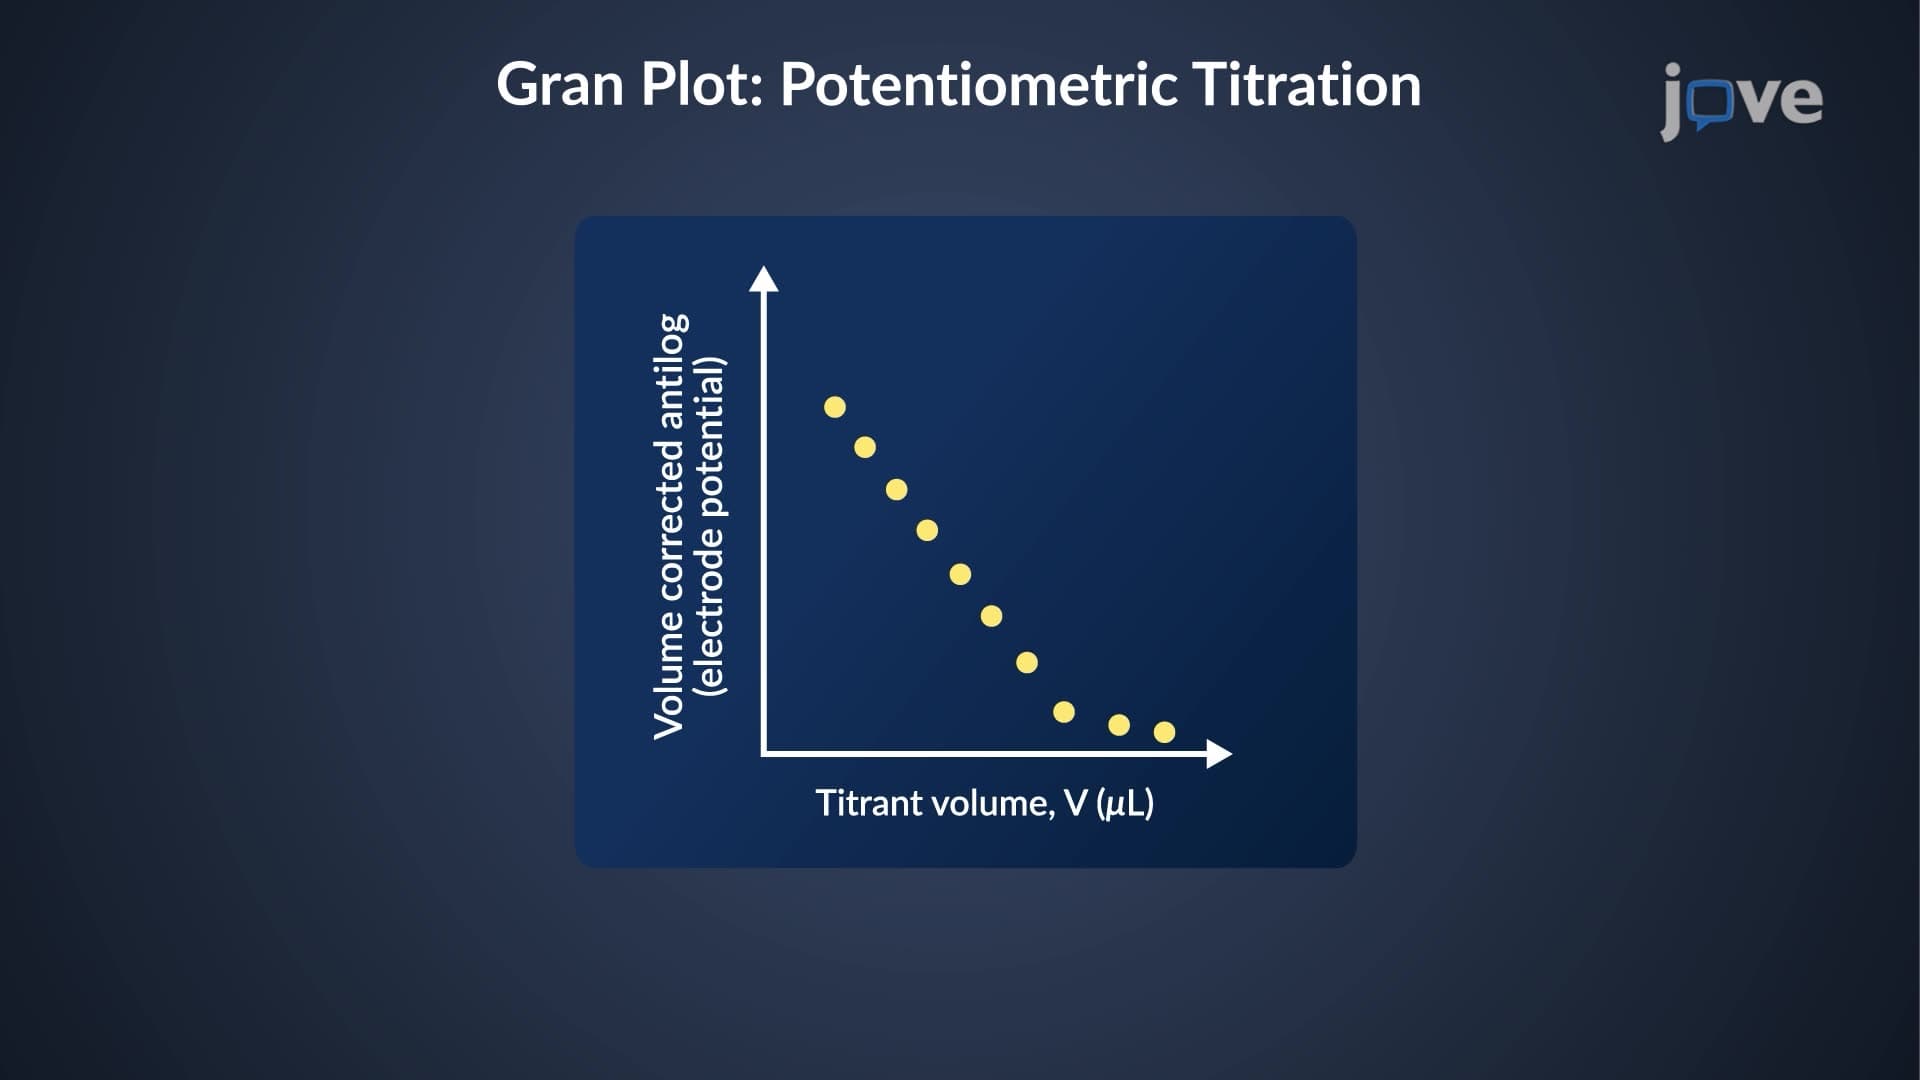
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
1.2K
 01:08
Determination of Expected Frequency
2.5K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.5K