
大型语言模型聊天机器人中的参考准确性:固有的错误信息的指标?
Małgorzata Pastucha1,2, Henryk Skarżyński2,3, Krzysztof Kochanek1,2
1Department of Experimental Audiology, Institute of Physiology and Pathology of Hearing, Warsaw, Poland.

概括
测试大型语言模型 (LLM) 聊天机器人对参考准确性的测试揭示了严重的错误信息. 网络搜索的ChatGPT-4.1表现最好,突出了在学术和临床环境中对AI工具改进的需要.
科学领域:
- 人工智能的人工智能
- 医疗信息学 医疗信息学
- 图书统计学 图书统计学
背景情况:
- 大型语言模型 (LLM) 和人工智能工具越来越多地用于学术研究和临床决策.
- 评估LLM提供的引用的准确性对于识别错误信息至关重要.
- 验证文献数据提供了一种可量化的方法来评价人工智能错误信息水平.
研究的目的:
- 为了比较不同版本的ChatGPT和Gemini聊天机器人的参考准确性.
- 评估AI生成的参考文献的可靠性,用于学术和临床使用.
- 建立一个评级AI错误信息在文献检索中的基准.
主要方法:
- 测试了六个聊天机器人版本 (3 ChatGPT, 3 Gemini).
- 聊天机器人提供了25个高度引用的耳鼻喉科主题的参考资料.
- 总共有1947个参考文献与PubMed,科学网络和谷歌学者进行了准确性验证.
主要成果:
- 常见的错误包括错误的作者名称和DOI号码.
- 使用网络搜索的ChatGPT-4.1获得了最高的准确度 (51%),其次是Gemini 2.5 Pro (41%).
- 具有网络搜索功能的聊天机器人表现优于没有网络搜索功能的聊天机器人;引用率较高的主题的错误率较低.
结论:
- 人工智能驱动的文献检索需要显著的改进,以实现可靠的学术和临床整合.
- 参考准确性测试为评估LLM错误信息提供了有价值的指标.
- 当前的人工智能工具在科学和医学领域广泛采用之前需要经过仔细的验证.
相关概念视频
 01:28
Accuracy, limits, and approximation
1.1K
Accuracy, limits, and approximations are common in many fields, especially in engineering calculations. These concepts are imperative for ensuring that a given value is as close as possible to its true value.
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
1.1K
 02:07
Improving Translational Accuracy
3.6K
3.6K
02:07Improving Translational Accuracy
14.1K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
14.1K
 01:52
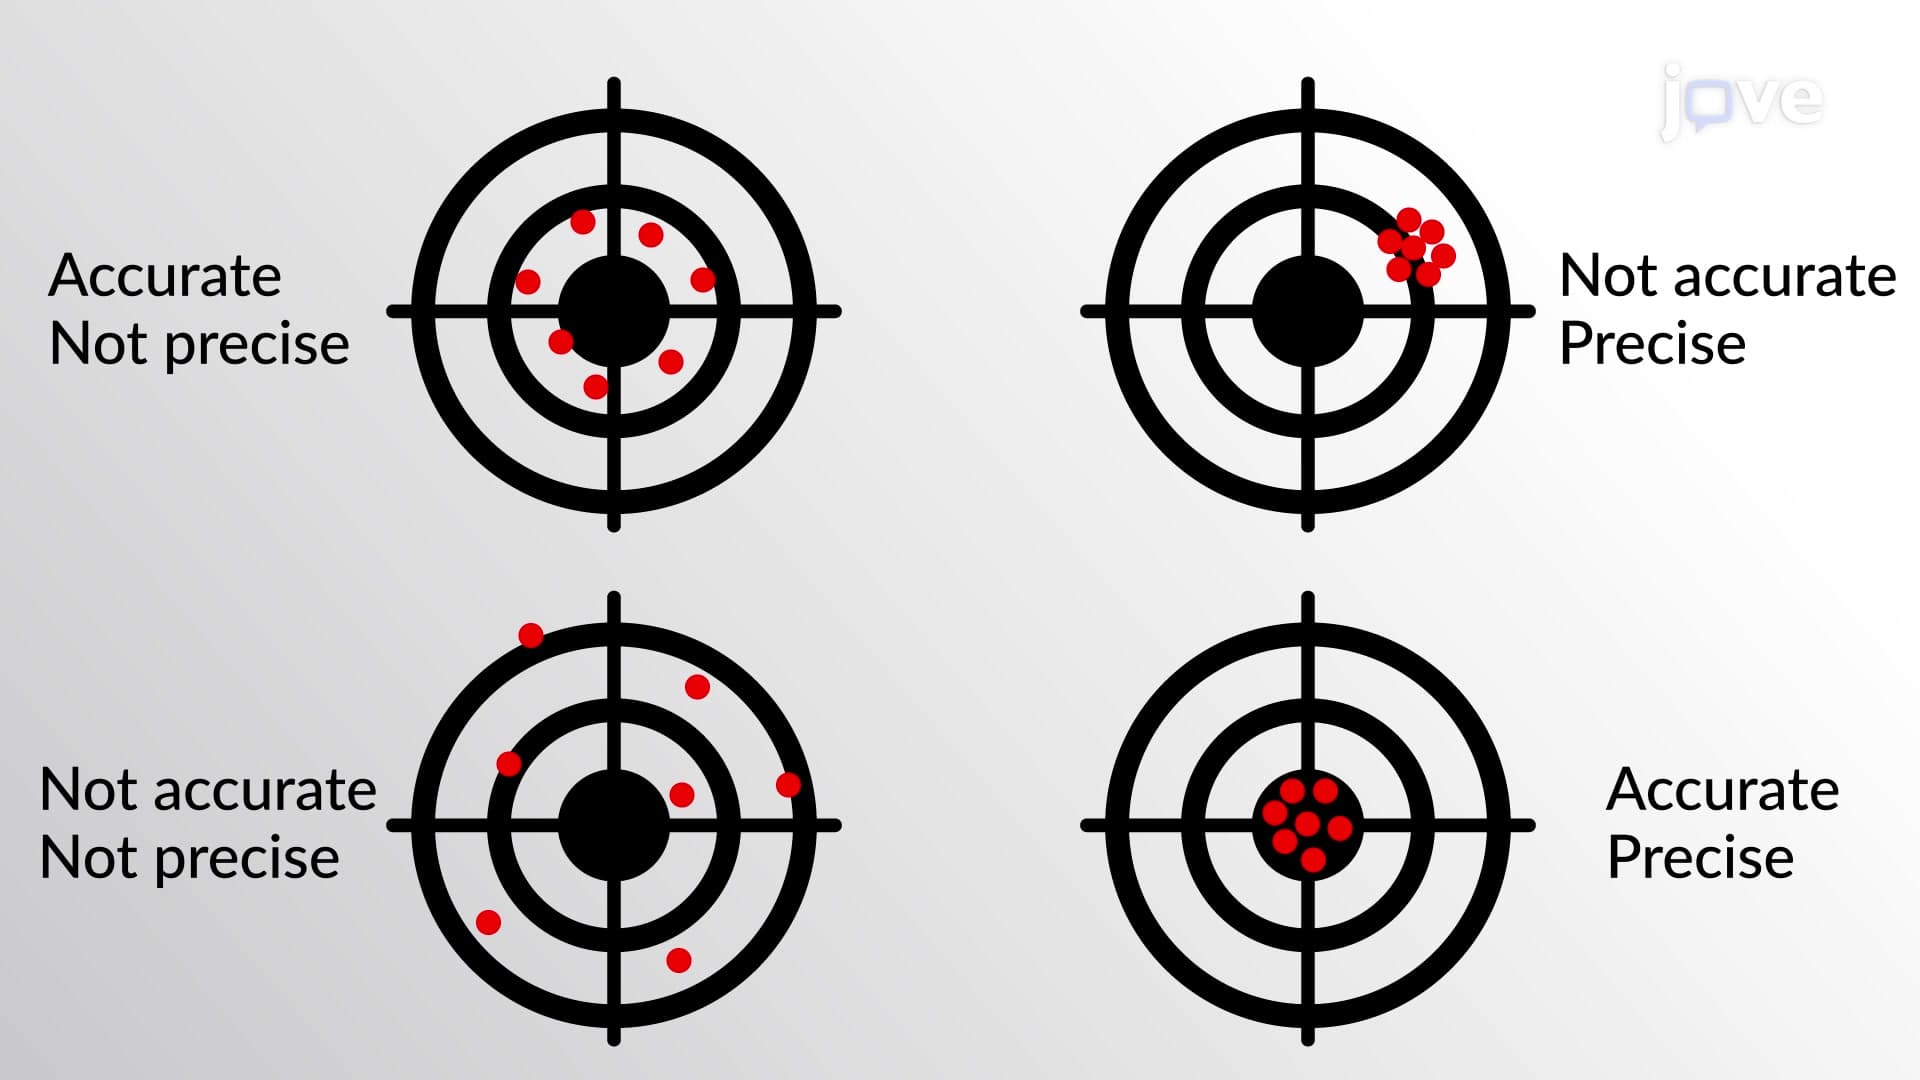
Accuracy and Precision
14.0K
Scientists typically make repeated measurements of a quantity to ensure the quality of their findings and to evaluate both the precision and the accuracy of their results. Measurements are said to be precise if they yield very similar results when repeated in the same manner. A measurement is considered accurate if it yields a result that is very close to the true or the accepted value. Precise values agree with each other; accurate values agree with a true value. Highly accurate...
14.0K
 02:16
Stereotype Content Model
15.3K
The Stereotype Content Model (SCM) was first proposed by Susan Fiske and her colleagues (Fiske, Cuddy, Glick & Xu, 2002; see also Fiske, 2012 and Fiske, 2017). The SCM specifies that when someone encounters a new group, they will stereotype them based on two metrics: warmth—or that group’s perceived intent, and how likely they are to provide help or inflict harm—and competence—or their ability to carry out that objective. Depending on the warmth-competence...
15.3K
 01:14
Understanding Deception
152
Deception is a pervasive aspect of human communication. Empirical studies have shown that most individuals engage in some form of deceit on a daily basis, with approximately 20% of social exchanges involving deceptive elements. Lying follows a developmental trajectory, peaking during adolescence and declining with age, possibly due to the maturation of cognitive control and social accountability.Cognitive and Social Factors in Deception DetectionDespite its prevalence, accurately detecting...
152