
在患有PTSD的个体中,情绪处理和调节的离散偏差:P300和LPP反应差异的证据
Carine El Jamal1, Nicholas J Santopetro1, Danielle M Morabito1,2
1Florida State University, Tallahassee, Florida, USA.
Psychophysiology
|January 23, 2026

概括
与没有创伤后应激障碍 (PTSD) 的创伤后应激障碍 (PTSD) 患者相比,在情绪调节任务期间,创伤后应激障碍 (PTSD) 患者表现出神经活动的改变,特别是P300和LPP早期幅度的减少,与没有创伤后应激障碍的个体相比. 这些神经差异与PTSD症状相关,如过度兴奋和避免.
科学领域:
- 神经科学是一个神经科学.
- 精神病学是一个精神病学.
- 心理学 心理学 心理学
背景情况:
- 创伤后应激障碍 (PTSD) 与神经缺陷有关,但研究往往忽略了那些没有患上创伤后应激障碍的人.
- 了解患有PTSD的人与没有PTSD的人的神经差异对于识别风险标志物和理解病因至关重要.
- 与事件相关潜力 (ERP) 和特定的PTSD症状集群之间的关联仍未得到充分研究.
研究的目的:
- 用ERP (P300,早期LPP,晚期LPP) 来比较患有PTSD的个体和没有PTSD的创伤暴露个体之间的情绪反应和调节.
- 调查ERP特定组件和PTSD症状集群 (过度兴奋,避免) 之间的关系.
主要方法:
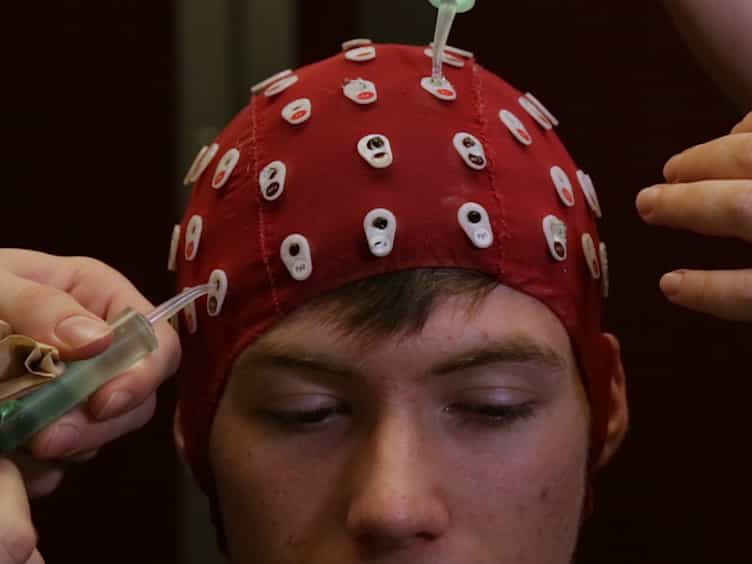
- 利用情绪调节任务通过ERP记录神经活动.
- 在PTSD (n=49) 和非PTSD受创伤暴露 (n=85) 组之间分析了P300,早期LPP和晚期LPP振幅的差异.
- 与PTSD症状集群相关联的ERP发现.
主要成果:
- 患有PTSD的个体在消极图像抑制期间表现出降低的P300幅度,并在所有情绪调节条件中减少早期LPP.
- 在抑制过程中减弱的P300和在增强过程中增加的P300与PTSD有独特的关联.
- 抑制P300的缺陷与回避症状有关,而较大的P300幅度与过度兴奋症状有关.
结论:
- 患有PTSD的人在早期情绪表达和调节方面表现出缺陷,特别是在增强和抑制P300组件方面,与受创伤影响的对照人相比.
- 这些神经缺陷可能反映了与PTSD特征的过度兴奋和回避症状相关的潜在病理生理学.
- 这些发现突出了PTSD发展的潜在神经风险标志物,并为我们了解疾病的病因提供了信息.
相关概念视频
 02:55
The Evidence for Evolution
47.7K
Genetic variations accumulating within populations over generations give rise to biological evolution. Evolutionary changes can result in the formation of novel varieties and entire new species. These changes are responsible for the diverse forms of life inhabiting the planet. The evidence for evolution suggests that all living organisms descended from common ancestors.
47.7K
 02:41
Chromatin Structure Regulates pre-mRNA Processing
8.1K
In eukaryotic cells, nascent mRNA transcripts need to undergo many post-transcriptional modifications to reach the cell cytoplasm and translate into functional proteins. For a long time, transcription and pre-mRNA processing were considered two independent events that occur sequentially in the cell. However, it has now been well established that transcription and pre-mRNA processing are two simultaneous processes that are precisely regulated inside the cell.
The chromatin structure, especially...
The chromatin structure, especially...
8.1K
 02:32
Variation: Normal Distribution, Range, and Standard Deviation
27.0K
In the field of psychology, there are several ways to organize measurements of a trait, feature, or characteristic (i.e., variables). Qualitative data, such as ethnicity, can be tabulated into a frequency count to provide information about the proportion, as well as the variety of groups in a sample or population. On the other hand, researchers can perform a wider set of calculations on quantitative data. The mean, mode, and median, for instance, are central tendency measures to identify a...
27.0K
 01:31
Regulation of the Unfolded Protein Response
2.9K
Inositol-requiring kinase one or IRE1 is the most conserved eukaryotic unfolded protein response (UPR) receptor. It is a type I transmembrane protein kinase receptor with a distinctive site-specific RNase activity. As the binding mechanics of the misfolded proteins with the N-terminal domain of IRE-1 are unclear, three binding models — direct, indirect, and allosteric -- are proposed for receptor activation. Nevertheless, it is known that once a misfolded protein associates with IRE1, it...
2.9K
 01:10
Standard Deviation
27.6K
The most commonly used measure of variation is the standard deviation. It is a numerical value measuring how far data values are from their mean. The standard deviation value is small when the data are concentrated close to the mean, exhibiting slight variation or spread. The standard deviation value is never negative, it is either positive or zero. The standard deviation is larger when the data values are more spread out from the mean, which means the data values are exhibiting more variation.
27.6K
 01:13
Mean Absolute Deviation
3.3K
The mean absolute deviation is also a measure of the variability of data in a sample. It is the absolute value of the average difference between the data values and the mean.
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
3.3K