机器学习模型在ACDF后预测结果中的表现: 443 000名患者的系统审查和元分析
Lucas P Mitre1, Rômulo S Sanglard2, Ethan D L Brown3
1Department of Radiation Oncology, UT Southwestern Medical Center, Dallas, TX, USA.
Global spine journal
|January 23, 2026

概括
机器学习模型可以预测前椎间盘切除和融合 (ACDF) 后的结果. 后勤回归和提振模型表现出强的性能,而神经网络和内核方法在特定的ACDF预测方面表现出色.
科学领域:
- 脊柱手术研究结果研究结果
- 机器学习在医疗保健中的应用.
- 预测建模在整形外科的预测建模.
背景情况:
- 现有关于机器学习 (ML) 对前椎间盘切除和融合 (ACDF) 的研究缺乏直接比较.
- 不同质的数据集,特征和指标阻碍了在ACDF中对ML模型性能的解释性和比较.
- 需要进行系统性审查和元分析,以便对预测ACDF结果的ML模型进行对比比较.
研究的目的:
- 直接比较各种机器学习模型在前椎间盘切除和融合 (ACDF) 结果的预测性能.
- 确定哪些ML算法为不同的ACDF相关结果提供了最强大和最可概括的歧视.
- 提供证据支持将ML驱动的风险计算器集成到ACDF的外科手术工作流程中.
主要方法:
- 按照PRISMA指南进行的系统审查和元分析,搜索主要数据库到2024年12月.
- 确定了26项研究 (n=443,445名患者),用于开发ACDF结果的ML模型.
- 分类算法 (逻辑回归,基于树的,增强组合,内核方法,NN) 和使用随机效应模型估计的聚合AUC和准确性.
主要成果:
- 总体歧视因结果而异,从0.59 (主要并发症) 到0.81 (相邻水平疾病).
- 后勤回归在预测不良出院 (AUC 0.76),再接收/再干预 (0.68) 和护理成本 (0.83) 中表现出色.
- 增强组合在预测血栓栓塞事件 (AUC 0.74),阿片类药物处方的NN (AUC 0.80) 和相邻水平疾病 (AUC 0.81) 和相邻水平融合的内核方法 (AUC 0.97) 中表现出强度.
结论:
- 后勤回归和梯度增强模型在各种ACDF结果中提供可靠的歧视.
- 神经网络和内核方法在特定的ACDF终点上表现出特殊的优势.
- 这些发现支持基于ML的风险预测工具的未来验证和整合到ACDF外科手术期间护理中.
关键词:
ACDF ACDF ACDF ACDF ACDF ACDF ACDF ACDF ACDF ACDF ACDF ACDF进行元分析.深度学习是一种深度学习.机器学习算法的算法在术后的结果.预测分析 预测分析风险分层的分层是风险分层.更多相关视频
 04:09
Predicting Treatment Response to Image-Guided Therapies Using Machine Learning: An Example for Trans-Arterial Treatment of Hepatocellular Carcinoma
Published on: October 10, 2018
8.7K
 06:19
Constructing and Visualizing Models using Mime-based Machine-learning Framework
Published on: July 22, 2025
2.4K
相关概念视频
 02:24
Predicting Reaction Outcomes
10.4K
Kinetics describes the rate and path by which a reaction occurs. In contrast, thermodynamics deals with state functions and describes the properties, behavior, and components of a system. It is not concerned with the path taken by the process and cannot address the rate at which a reaction occurs. Although it does provide information about what can happen during a reaction process, it does not describe the detailed steps of what appears on an atomic or a molecular level. On the other hand,...
10.4K
 01:30
Simplified Synchronous Machine Model
759
The Synchronous Machine Model is a fundamental tool in analyzing and ensuring the transient stability of power systems. This model simplifies the representation of a synchronous machine under balanced three-phase positive-sequence conditions, assuming constant excitation and ignoring losses and saturation. The model is pivotal for understanding the behavior of synchronous generators connected to a power grid, particularly during transient events.
In this model, each generator is connected to a...
In this model, each generator is connected to a...
759
 01:24
Wind Turbine Machine Models
570
In the growing field of wind energy, incorporating wind turbine models into transient stability analysis is essential. Induction and synchronous machines are the primary models used, with induction machines being prevalent due to their simplicity and reliability.
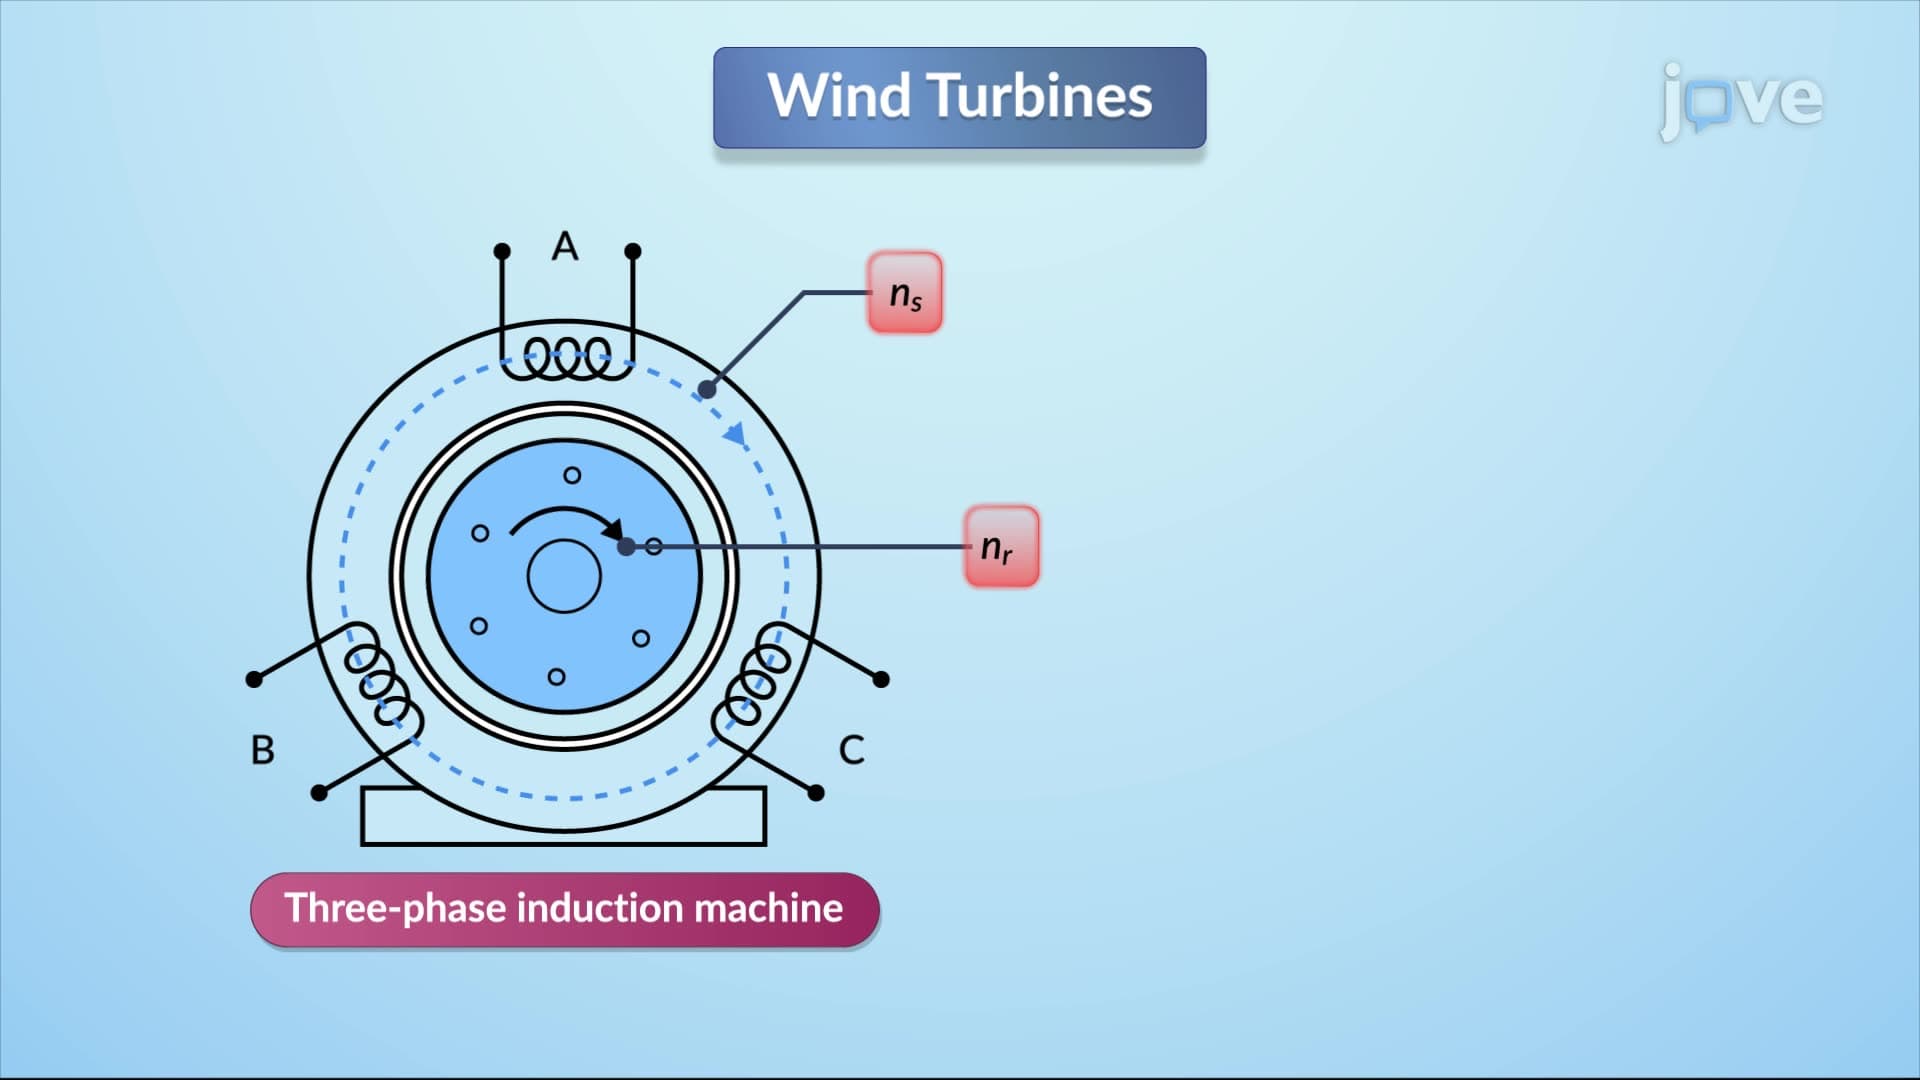
Induction machines interact through the rotating magnetic field generated by the stator and the rotor. The key parameter is slip, which is the difference between synchronous speed and rotor speed relative to synchronous speed. Slip is...
Induction machines interact through the rotating magnetic field generated by the stator and the rotor. The key parameter is slip, which is the difference between synchronous speed and rotor speed relative to synchronous speed. Slip is...
570
 01:10
Review and Preview
8.3K
In statistics, several tools are used to interpret the data. Measures of central tendency represent the characteristics of the data, such as mean, median, and mode. Additionally, measures of variance like standard deviation and range are used to find the spread of data from the mean. Relative standing measures the distance between data locations. Commonly used measures of relative standings are percentile, z score, and quartiles.
Percentiles are a type of fractile that partition data into...
Percentiles are a type of fractile that partition data into...
8.3K
 01:13
Review and Preview
10.9K
Data are individual items of information obtained from a population or sample. Data may be classified as qualitative (categorical), quantitative continuous, or quantitative discrete. Because it is not practical to measure the entire population in a study, researchers use samples to represent the population. A random sample is a representative group from the population chosen by using a method that gives each individual in the population an equal chance of being included in the sample. Random...
10.9K
 02:27
Predicting Molecular Geometry
45.6K
VSEPR Theory for Determination of Electron Pair Geometries
45.6K