相关实验视频
Updated: Jan 28, 2026
10:34
Ultra-long Read Sequencing for Whole Genomic DNA Analysis
Published on: March 15, 2019
23.9K
正方形斑点鹿的基因组序列,Chrysops viduatus (法布里西乌斯,1794) (Diptera:Tabanidae) 的基因组序列
Erica McAlister1, Ryan Mitchell2, Olga Sivell1
1Natural History Museum, London, England, UK.
Wellcome open research
|January 26, 2026

概括
我们向您介绍的是正方形斑点鹿 (Chrysops viduatus) 的第一个基因组组. 这种基因组资源有助于生物多样性研究和对英国和爱尔兰的虫物种的理解.
科学领域:
- 基因组学就是基因组学.
- 昆虫学 昆虫学是一门学科.
- 生物多样性研究的研究.
背景情况:
- 方形斑点鹿 (Chrysops viduatus) 是Diptera类的一种昆虫.
- 参考基因组对于理解真核生物多样性至关重要.
研究的目的:
- 为了生成一个高质量的基因组组合的金龙 viduatus.
- 为达尔文生命之树项目的目标 - - 编目英国和爱尔兰的生物多样性做出贡献.
主要方法:
- 一个单独的雌性 Chrysops viduatus 的全基因组测序.
- 核和线粒体基因组的生物信息组装和支架.
主要成果:
- 实现了总基因组序列长度为312.35兆基的结果.
- 87.6%的组件成功地被支架成5个染色体伪分子.
- 线粒体基因组被组装成一个长度为16.08 kilobases.
结论:
- 这种基因组组合为Chrysops viduatus提供了有价值的基因组资源.
- 这些数据支持Diptera序列中正在进行的生物多样性和进化研究.
相关概念视频
 01:00
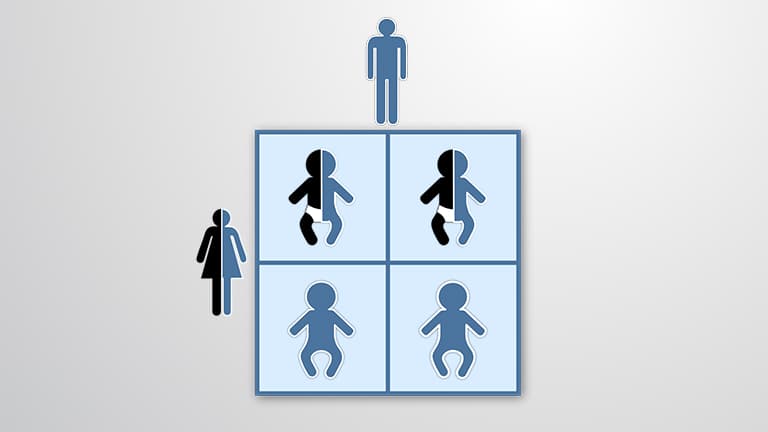
Punnett Squares
125.3K
Overview
125.3K
 02:02
Genomics
40.3K
Genomics is the science of genomes: it is the study of all the genetic material of an organism. In humans, the genome consists of information carried in 23 pairs of chromosomes in the nucleus, as well as mitochondrial DNA. In genomics, both coding and non-coding DNA is sequenced and analyzed. Genomics allows a better understanding of all living things, their evolution, and their diversity. It has a myriad of uses: for example, to build phylogenetic trees, to improve productivity and...
40.3K
 00:57
Root Mean Square
3.8K
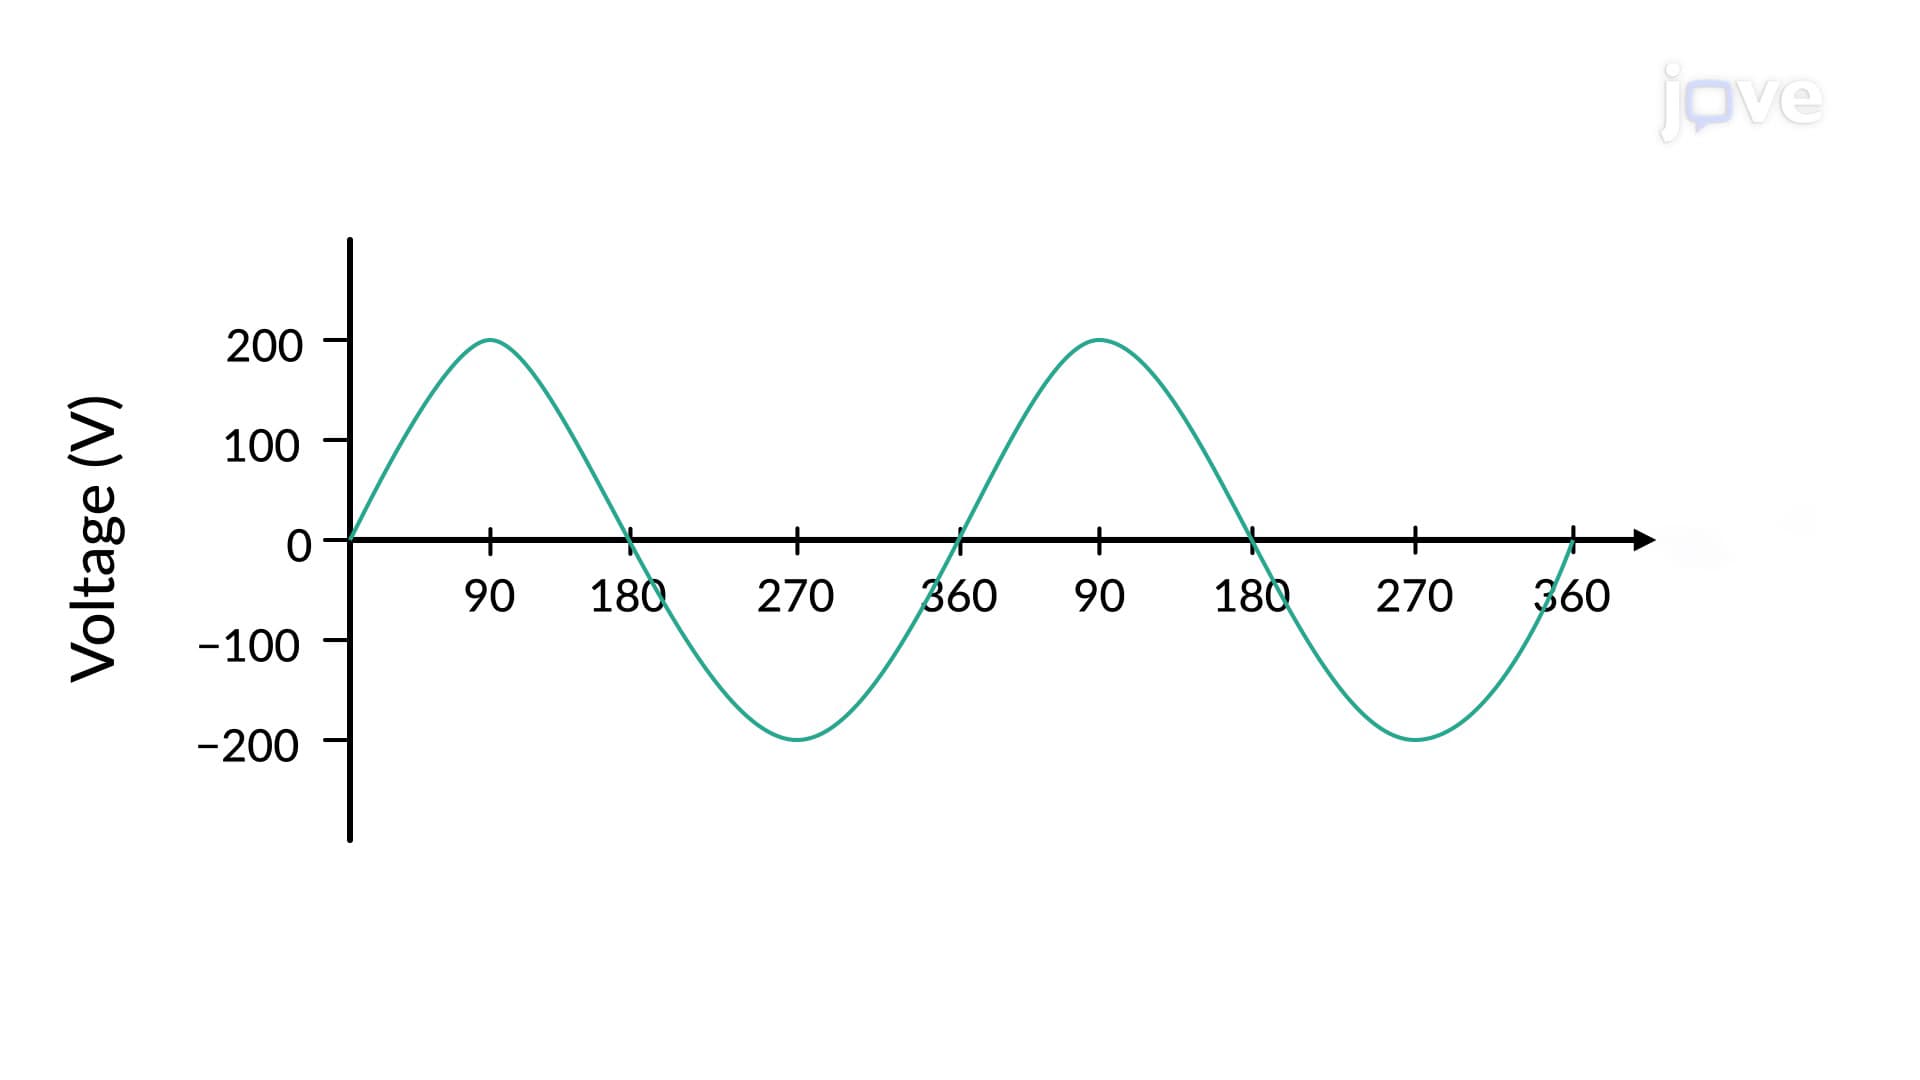
If in an experiment, data values have a probability of being both positive and negative, neither the arithmetic mean, the geometric mean, nor the harmonic mean can be used to calculate the central tendency of the data set. In particular, if the positive and negative values are equally likely, the arithmetic mean is close to zero.
For example, consider the velocity of gas molecules in a container. The gas molecules are moving in different directions, which might impart positive and negative...
For example, consider the velocity of gas molecules in a container. The gas molecules are moving in different directions, which might impart positive and negative...
3.8K
 02:46
Chi-square Analysis
43.9K
The chi-square test is a statistical hypothesis test. It is used to check whether there is a significant difference between an expected value and an observed value. In the context of genetics, it enables us to either accept or reject a hypothesis, based on how much the observed values deviate from the expected values.
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
43.9K
 01:10
Chi-square Distribution
6.8K
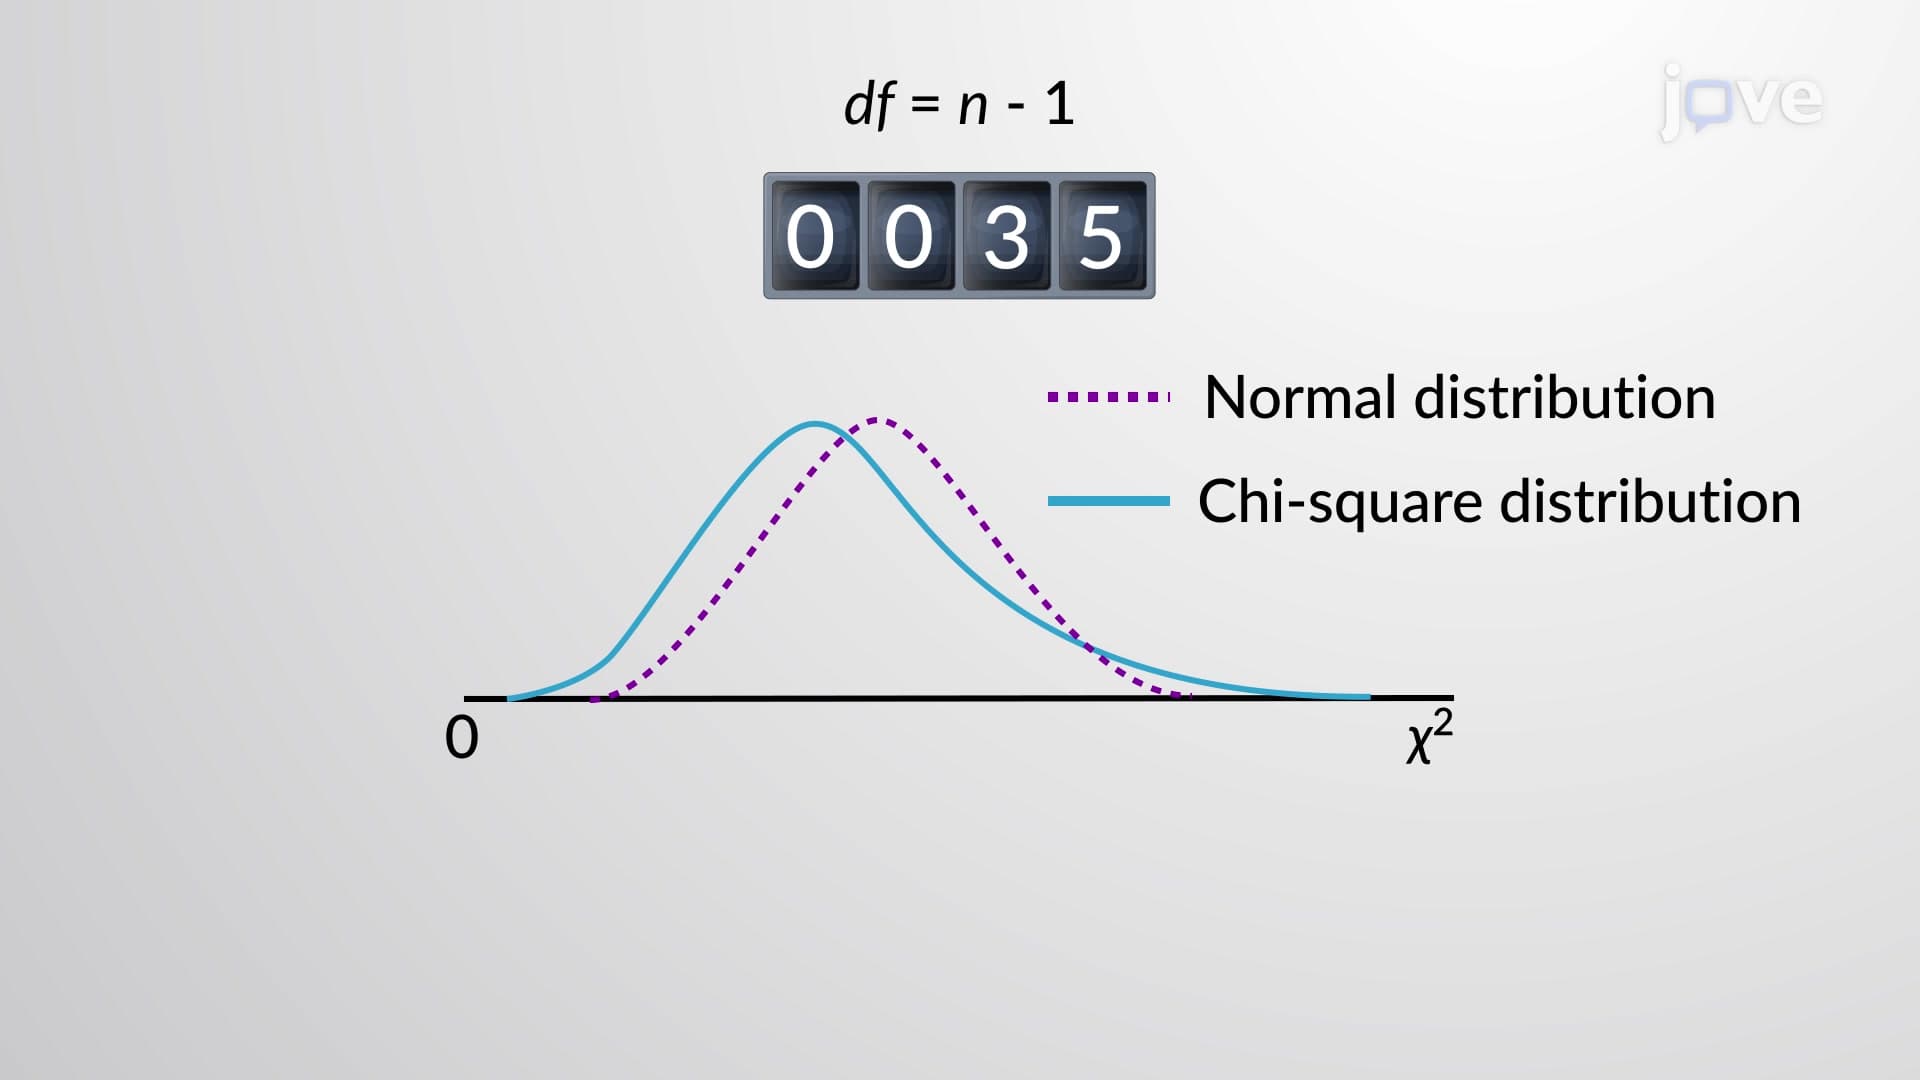
How does one determine if bingo numbers are evenly distributed or if some numbers occurred with a greater frequency? Or if the types of movies people preferred were different across different age groups or if a coffee machine dispensed approximately the same amount of coffee each time. These questions can be addressed by conducting a hypothesis test. One distribution that can be used to find answers to such questions is known as the chi-square distribution. The chi-square distribution has...
6.8K
 01:11
Residuals and Least-Squares Property
9.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
9.4K