在有系统和零星地缺少数据的情况下,对分类变量进行分层归算
1Department of Methodology and Statistics, https://ror.org/02jz4aj89Care and Public Health Research Institute (CAPHRI), Maastricht University, Maastricht, The Netherlands.
Research synthesis methods
|February 2, 2026

概括
本研究介绍了先进的等级归算方法,用于处理个人参与者数据元分析中缺少的分类数据. 新方法有效地解决了复杂的嵌套数据结构中的系统和零星缺失问题.
科学领域:
- 统计 统计 统计 统计
- 生物统计学 生物统计学
- 数据科学数据科学数据科学
背景情况:
- 定量证据综合经常结合来自多项研究的个体参与者数据 (IPD).
- 缺失的数据,无论是系统的还是零星的,在IPD元分析中都构成了重大挑战.
- 现有的多重归算 (MI) 方法需要对层次数据进行高级程序.
研究的目的:
- 将等级归算方法扩展到MICE框架内的分类变量.
- 在嵌套设计中适应系统和偶尔缺失的数据.
- 为复杂的缺失数据模式开发可靠的归算技术.
主要方法:
- 扩展对分类变量的等级归算方法.
- 开发一个接受-拒绝算法来处理数据的分类性质.
- 通过模拟研究进行评估,并将其应用于现实世界IPD数据集.
主要成果:
- 拟议的方法有效地处理系统性和偶尔缺少的分类数据.
- 接受-拒绝算法成功地解决了分类归因的挑战.
- 在病患者数据的IPD元分析中证明了实用性.
结论:
- 新的等级归算方法为IPD元分析中缺少的分类数据提供了可靠的解决方案.
- 这种方法提高了复杂数据的证据合成的准确性和可靠性.
- 适用于需要对层次和不完整数据集进行分析的各种领域.
相关概念视频
 01:11
How Data are Classified: Categorical Data
44.6K
A variable, usually notated by capital letters such as X and Y, is a characteristic or measurement that can be determined for each member of a population. Data are the actual values of variables. They may be numbers, or they may be words. Datum is a single value.
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
44.6K
 01:20
Random and Systematic Errors
14.9K
Scientists always try their best to record measurements with the utmost accuracy and precision. However, sometimes errors do occur. These errors can be random or systematic. Random errors are observed due to the inconsistency or fluctuation in the measurement process, or variations in the quantity itself that is being measured. Such errors fluctuate from being greater than or less than the true value in repeated measurements. Consider a scientist measuring the length of an earthworm using a...
14.9K
 01:11
Variability: Analysis
511
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
511
 01:09
Random Variables
17.8K
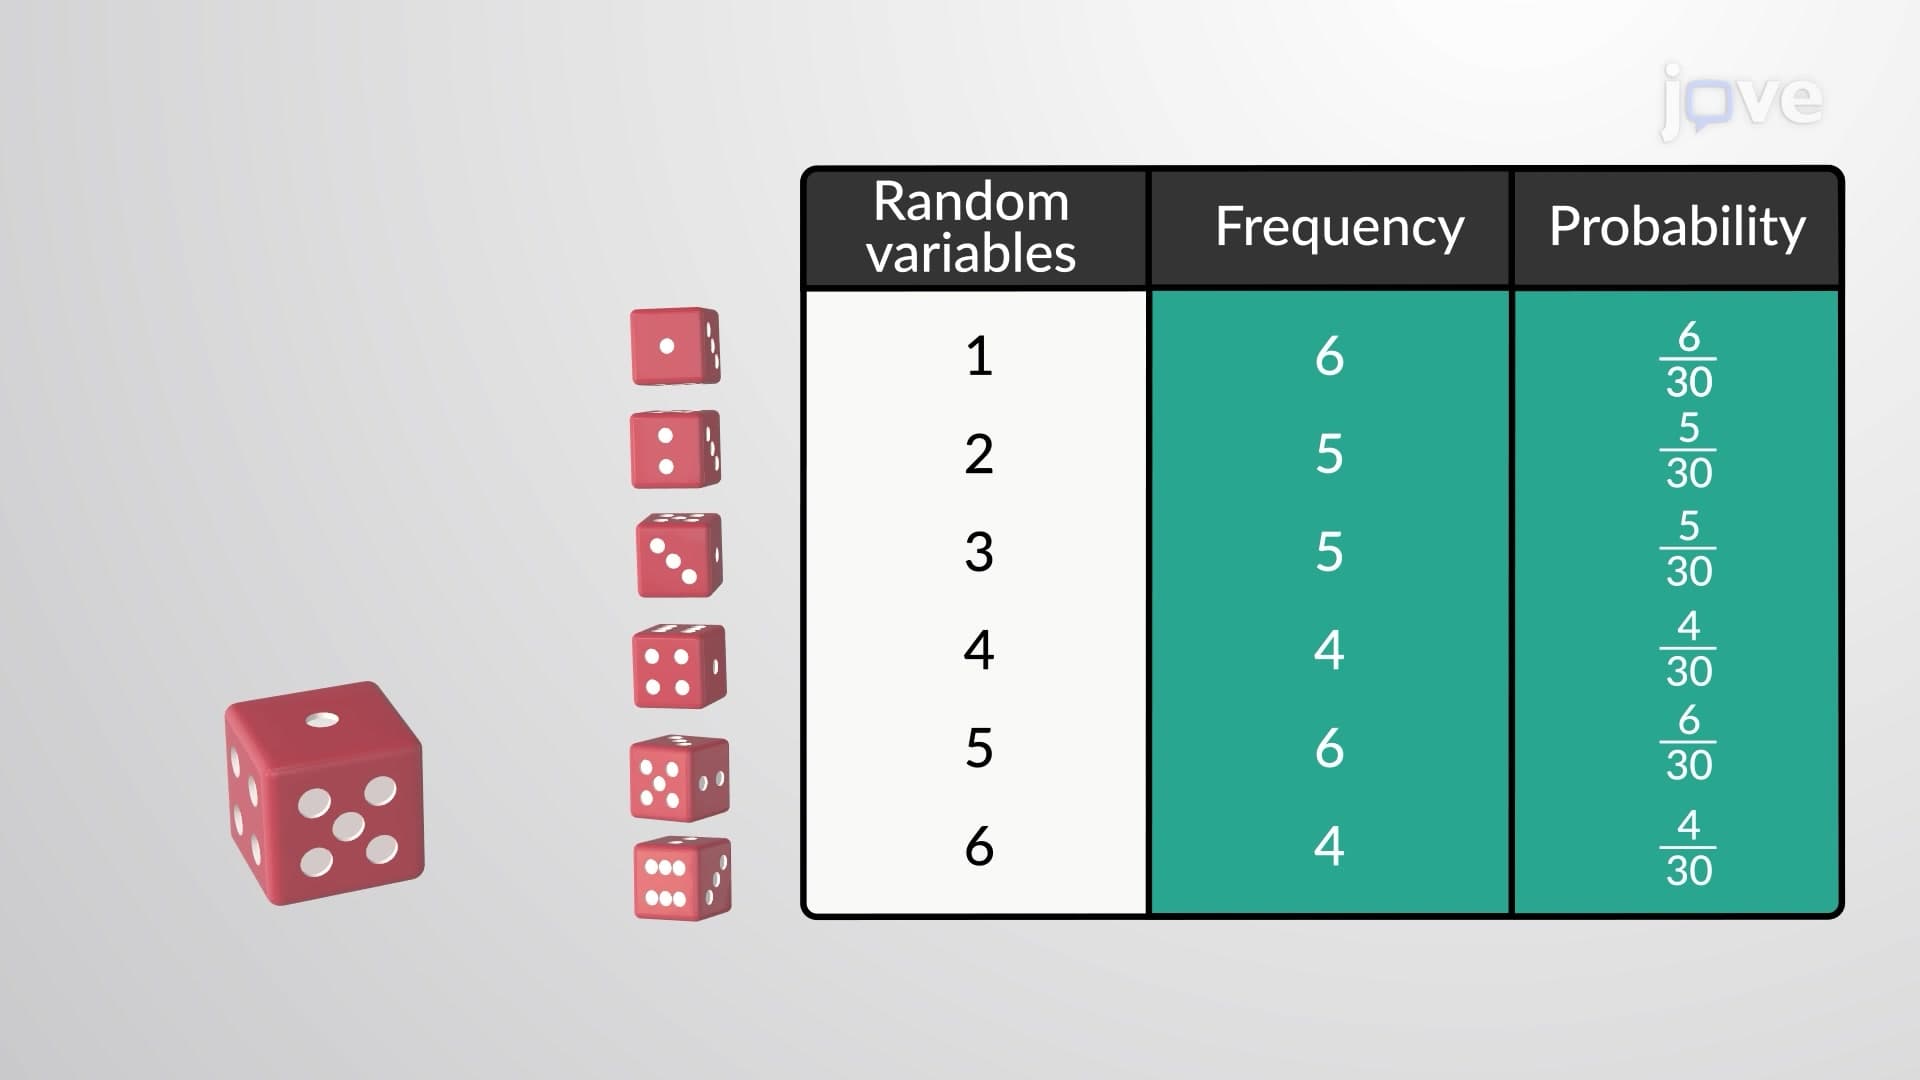
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
17.8K
 01:17
Systematic Sampling Method
13.3K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. Data are the result of sampling from a population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
Systematic sampling is one of the simplest methods...
Systematic sampling is one of the simplest methods...
13.3K
 01:30
Graphs of Equations in Two Variables
246
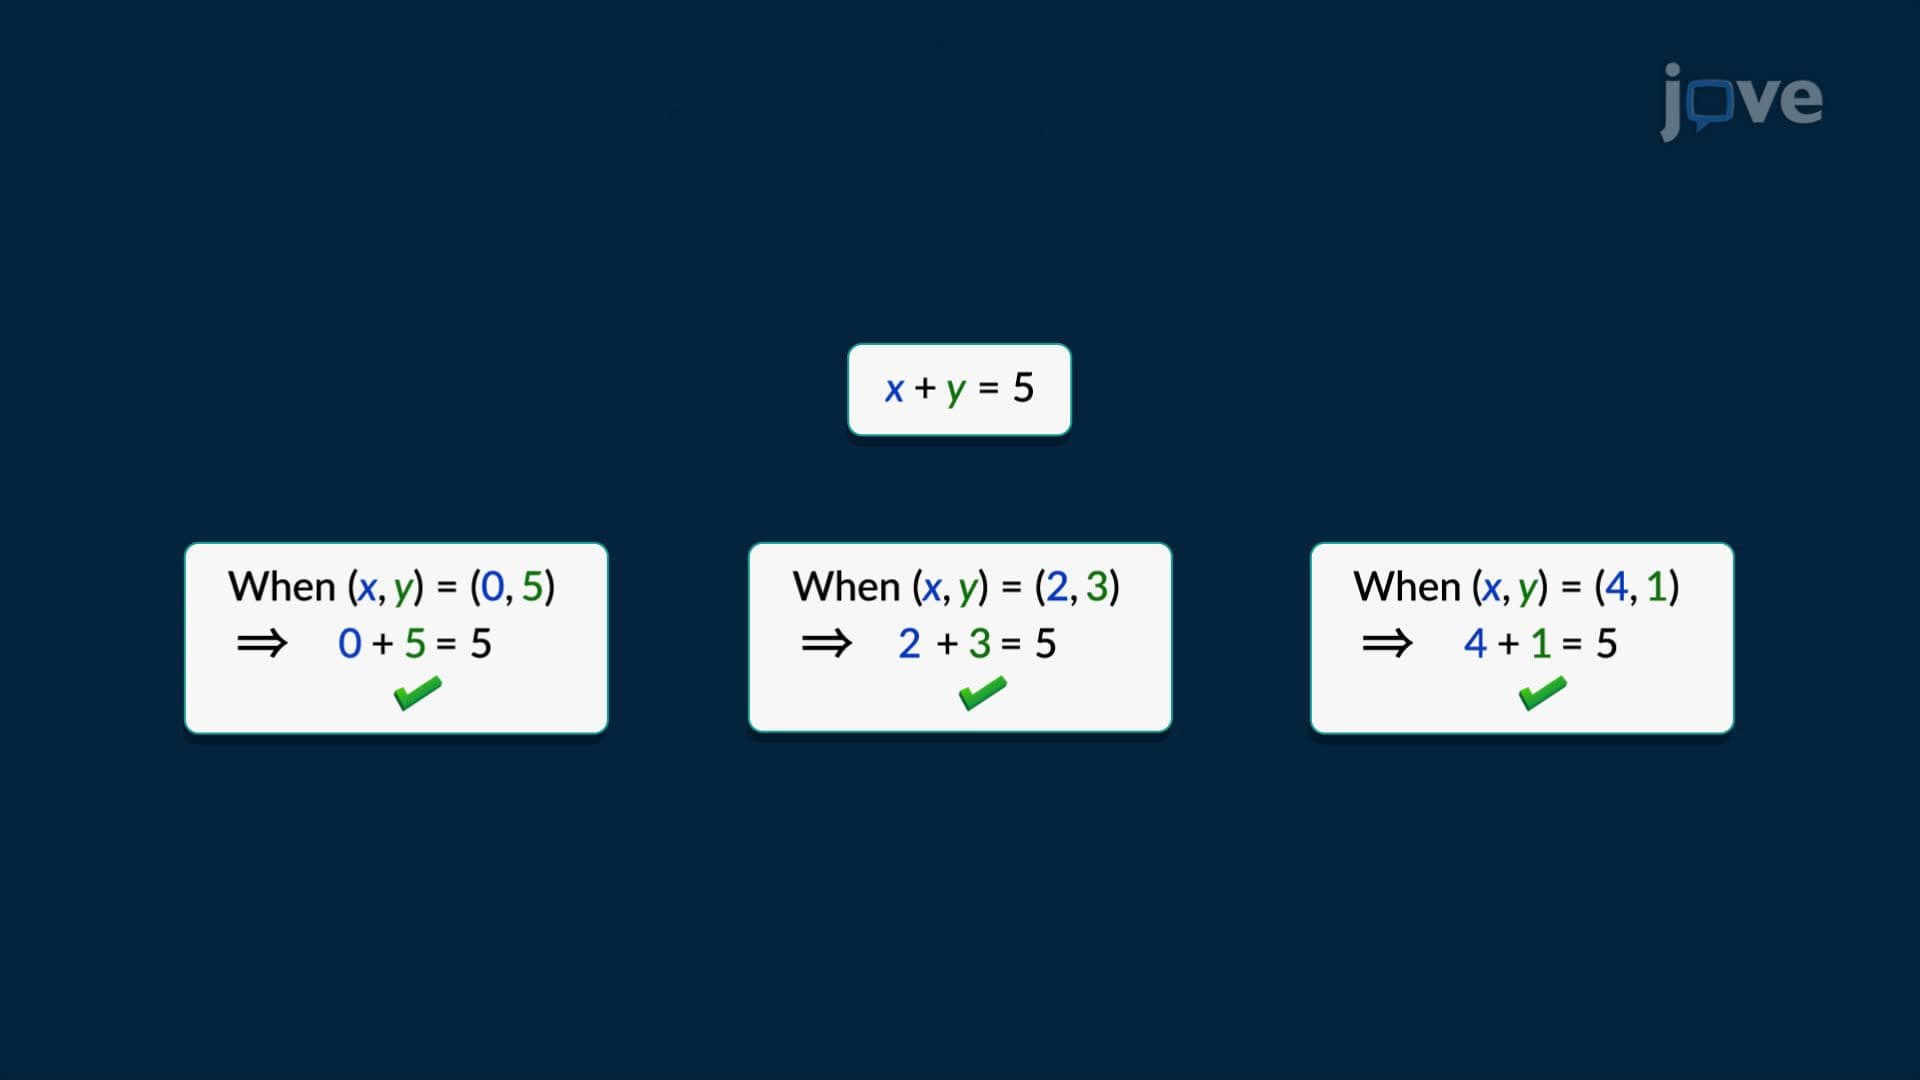
An equation with two variables, typically written in the form y = f(x) or Ax + By = C, describes a relationship between quantities represented by x and y. Each solution to such an equation is an ordered pair (x, y) that satisfies the equation when substituted. These pairs can be represented graphically to understand the variables' relationship visually.A common technique for constructing the graph of a two-variable equation is to create a value table. Begin by choosing several values for the...
246