
学习基因扰乱效应与变异性因果推理
Emily Liu1,2, Jiaqi Zhang1,2,3, Caroline Uhler1,2,3
1Department of Electrical Engineering and Computer Science, MIT, Cambridge, Massachusetts, United States of America.
PLoS computational biology
|February 2, 2026

概括
我们开发了一种混合计算模型,单细胞因果变异自编码器 (SCCVAE),用于预测遗传干扰后的基因表达变化. SCCVAE准确地预测了对未见的干扰的反应,推进了功能基因组学和治疗标识.
科学领域:
- 基因组学就是基因组学.
- 计算生物学 计算生物学
- 系统生物学 系统生物学
背景情况:
- Perturb-seq使得基因乱的高分辨率单细胞转录组分析成为可能.
- 当前的计算模型因过度拟合或过于简单的假设而难以将其概括为未见的扰动.
- 对基因调节网络 (GRN) 反应的准确预测对于功能基因组学和确定治疗点至关重要.
研究的目的:
- 开发一种新的计算模型,准确预测对基因扰动的转录组反应,特别是对未见的扰动.
- 将机械因果推理与深度学习相结合,以提高单细胞数据分析中的外推能力.
- 为解释和模拟单细胞水平的基因扰动效应提供一个强大的工具.
主要方法:
- 提出了一种混合方法,单细胞因果变异自编码器 (SCCVAE),将机械因果模型与变异深度学习相结合.
- 机械组件将扰动模型作为通过学习调节网络传播的转移干预.
- 将机械模型集成到一个变量自编码器框架中,以生成全面的转录基因反应.
主要成果:
- 与最先进的方法相比,SCCVAE在推断和预测对未见的遗传干扰的反应方面表现出卓越的表现.
- 该模型的潜空间促进了对观察到的扰动的功能扰动模块的识别.
- 通过SCCVAE,可以模拟不同透度的单基因淘汰实验.
结论:
- 在干扰后,SCCVAE提供了一种强大而准确的方法来预测基因调节网络动态.
- 混合方法克服了纯粹深度学习或机械模型的局限性,增强了对新扰的预测能力.
- 该工具促进了单细胞转录组数据的解释,并有助于发现治疗策略.
更多相关视频
 07:15
Determining the Likelihood of Variant Pathogenicity Using Amino Acid-level Signal-to-Noise Analysis of Genetic Variation
Published on: January 16, 2019
11.4K
 09:09
Protocol for Assessing the Relative Effects of Environment and Genetics on Antler and Body Growth for a Long-lived Cervid
Published on: August 8, 2017
8.0K
相关概念视频
 01:25
Genetic Variation
1.4K
Genetic variation is the diversity in DNA sequences found among individuals of the same species. This diversity is crucial for a species' survival because it helps organisms adapt to environmental changes. Genetic variation begins with fertilization, where an egg and sperm cell merge. Each of these cells carries 23 chromosomes, up to 46 in the fertilized egg. Chromosomes are long DNA strands that contain genes, the basic units of heredity.
Genes exist in different versions called alleles,...
Genes exist in different versions called alleles,...
1.4K
 01:21
Causality in Epidemiology
1.6K
Causality or causation is a fundamental concept in epidemiology, vital for understanding the relationships between various factors and health outcomes. Despite its importance, there's no single, universally accepted definition of causality within the discipline. Drawing from a systematic review, causality in epidemiology encompasses several definitions, including production, necessary and sufficient, sufficient-component, counterfactual, and probabilistic models. Each has its strengths and...
1.6K
 01:14
What is Variation?
18.5K
Apart from the measures of central tendency, distribution, outliers, and the changing characteristics of data with time, an important characteristic of any data set is its variation or spread. In some data sets, the data values are concentrated closely near the mean; in others, the data values are more widely spread out from the mean.
The range, standard deviation, standard error, and variance are the different measures of variation.
Range: The range is the difference between its maximum and...
The range, standard deviation, standard error, and variance are the different measures of variation.
Range: The range is the difference between its maximum and...
18.5K
 02:53
Conservative Site-specific Recombination and Phase Variation
6.8K
Because the DNA segments are cut and reorganized in a direction-specific manner, site-specific recombination has emerged as an efficient genetic engineering technique. Flippase and Cyclization recombinases or Flp and Cre, respectively, are two members of the tyrosine recombinase family derived from bacteriophages, that are used to mediate site-specific DNA insertions, deletions, and targeted expression of proteins in mammalian cell lines.
The recognition sites for Cre recombinase called LoxP...
The recognition sites for Cre recombinase called LoxP...
6.8K
 01:25
What is Population Genetics?
64.7K
A population is composed of members of the same species that simultaneously live and interact in the same area. When individuals in a population breed, they pass down their genes to their offspring. Many of these genes are polymorphic, meaning that they occur in multiple variants. Such variations of a gene are referred to as alleles. The collective set of all the alleles within a population is known as the gene pool.
64.7K
 01:19
Variation
8.0K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
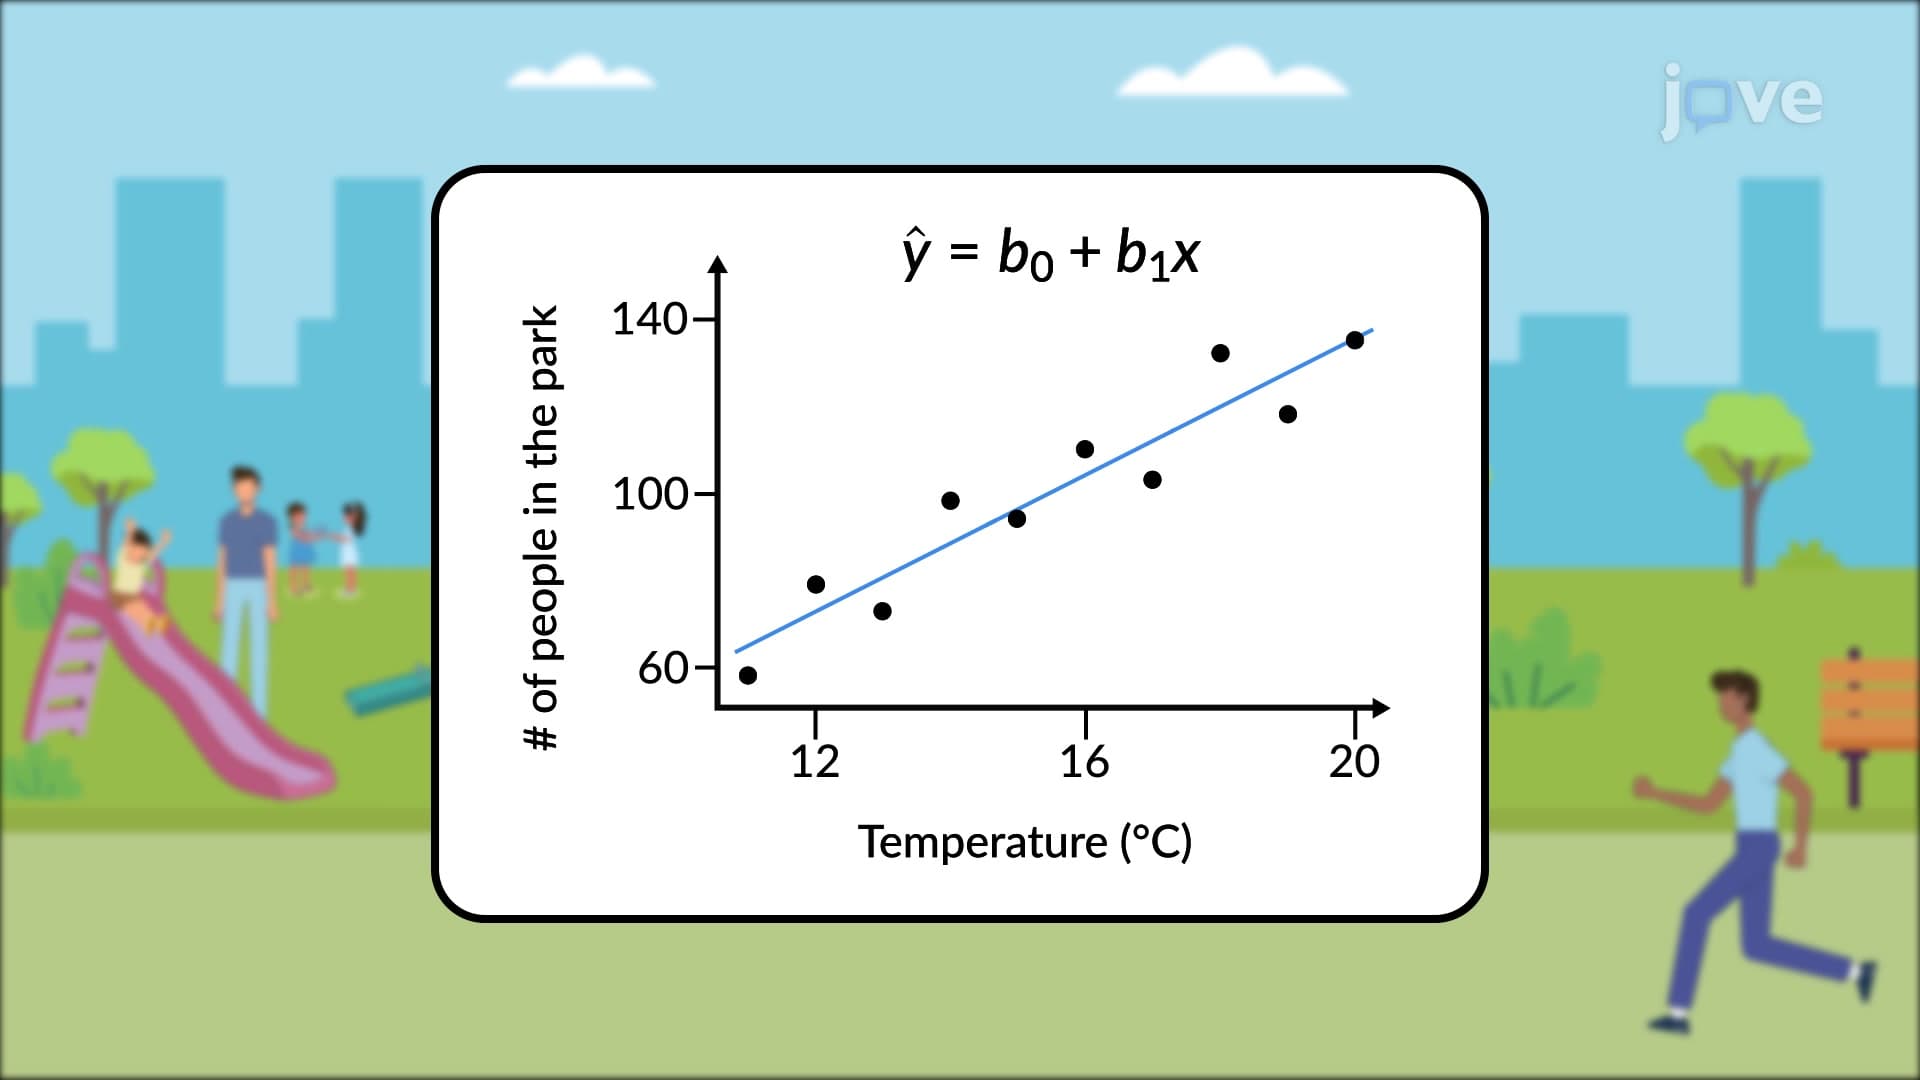
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
8.0K