临床亚组分层的血蛋白质组特征改善了心肌梗塞风险预测:SCORE2-Pro
Muye Tong1,2, Minchun Zhang1,2, Min Xu1,2
1Department of Endocrine and Metabolic Diseases, Shanghai Institute of Endocrine and Metabolic Diseases, Ruijin Hospital, Shanghai Jiao Tong University School of Medicine, Shanghai, China.
Cardiovascular diabetology
|February 3, 2026

概括
新的蛋白质组模型 (SCORE2-Pro) 在不同患者群体中显著改善了对心肌梗塞 (MI) 风险的预测. 这些特定于子组的蛋白质特征提高了比传统的临床风险得分更准确的准确性.
科学领域:
- 心血管疾病研究研究
- 蛋白质组学和生物标志物发现发现
- 个性化医学和风险分层
背景情况:
- 心肌梗塞 (MI) 是全球主要的死亡原因,不同人群的风险差异很大.
- 目前的风险分层工具,如SCORE2,在改进个性化MI风险预测方面存在局限性,特别是在特定的子组中.
- 亚组特异性血蛋白质学增强心脏病风险预测的潜力需要进一步调查.
研究的目的:
- 开发和验证用于心肌梗塞 (MI) 的临床亚组分层血蛋白质组预测模型.
- 评估子组特定的蛋白质组特征是否可以改善超越传统临床模型的MI风险预测.
- 确定有效的蛋白质面板和分层策略,以进行个性化MI风险评估.
主要方法:
- 开发了SCORE2-Pro模型,使用来自51010名英国生物库参与者的血蛋白质组学数据 (年龄在40-69岁之间).
- 根据关键临床因素对模型进行了分层:性别,年龄,吸烟状况,非高密度胆固醇和静脉血压.
- 利用光梯度增强机分类器和Cox比例危险模型来识别预测性蛋白质组合和验证.
主要成果:
- SCORE2-Pro为特定的人口和临床子组确定了独特和高效的蛋白质面板.
- 该模型显著提高了各子组的预测性能,与临床模型相比,改善了AUC和净重新分类指数 (NRI).
- 例如,女性的9蛋白模型改善了AUC的+0.061和NRI的+0.125;中年人的7蛋白模型显示AUC的改善是+0.036和NRI的+0.127.
结论:
- 使用SCORE2因子和血蛋白质组学的子组分层方法产生了MI的特定蛋白质组特征.
- 这些特定于子组的特征大大提高了预测准确性和心脏病发作风险的重新分类.
- 与传统的临床模型相比,SCORE2-Pro提供了一种更精细和个性化的心血管风险评估方法.
相关概念视频
 01:16
Stratified Sampling Method
15.4K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a stratified sample, divide the population into groups called strata and then take a...
To choose a stratified sample, divide the population into groups called strata and then take a...
15.4K
 02:27
Predicting Molecular Geometry
45.8K
VSEPR Theory for Determination of Electron Pair Geometries
45.8K
 01:33
Proteomics
9.8K
A proteome is the entire set of proteins that a cell type produces. We can study proteomes using the knowledge of genomes because genes code for mRNAs, and the mRNAs encode proteins. Although mRNA analysis is a step in the right direction, not all mRNAs are translated into proteins.
Proteomics is the study of proteomes' function. It involves the large-scale systematic study of the proteome to denote the protein complement expressed by a genome. Scientist Mark Wilkins coined the term...
Proteomics is the study of proteomes' function. It involves the large-scale systematic study of the proteome to denote the protein complement expressed by a genome. Scientist Mark Wilkins coined the term...
9.8K
 01:12
Relative Risk
2.1K
Relative risk (RR) is a statistical measure commonly used in epidemiology to compare the likelihood of a particular event occurring between two groups. This metric is important for evaluating the relationship between exposure to a specific risk factor and the probability of a particular outcome. It plays a crucial role in medical research, public health studies, and risk assessment. Relative risk quantifies how much more (or less) likely an event is to occur in an exposed group compared to an...
2.1K
 01:29
Classification of Epithelial Tissues: Stratified Epithelium
12.7K
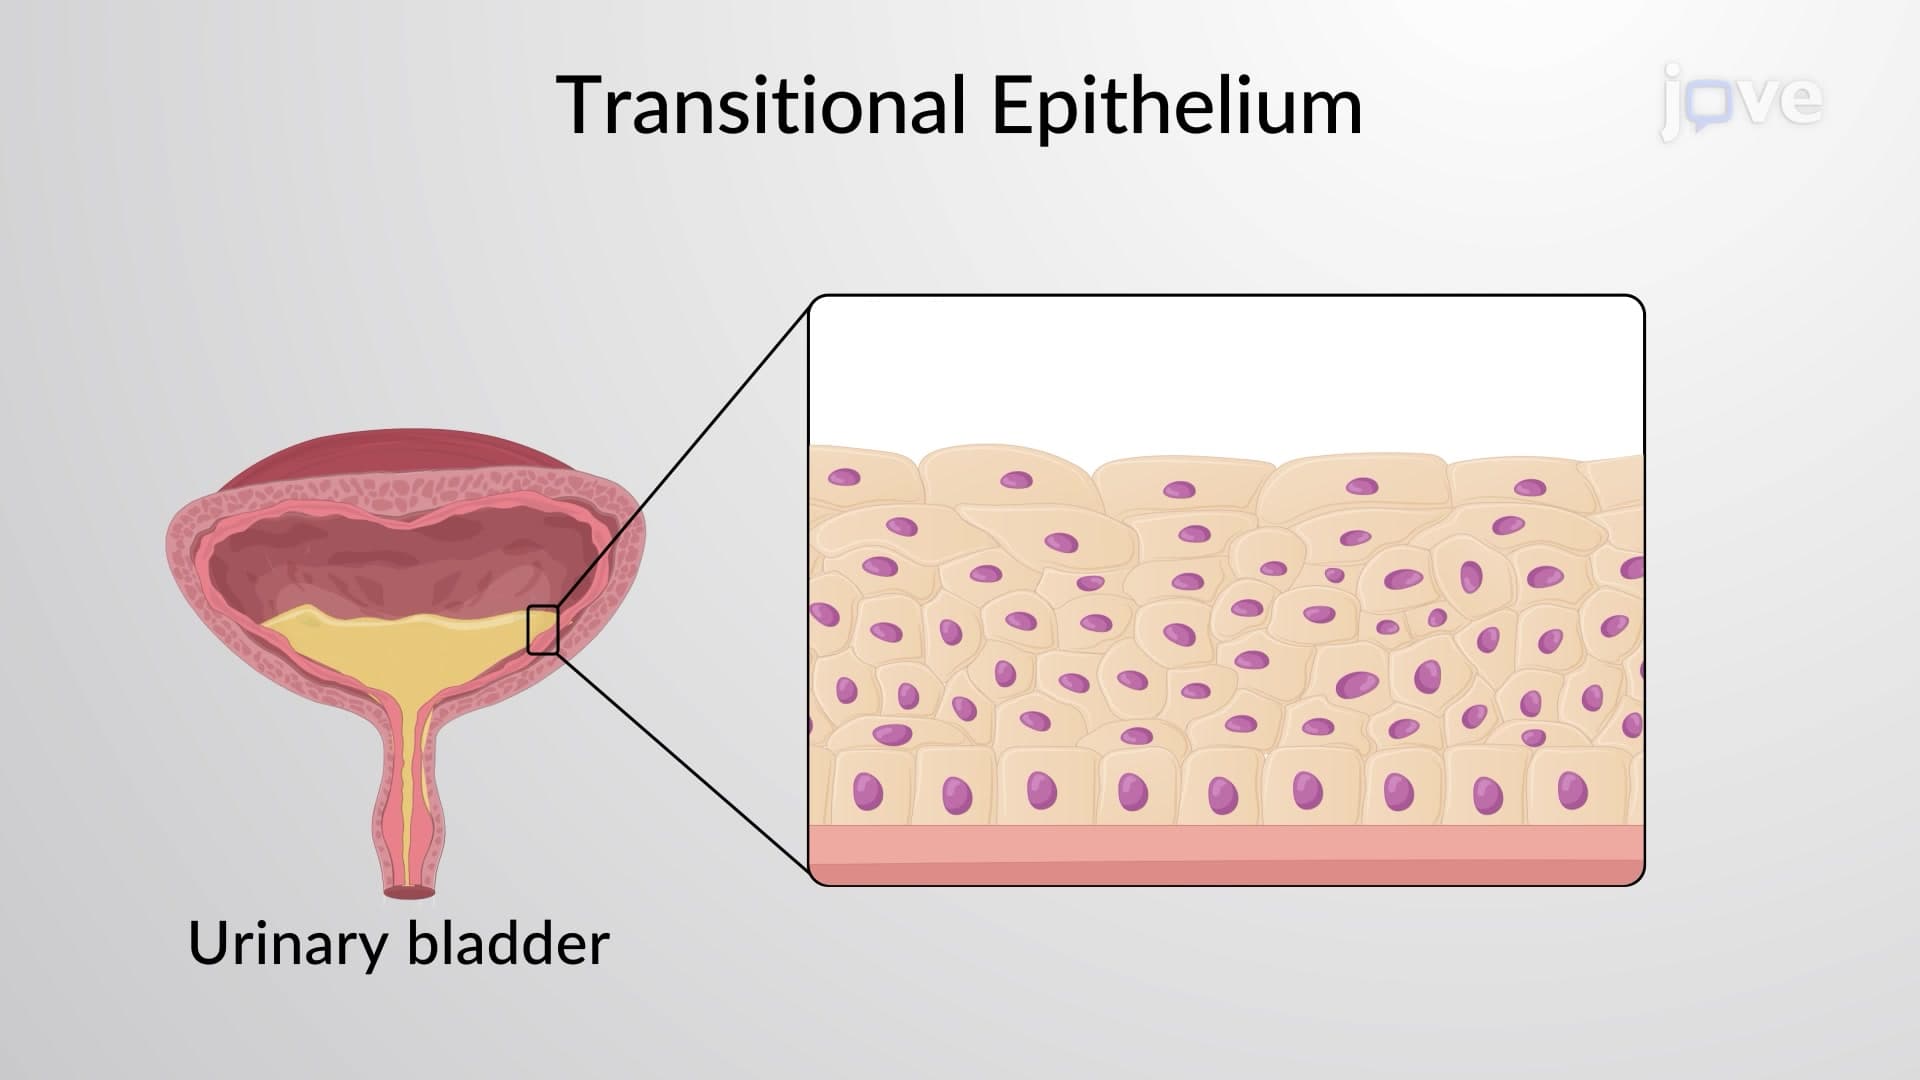
Stratified epithelium consists of several stacked layers of cells. They provide the durability to withstand constant physical and chemical attacks. Stratified epithelium is named after the shape of the most apical layer of cells. Stratified squamous epithelium is the most common type found in the human body. In this tissue, the apical cells are squamous, whereas the basal layer contains either columnar or cuboidal cells. The basal cells divide to form new daughter cells, which gradually become...
12.7K
 01:03
Prediction Intervals
3.4K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
3.4K