
对于半参数循环回归模型的准概率估计
Anna Gottard1, Andrea Meilán-Vila2, Agnese Panzera1
1Department of Statistics, Computer Science, Applications, University of Florence, 50134 Florence, Italy.
Biometrics
|February 3, 2026

概括
这项研究引入了一种灵活的半参数回归模型来分析循环数据,提供了对动物迁移模式的遗传影响的可解释的见解.
科学领域:
- 统计 统计 统计 统计
- 遗传学 是一个遗传学.
- 生态生态学 生态生态学
背景情况:
- 循环数据分析需要灵活和可解释的模型.
- 现有的方法可能缺乏适应复杂的共同变量结构的适应性.
研究的目的:
- 为循环反应开发一个半参数回归模型.
- 为了适应线性和圆性共变量.
- 为分析具有循环特征的生物数据提供一个强大的框架.
主要方法:
- 为循环数据开发了一种半参数回归模型.
- 采用循环准概率函数,避免分布假设.
- 使用后配算法进行模型估计.
- 通过模拟评估模型性能.
主要成果:
- 拟议的模型展示了灵活性和可解释性.
- 该方法有效处理混合线性和圆形共变量.
- 模拟证实了有限样本的良好性能.
结论:
- 半参数模型为循环数据分析提供了一个有价值的工具.
- 它提供了对柳迁徙行为的遗传基础的新见解.
- 这种方法增强了对基因组对生态现象影响的理解.
相关概念视频
 01:52
Regression Toward the Mean
7.0K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
7.0K
 01:25
Multiple Regression
4.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
4.0K
 00:53
Correlation and Regression
3.4K
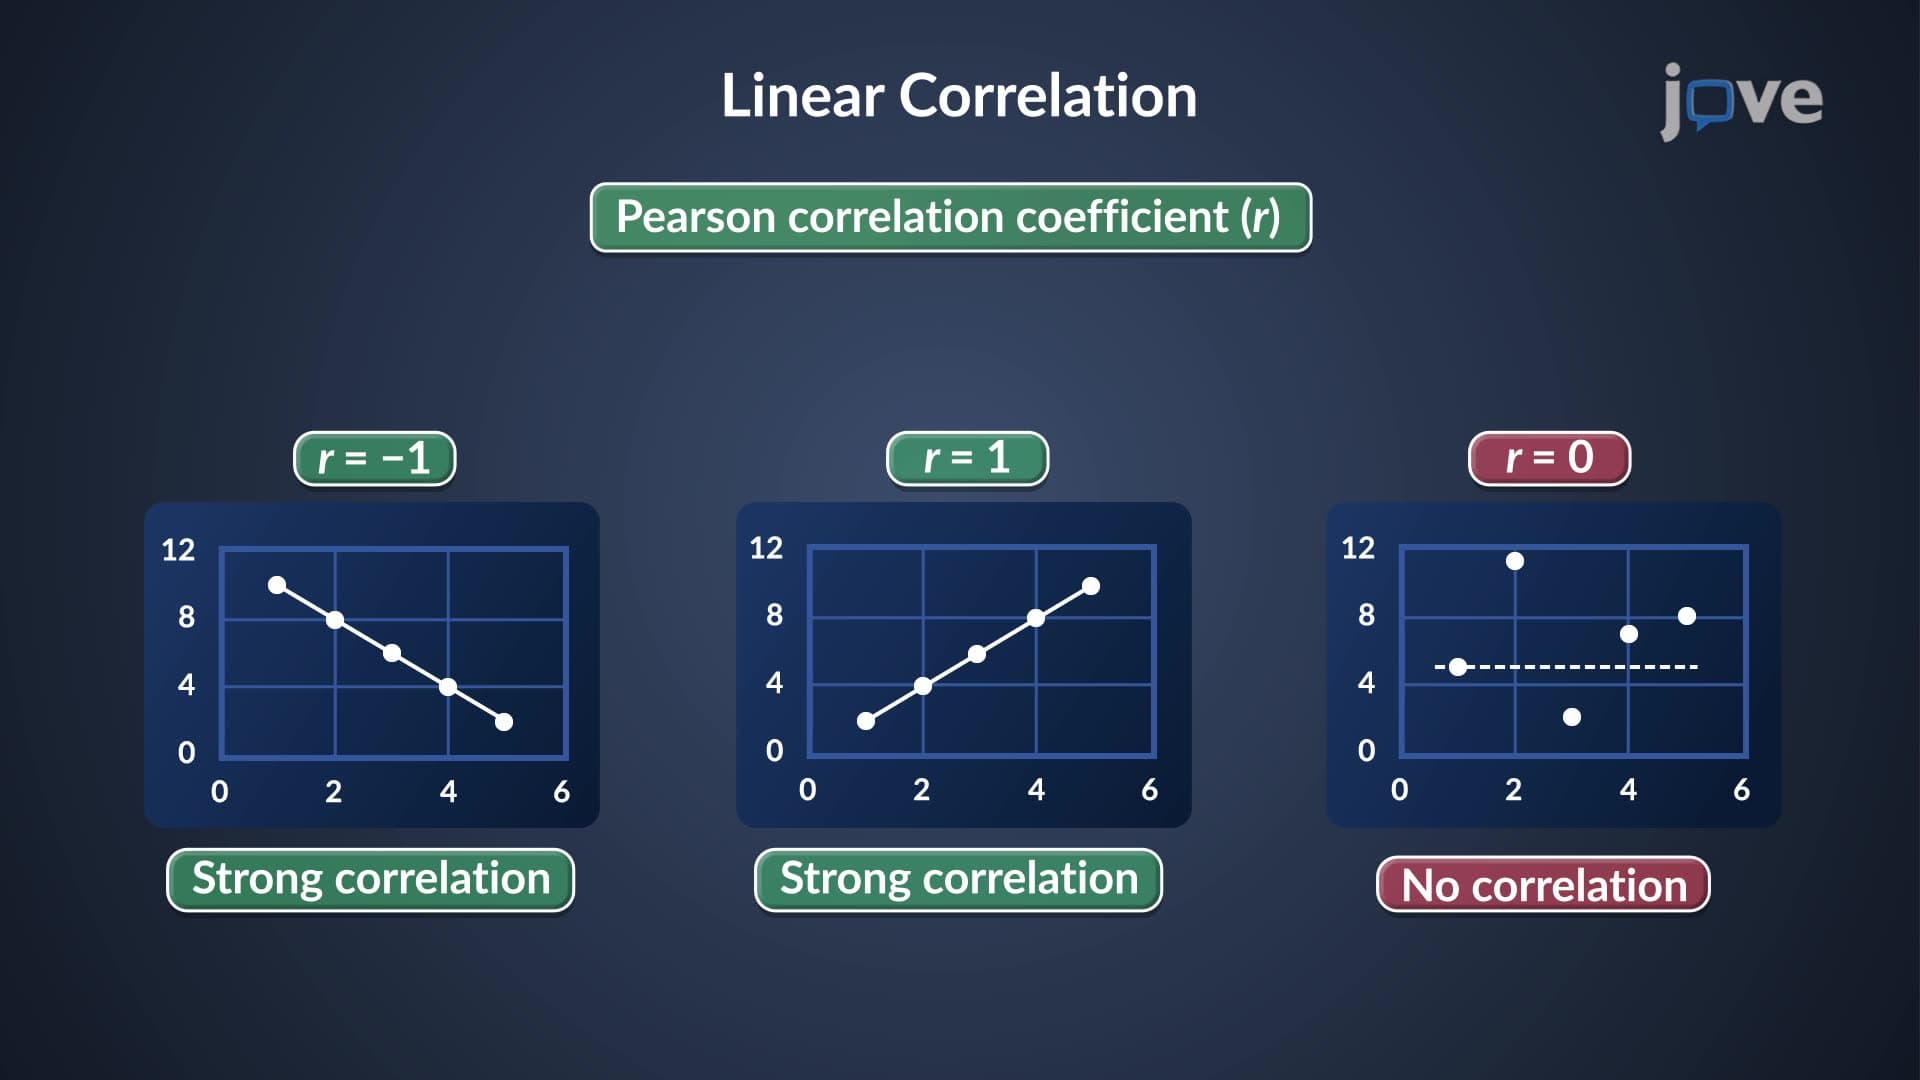
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
3.4K
 01:11
Regression Analysis
8.4K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
8.4K
 01:18
Microsoft Excel: Regression Analysis
1.6K
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
1.6K
 01:06
What are Estimates?
8.8K
It isn't easy to measure a parameter such as the mean height or the mean weight of a population. So, we draw samples from the population and calculate the mean height or mean weight of the individuals in the sample. This sample data acts as a representative measure of the population parameter. These sample statistics are known as estimates.
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
8.8K