
RaCE:用于网络元分析的等级聚类估计方法
Michael Pearce1, Shouhao Zhou2
1Mathematics and Statistics, https://ror.org/00a6ram87Reed College, USA.
Research synthesis methods
|February 4, 2026

概括
网络元分析 (NMA) 排名通过排名集群估计 (RaCE) 得到改善. 这种贝叶斯式方法将类似的干预组合在一起,为更好的临床决策提供超出单一排名的细微解释.
科学领域:
- 生物统计学 生物统计学
- 医疗保健服务研究 医疗服务研究
- 证据综合 证据综合
背景情况:
- 网络元分析 (NMA) 对于比较多种干预措施和为临床决策提供信息至关重要.
- 传统的NMA排名方法可能过度简化治疗效果,导致由于不确定性导致误导性结论.
研究的目的:
- 为NMA引入一种新的贝叶斯级别集群估计 (RaCE) 方法.
- 通过对具有相似结果的治疗方法进行聚类,而不是仅仅确定一个最佳干预措施来提供更细微的干预效果解释.
主要方法:
- 为NMA开发了贝叶斯级别集群估计 (RaCE) 方法.
- 从NMA建模中解脱了聚类,以实现跨结果类型,建模方法和估计框架的灵活性.
- 通过模拟研究和前线免疫化学疗法的NMA对卵泡淋巴瘤进行了验证.
主要成果:
- 即使有显著的不确定性和重叠的干预效应,RaCE也有效地识别了等级集群.
- 与传统的单一排名方法相比,这种方法提供了更合理的解释.
- 对卵泡淋巴瘤的应用揭示了以前被认为是不同的治疗方法中的临床相关集群.
结论:
- 在NMA中,RaCE提高了等级估计和解释性.
- 这种方法在复杂的干预比较中促进了基于证据的决策.
- 对于研究人员来说,RaCE提供了一个有价值的工具,可以对多种干预措施进行综合证据.
相关概念视频
 01:21
Friedman Two-way Analysis of Variance by Ranks
508
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
508
 01:20
Cluster Sampling Method
14.7K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
14.7K
 01:02
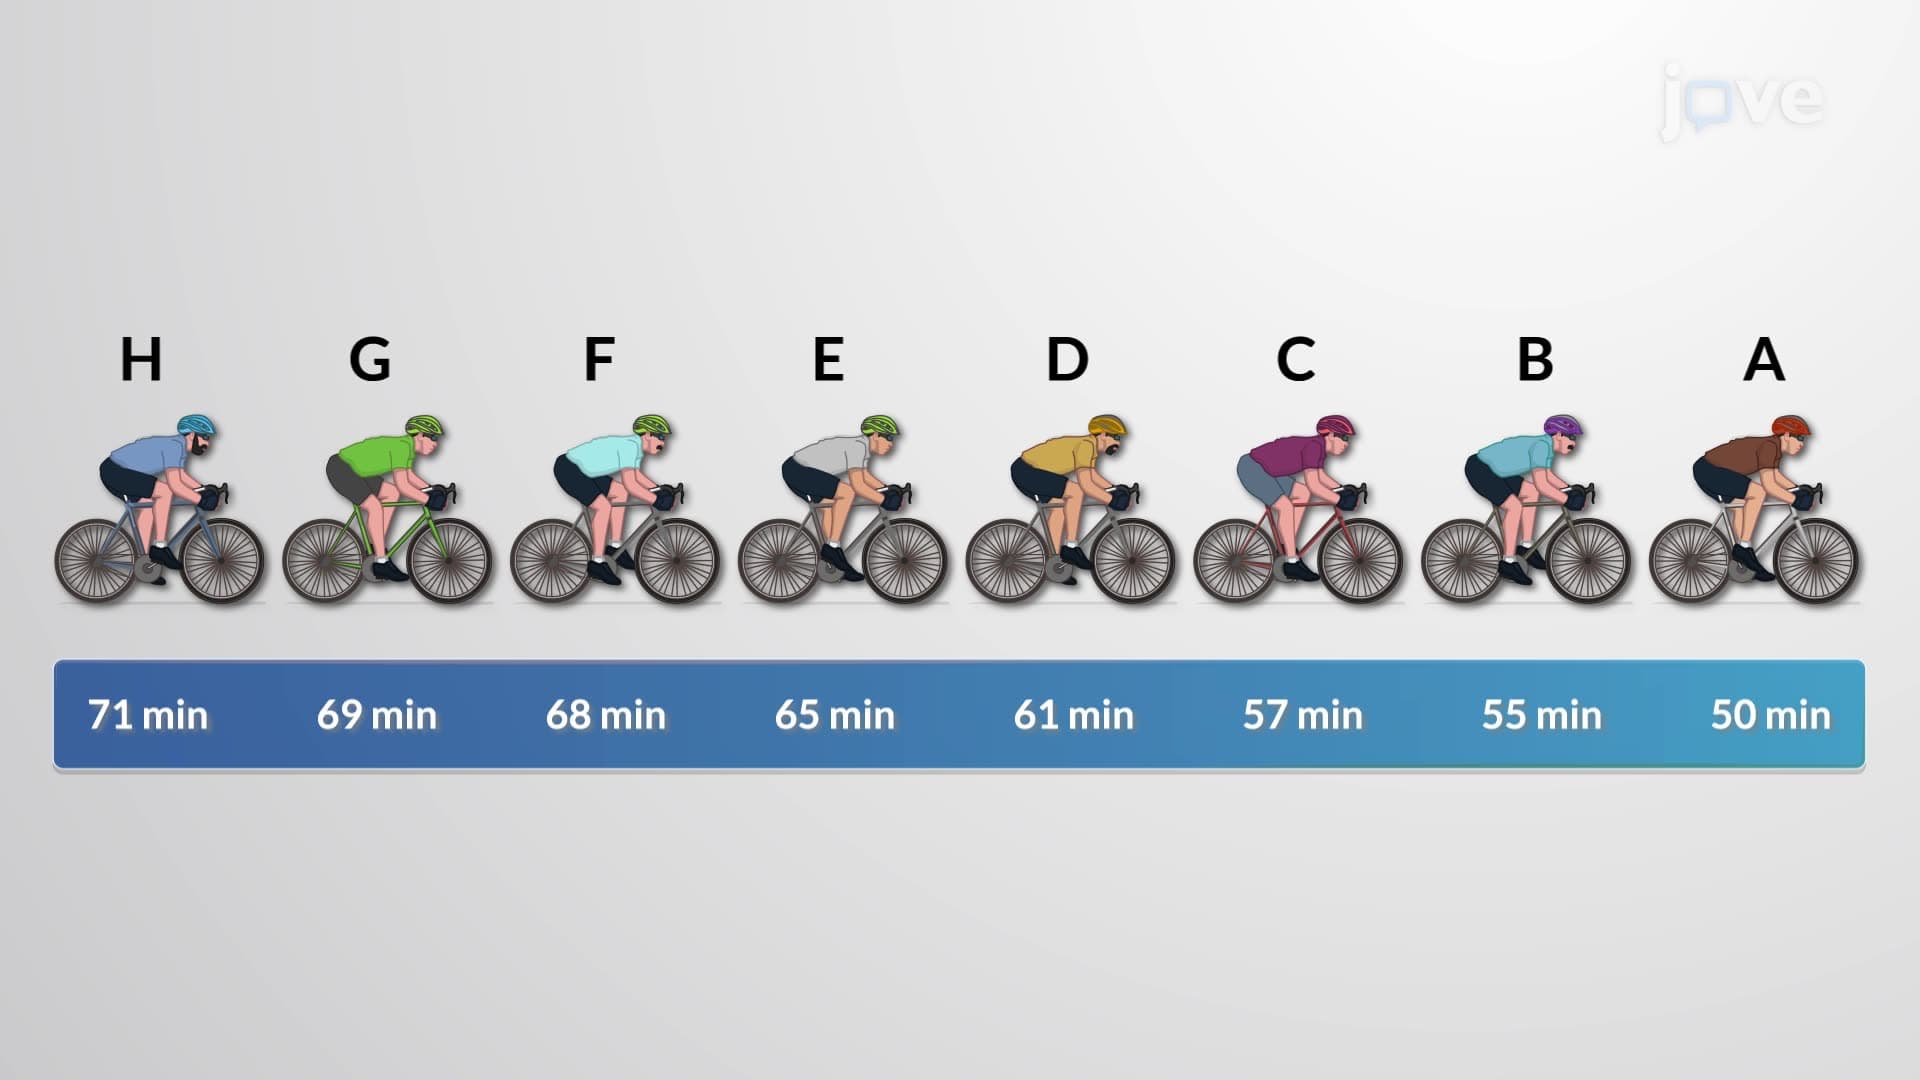
Ranks
507
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
507
 01:20
Spearman's Rank Correlation Test
1.5K
Spearman's rank correlation test, also known as Spearman's rho, is a nonparametric method for assessing the strength and direction of association between two variables. This test is particularly valuable when the data distribution is unknown or when the assumption of normality does not hold. Named after the English psychologist and statistician Dr. Charles Edward Spearman, it serves as the nonparametric counterpart to Pearson's correlation coefficient.
Spearman's test calculates correlation by...
Spearman's test calculates correlation by...
1.5K
 02:35
RACE - Rapid Amplification of cDNA Ends
7.3K
Rapid Amplification of cDNA Ends, or RACE, is one of the most effective methods to obtain a full-length cDNA from an mRNA sequence between a known internal region to the unknown sequence at the 5’ or 3’ end. The unknown region is cloned in the cDNA by a gene-specific primer that binds the known end, and a hybrid primer that attaches a predefined anchor sequence to the unknown end of the cDNA. The sequence in between is amplified by PCR with an anchor primer and a gene-specific...
7.3K
 02:26
Protein Networks
4.6K
An organism can have thousands of different proteins, and these proteins must cooperate to ensure the health of an organism. Proteins bind to other proteins and form complexes to carry out their functions. Many proteins interact with multiple other proteins creating a complex network of protein interactions.
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
4.6K