一个基于机器学习的QSAR模型,用于预测商业农药对Eisenia fetida的毒性
Simin Li1, Peiwen Zhang1, Rong Zhou1
1Research Center of Solid Waste Pollution and Prevention, Nanjing Institute of Environmental Science, Ministry of Ecology and Environment, Nanjing 210042, PR China.

一个新的机器学习框架使用分子结构,土壤条件和配方类型预测杀虫剂对的毒性. 这种方法提供了一种快速,具有成本效益的方法来评估农药对环境的风险.
科学领域:
- 环境化学环境化学
- 毒理学 毒理学 毒理学
- 计算化学的计算化学
背景情况:
- 商用杀虫剂对农业至关重要,但对非目标土壤生物,如虫,构成风险.
- 在现实的土壤条件下评估农药毒性对于环境保护至关重要.
研究的目的:
- 开发基于机器学习的定量结构-活动关系 (ML-QSAR) 框架,以预测商业农药对的毒性.
- 整合分子结构,土壤物理化学参数和配方类型,以准确预测毒性.
主要方法:
- 使用了947个专有和公共农药毒性数据的综合数据集.
- 使用十个机器学习算法,两个描述器集和分子指纹开发了30个二进制分类模型.
- 使用RDKit描述符 (GBDT-RDKit) 的渐变增强决策树作为最佳模型,使用准确度,精度,回忆和AUROC等指标进行验证.
- 使用Tanimoto相似性定义了模型的适用域.
主要成果:
- 最优的 GBDT-RDKit 模型实现了高预测性能 (准确率 = 0.83,AUROC = 0.88).
- 沙普利添加剂扩展 (SHAP) 分析揭示了化学结构,土壤参数和配方类型对毒性的显著影响.
- 开发了三类分类器,以优先考虑高度有毒的农药.
结论:
- 开发的ML-QSAR框架提供了一种快速且具有成本效益的方法,用于评估农药对土壤的毒性.
- 这种方法可以帮助商业农药的环境风险评估,支持可持续的农业实践.
更多相关视频
 07:13
Comparison of Predictive Performance of Three Lymph Node Staging Systems in Colorectal Signet Ring Cell Carcinoma Based on Machine Learning Model
Published on: April 18, 2025
 05:47
In Silico Modeling Method for Computational Aquatic Toxicology of Endocrine Disruptors: A Software-Based Approach Using QSAR Toolbox
Published on: August 28, 2019
相关概念视频
 01:30
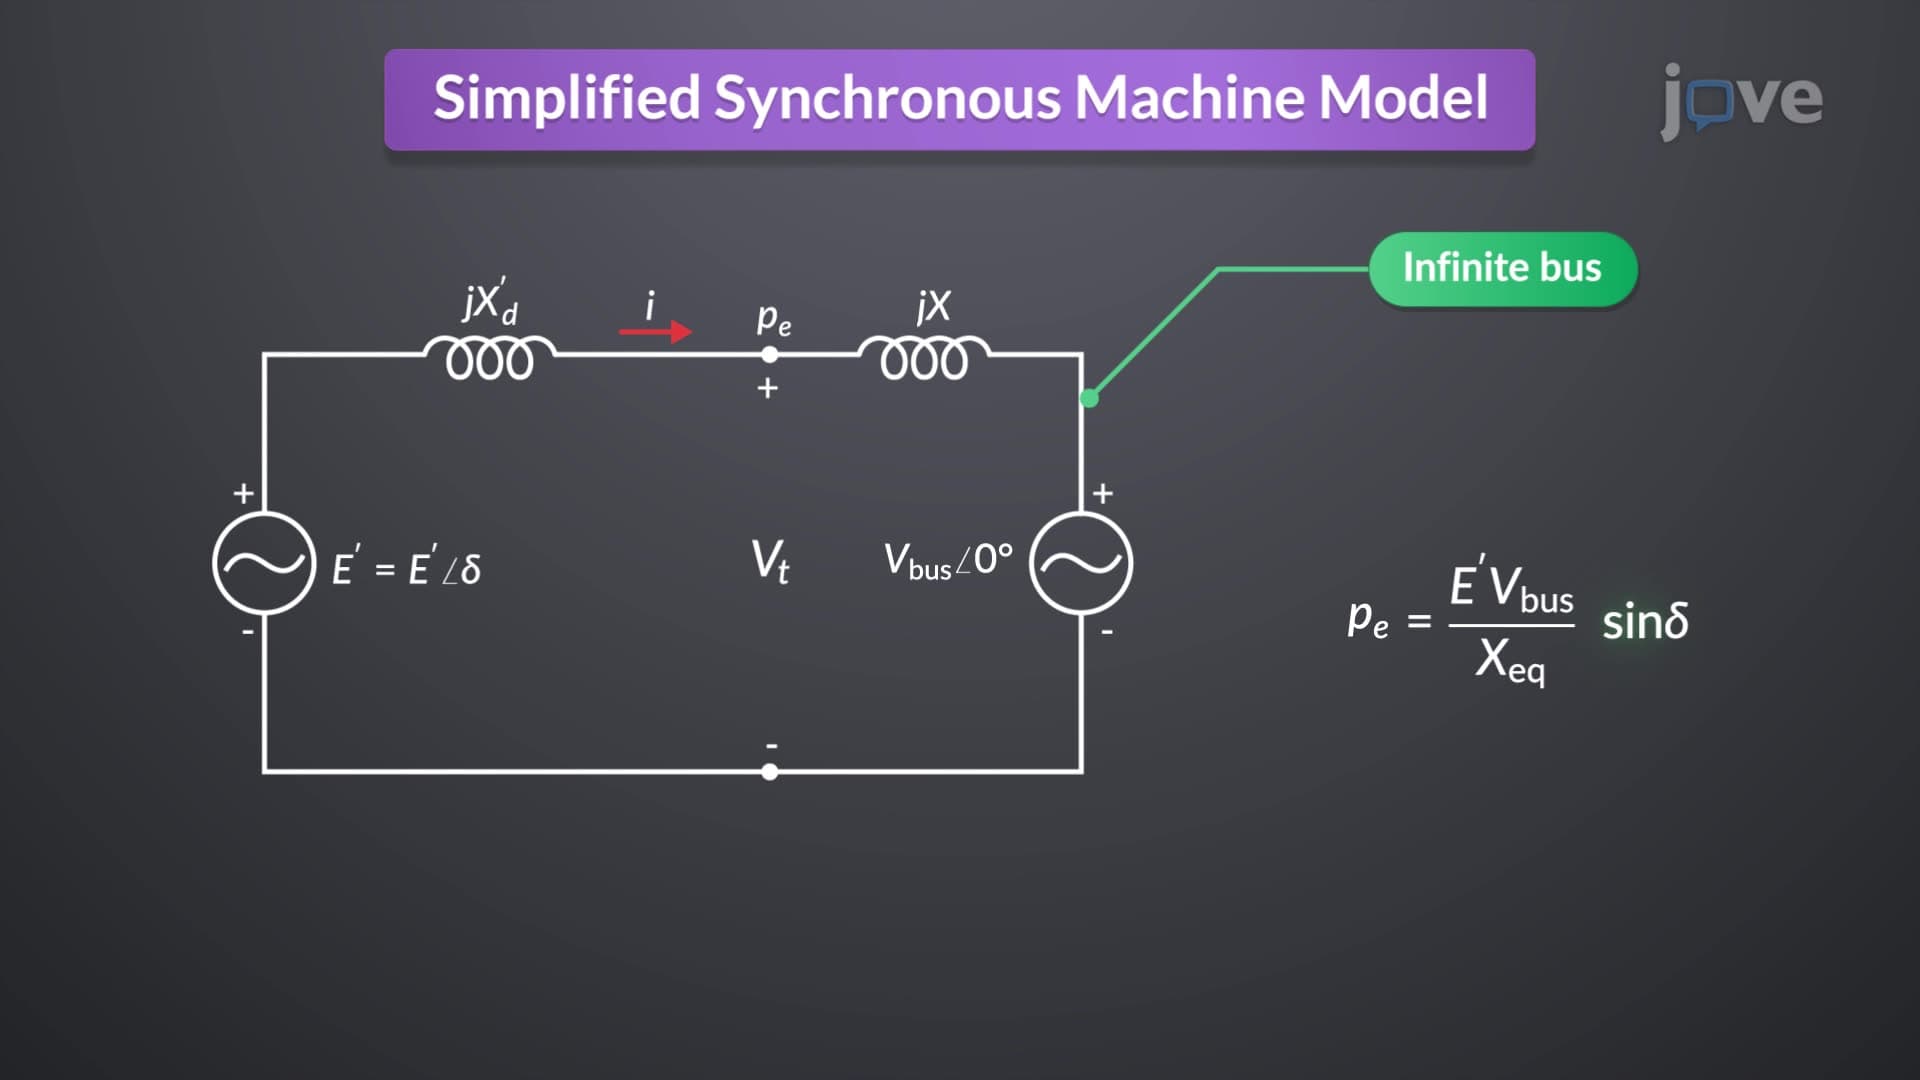
Simplified Synchronous Machine Model
In this model, each generator is connected to a...
 01:24
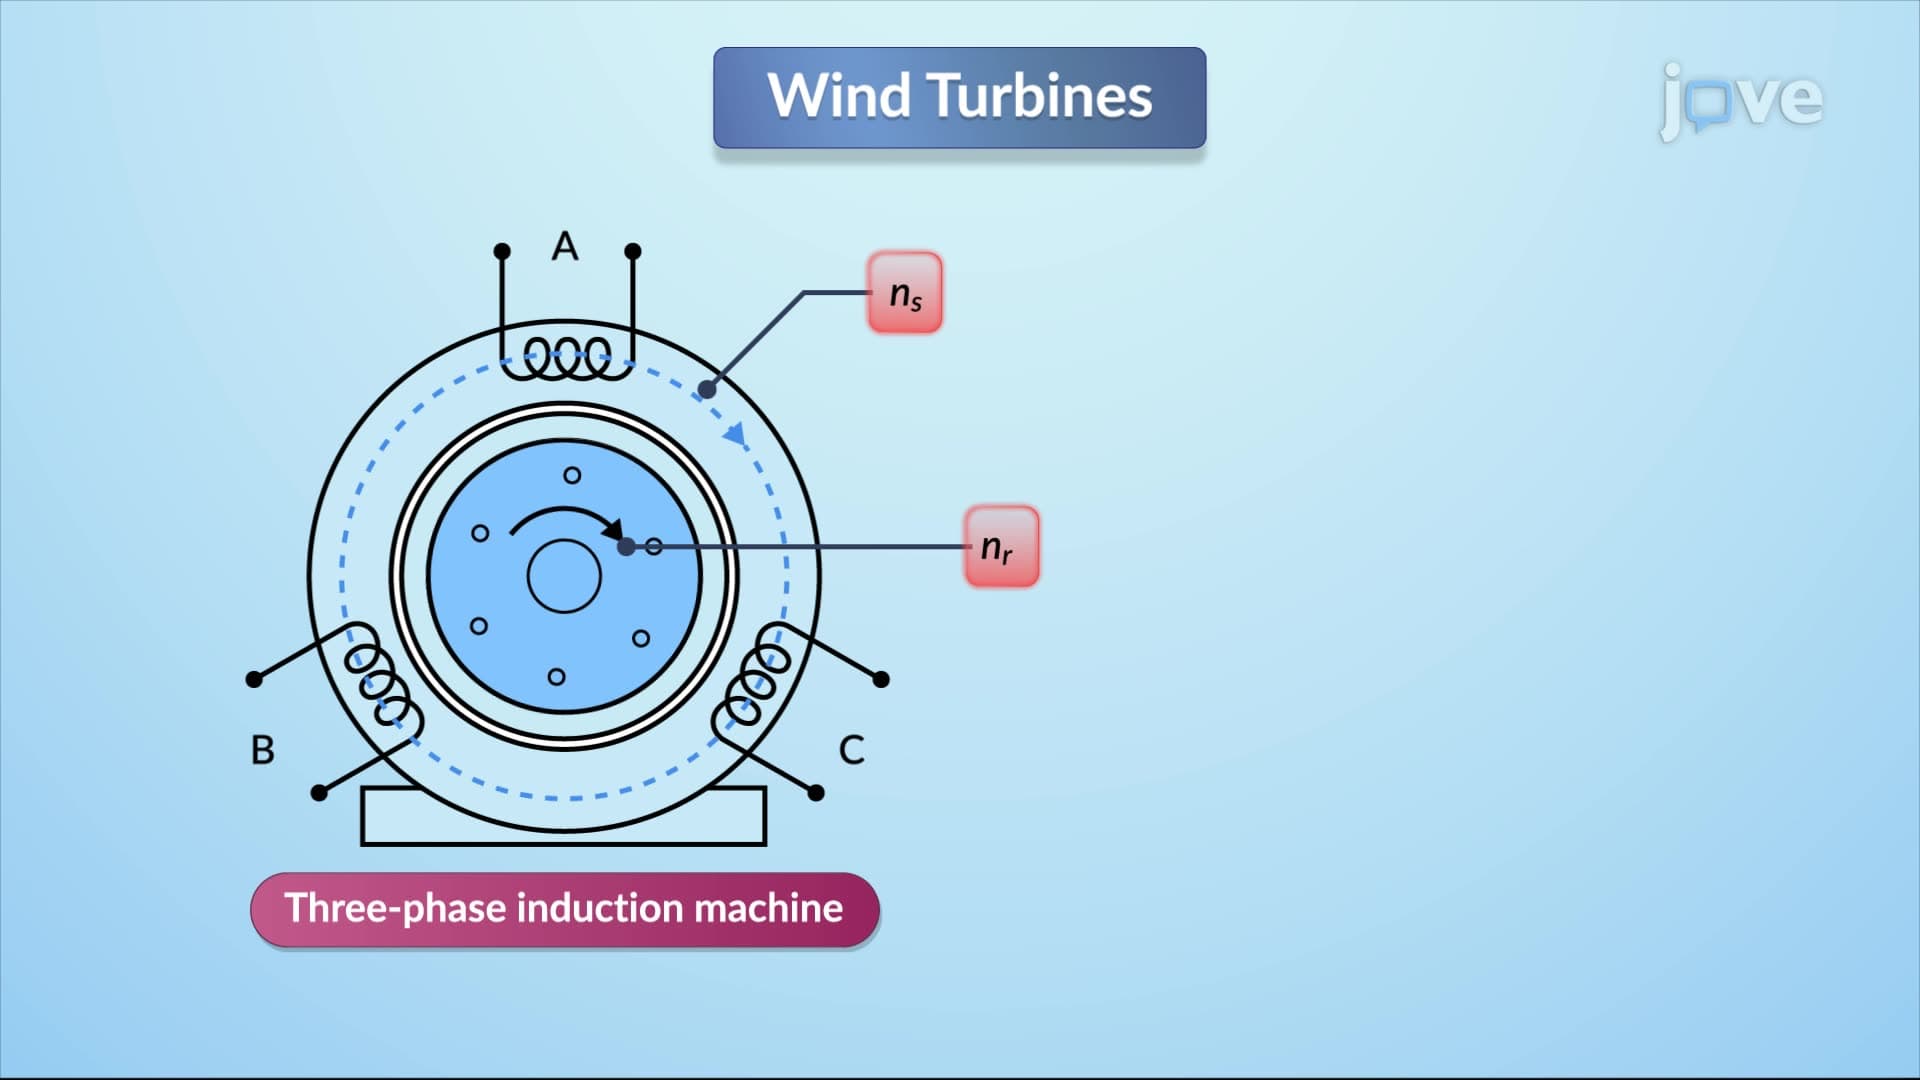
Wind Turbine Machine Models
Induction machines interact through the rotating magnetic field generated by the stator and the rotor. The key parameter is slip, which is the difference between synchronous speed and rotor speed relative to synchronous speed. Slip is...
 02:27
Predicting Molecular Geometry
 01:19
Machines
A free-body diagram of the...
 01:30
Machines: Problem Solving II
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.