相关实验视频
Updated: Mar 18, 2026
03:52

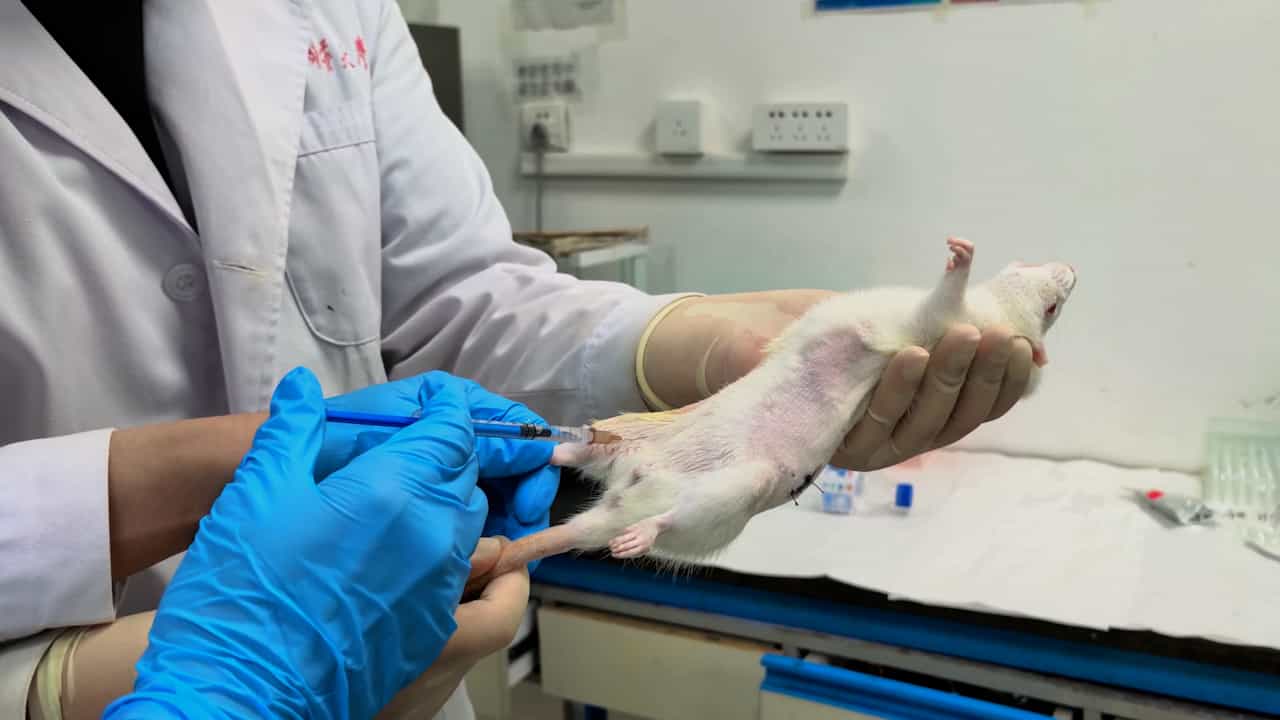
The Creation of a Rat Model for Osteosarcopenia via Ovariectomy
Published on: February 21, 2025
1.4K
评估大型语言模型在与皮症相关的患者查询中的性能:为以患者为中心的验证进行基础评估
Tao Huang1, Ben Kirk2, Jacqueline Close3
1Department of Orthopaedics and Traumatology, The Chinese University of Hong Kong, Hong Kong SAR, China.
Frontiers in aging
|March 16, 2026

概括
大型语言模型 (LLM) 对皮病信息有希望,所有测试模型都显示出良好的准确性和全面性. 专家评估表明,LLM可以帮助患者教育,但人类监督对于安全实施至关重要.
科学领域:
- 人工智能的人工智能
- 医疗信息学 医疗信息学
- 老年病的医生 老年病的医生
背景情况:
- 大型语言模型 (LLM) 在临床环境中显示出潜力.
- 在萨尔科佩尼亚等专业领域的LLM绩效被低估了.
研究的目的:
- 评估LLM对以患者为中心的萨尔科佩尼亚查询的答案的准确性和全面性.
- 为了比较三个领先的LLM在提供肉症信息方面的表现.
主要方法:
- 一个由sarcopenia专家组成的小组制定了20个标准化问题.
- 三个LLM (Deepseek,ChatGPT,Gemini) 回答了这些问题.
- 答案是匿名的,并由三个独立的临床研究人员对准确性和全面性进行评估.
主要成果:
- 所有LLM的表现都很好,没有"差"准确度评级.
- 深度搜索提供了最详细的答案,在"风险因素"和"预后"方面表现出色.
- 聊天GPT提供了简洁的答案,最高比例的"好"评级;双子座在"发病"和"诊断"方面领先.
结论:
- 所有评估的LLM都表现出了可接受的准确性和全面性,对于与肉类相关的查询.
- LLM可以作为宝贵的工具,用于患者教育和护理在肉症.
- 人类监督对于安全有效的临床应用至关重要.

相关概念视频
 02:07
Improving Translational Accuracy
15.4K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
15.4K
02:07Improving Translational Accuracy
3.8K
3.8K