Related Experiment Video
Updated: Sep 16, 2026

fMRI Mapping of Brain Activity Associated with the Vocal Production of Consonant and Dissonant Intervals
Published on: May 23, 2017
Intonation and dialog context as constraints for speech recognition
1Center for Speech Technology Research, University of Edinburgh, U.K. pault@cstr.ed.ac.uk

Abstract:
This paper describes a way of using intonation and dialog context to improve the performance of an automatic speech recognition (ASR) system. Our experiments were run on the DCIEM Maptask corpus, a corpus of spontaneous task-oriented dialog speech. This corpus has been tagged according to a dialog analysis scheme that assigns each utterance to one of 12 "move types," such as "acknowledge," "query-yes/no" or "instruct." Most ASR systems use a bigram language model to constrain the possible sequences of words that might be recognized. Here we use a separate bigram language model for each move type. We show that when the "correct" move-specific language model is used for each utterance in the test set, the word error rate of the recognizer drops. Of course when the recognizer is run on previously unseen data, it cannot know in advance what move type the speaker has just produced. To determine the move type we use an intonation model combined with a dialog model that puts constraints on possible sequences of move types, as well as the speech recognizer likelihoods for the different move-specific models. In the full recognition system, the combination of automatic move type recognition with the move specific language models reduces the overall word error rate by a small but significant amount when compared with a baseline system that does not take intonation or dialog acts into account. Interestingly, the word error improvement is restricted to "initiating" move types, where word recognition is important. In "response" move types, where the important information is conveyed by the move type itself--for example, positive versus negative response--there is no word error improvement, but recognition of the response types themselves is good. The paper discusses the intonation model, the language models, and the dialog model in detail and describes the architecture in which they are combined.
More Related Videos
 09:09
Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
 05:48
Memorization-Based Training and Testing Paradigm for Robust Vocal Identity Recognition in Expressive Speech Using Event-Related Potentials Analysis
Published on: August 9, 2024
Related Concept Videos
 01:26
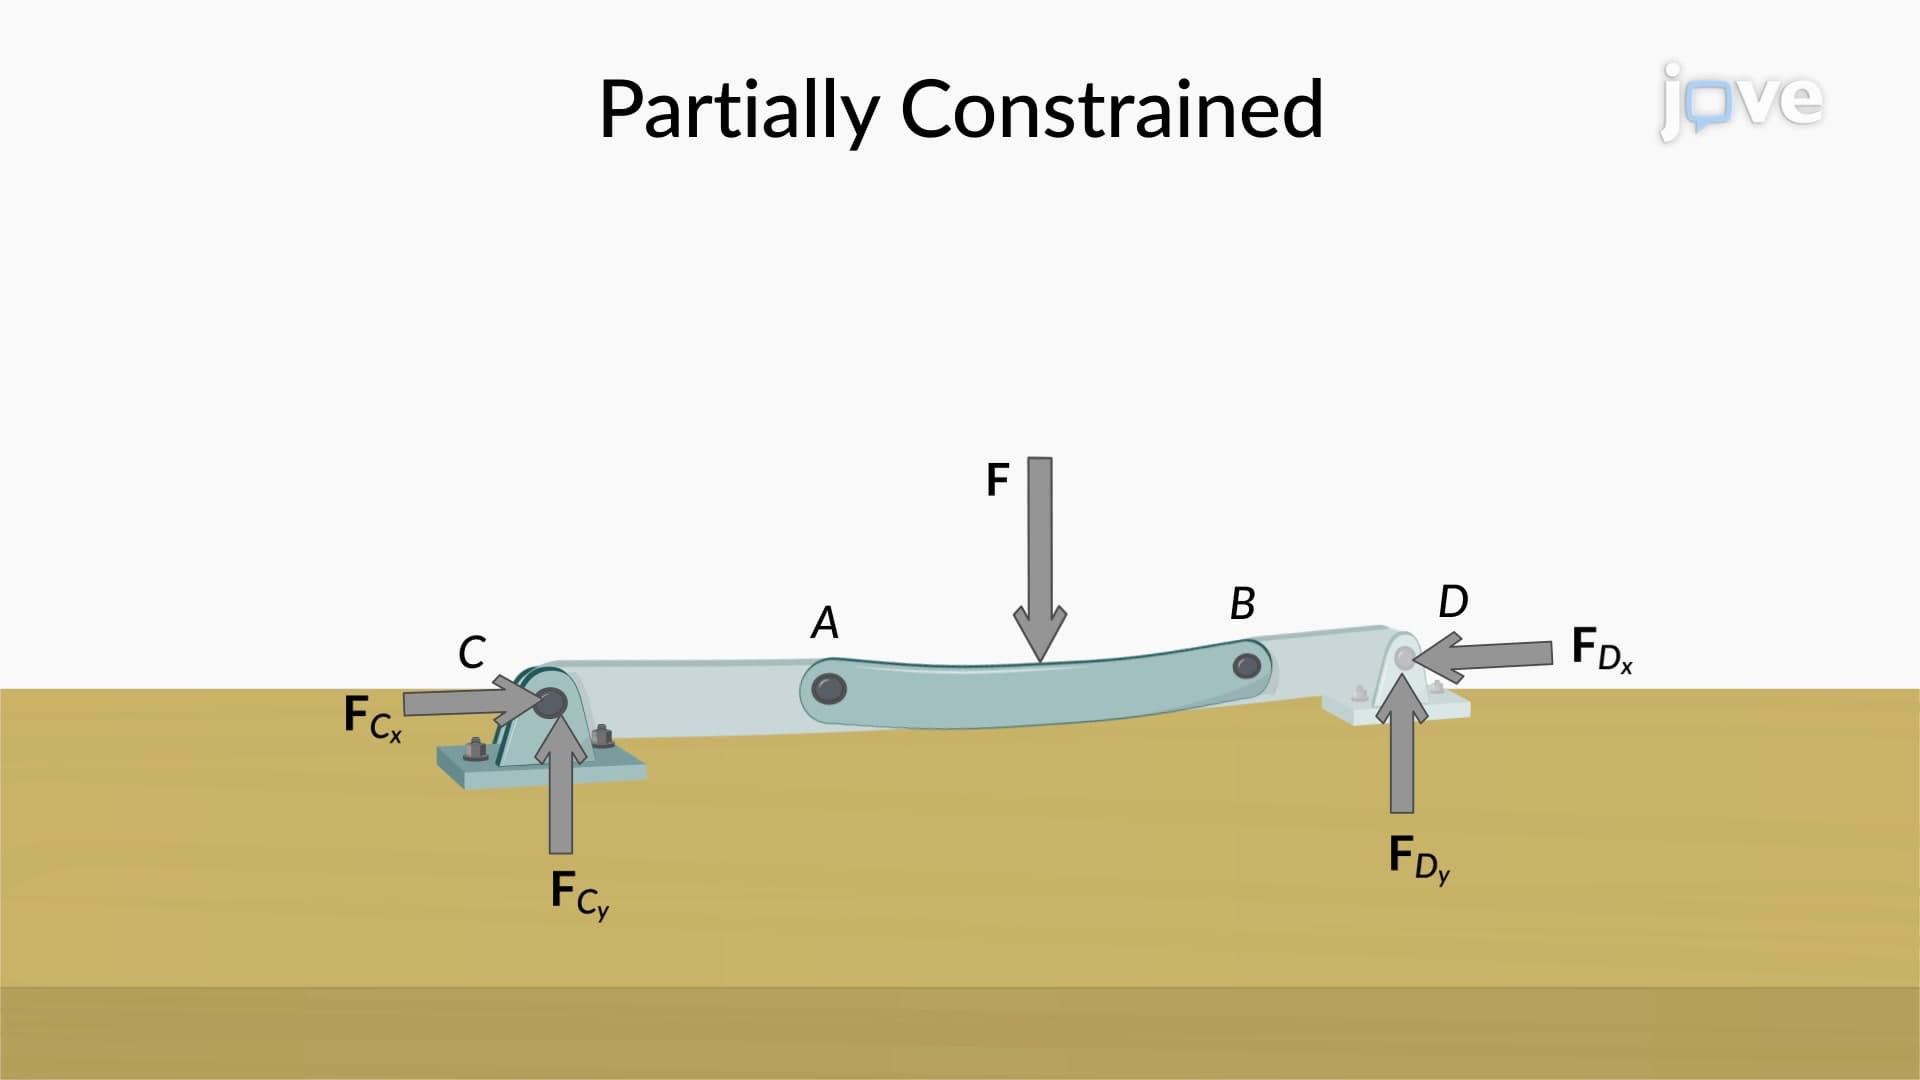
Constraints and Statical Determinacy
 01:27
Air-entraining Agents
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by identifying...
 01:24
Components of Language
 01:22
Language Development
The critical period for language acquisition suggests that the ability to acquire language is at its peak early in life. As people age, this proficiency decreases. Language development begins very...
 01:27
Language and Cognition