Related Experiment Videos
Sufficient conditions for error backflow convergence in dynamical recurrent neural networks
1LIMOS (FRE CNRS 2239), University Blaise Pascal, Clermont Ferrand II, Aubiere, France. alex@isima.fr

Abstract:
This article extends previous analysis of the gradient decay to a class of discrete-time fully recurrent networks, called dynamical recurrent neural networks, obtained by modeling synapses as finite impulse response (FIR) filters instead of multiplicative scalars. Using elementary matrix manipulations, we provide an upper bound on the norm of the weight matrix, ensuring that the gradient vector, when propagated in a reverse manner in time through the error-propagation network, decays exponentially to zero. This bound applies to all recurrent FIR architecture proposals, as well as fixed-point recurrent networks, regardless of delay and connectivity. In addition, we show that the computational overhead of the learning algorithm can be reduced drastically by taking advantage of the exponential decay of the gradient.
Related Concept Videos
 01:10
Propagation of Uncertainty from Systematic Error
 01:20
Region of Convergence of Laplace Tarnsform
Consider a decaying exponential signal that begins at a specific time. When deriving its Laplace transform, the time-domain variable is replaced with a complex variable. This substitution...
 01:25
Neural Circuits
Neuronal pools are collections of nerve cells with similar functions and interact through chemical and electrical signals. These pools include both interneurons (the central neural circuit nodes that...
 01:17
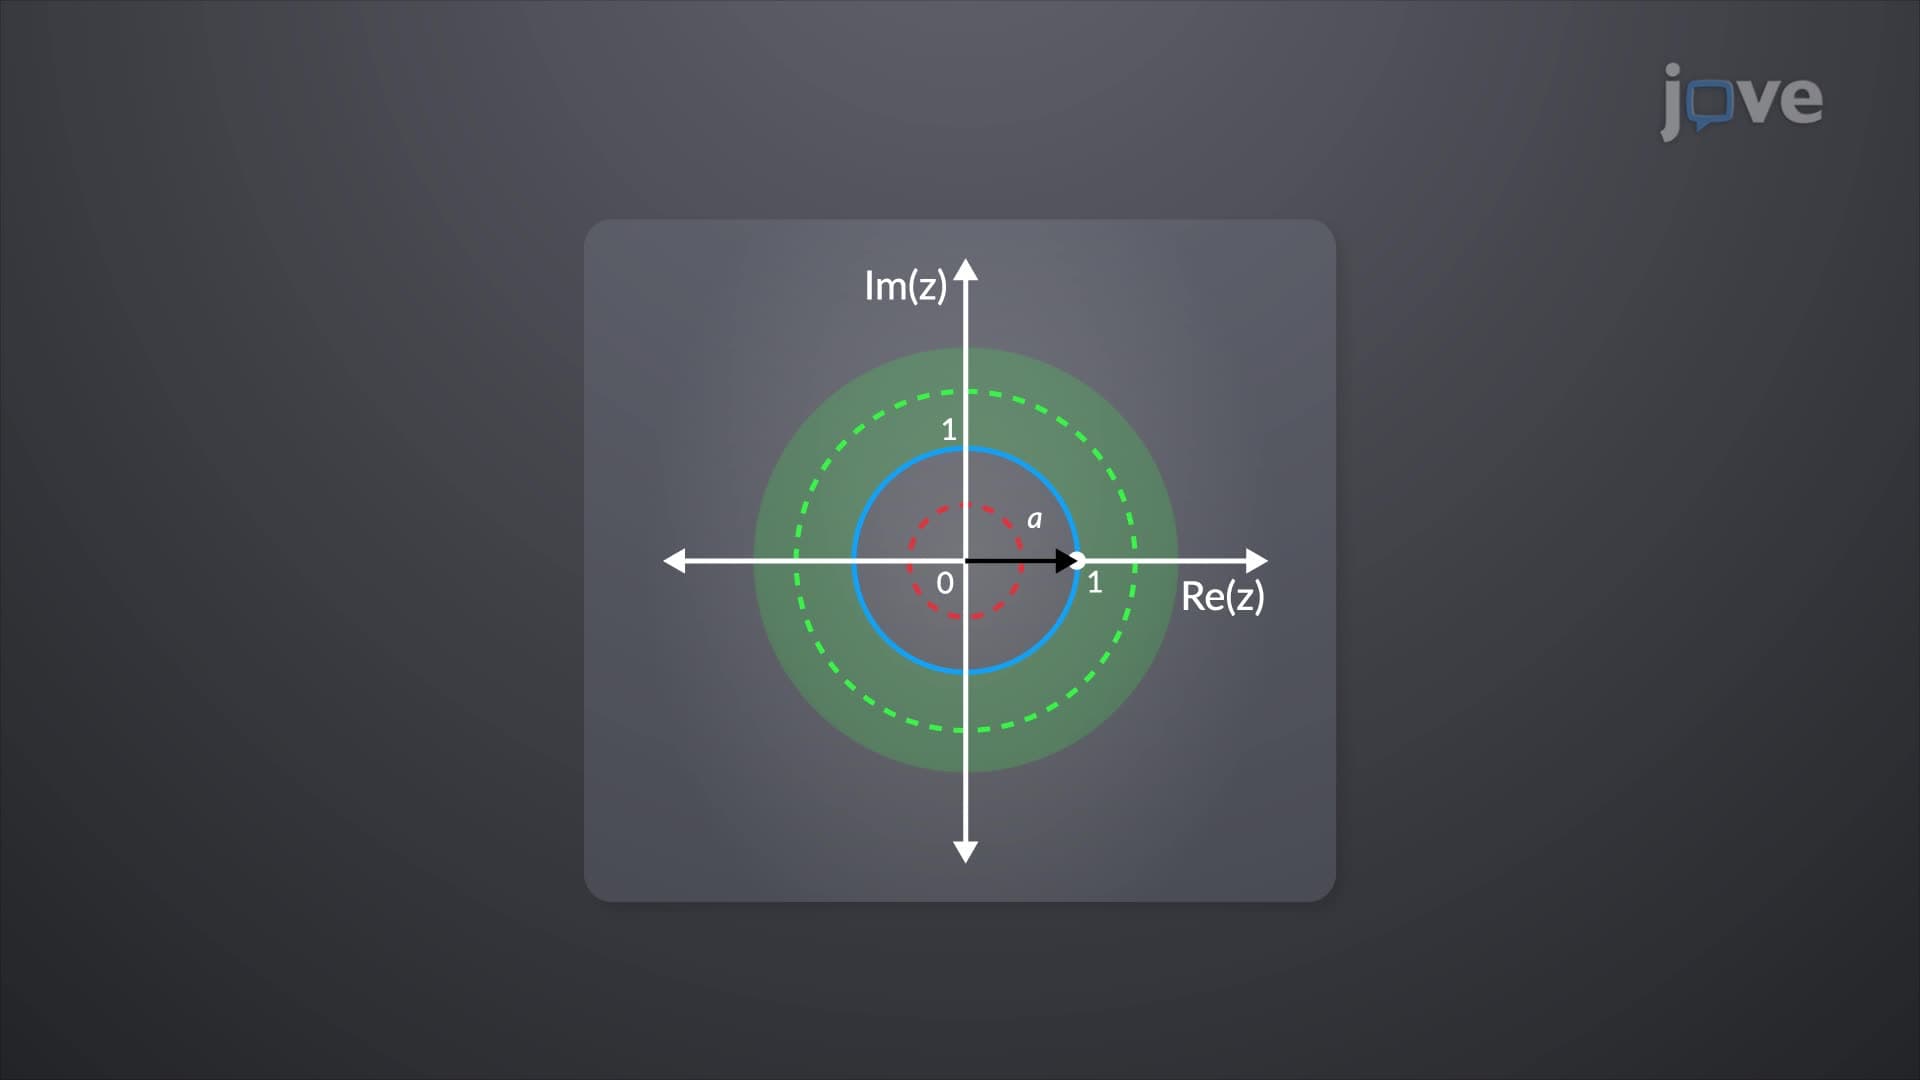
Region of Convergence
 01:18
Second Order systems II
If ζ...
 01:22
Net Change Theorem