Permutation analysis of data with multiple binary category choices

Kenneth J Berry1, P W Mielke

  • 1Department of Sociology, Colorado State University, Fort Collins 80523-1784, USA. berry@lamar.colostate.edu

Psychological Reports
|April 4, 2003
PubMed

Related Concept Videos

How Data are Classified: Categorical Data01:11

How Data are Classified: Categorical Data

A variable, usually notated by capital letters such as X and Y, is a characteristic or measurement that can be determined for each member of a population. Data are the actual values of variables. They may be numbers, or they may be words. Datum is a single value.
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
Contingency Table01:29

Contingency Table

A contingency table provides a way of portraying data that can facilitate calculating probabilities. It is a method of displaying a frequency distribution as a table with rows and columns to show how two variables may be dependent (contingent) upon each other; The table helps determine conditional probabilities quite quickly and can help systematically organize, analyze and quantify data. The table displays sample values concerning two variables that may be dependent or contingent on one...
Binomial Probability Distribution01:15

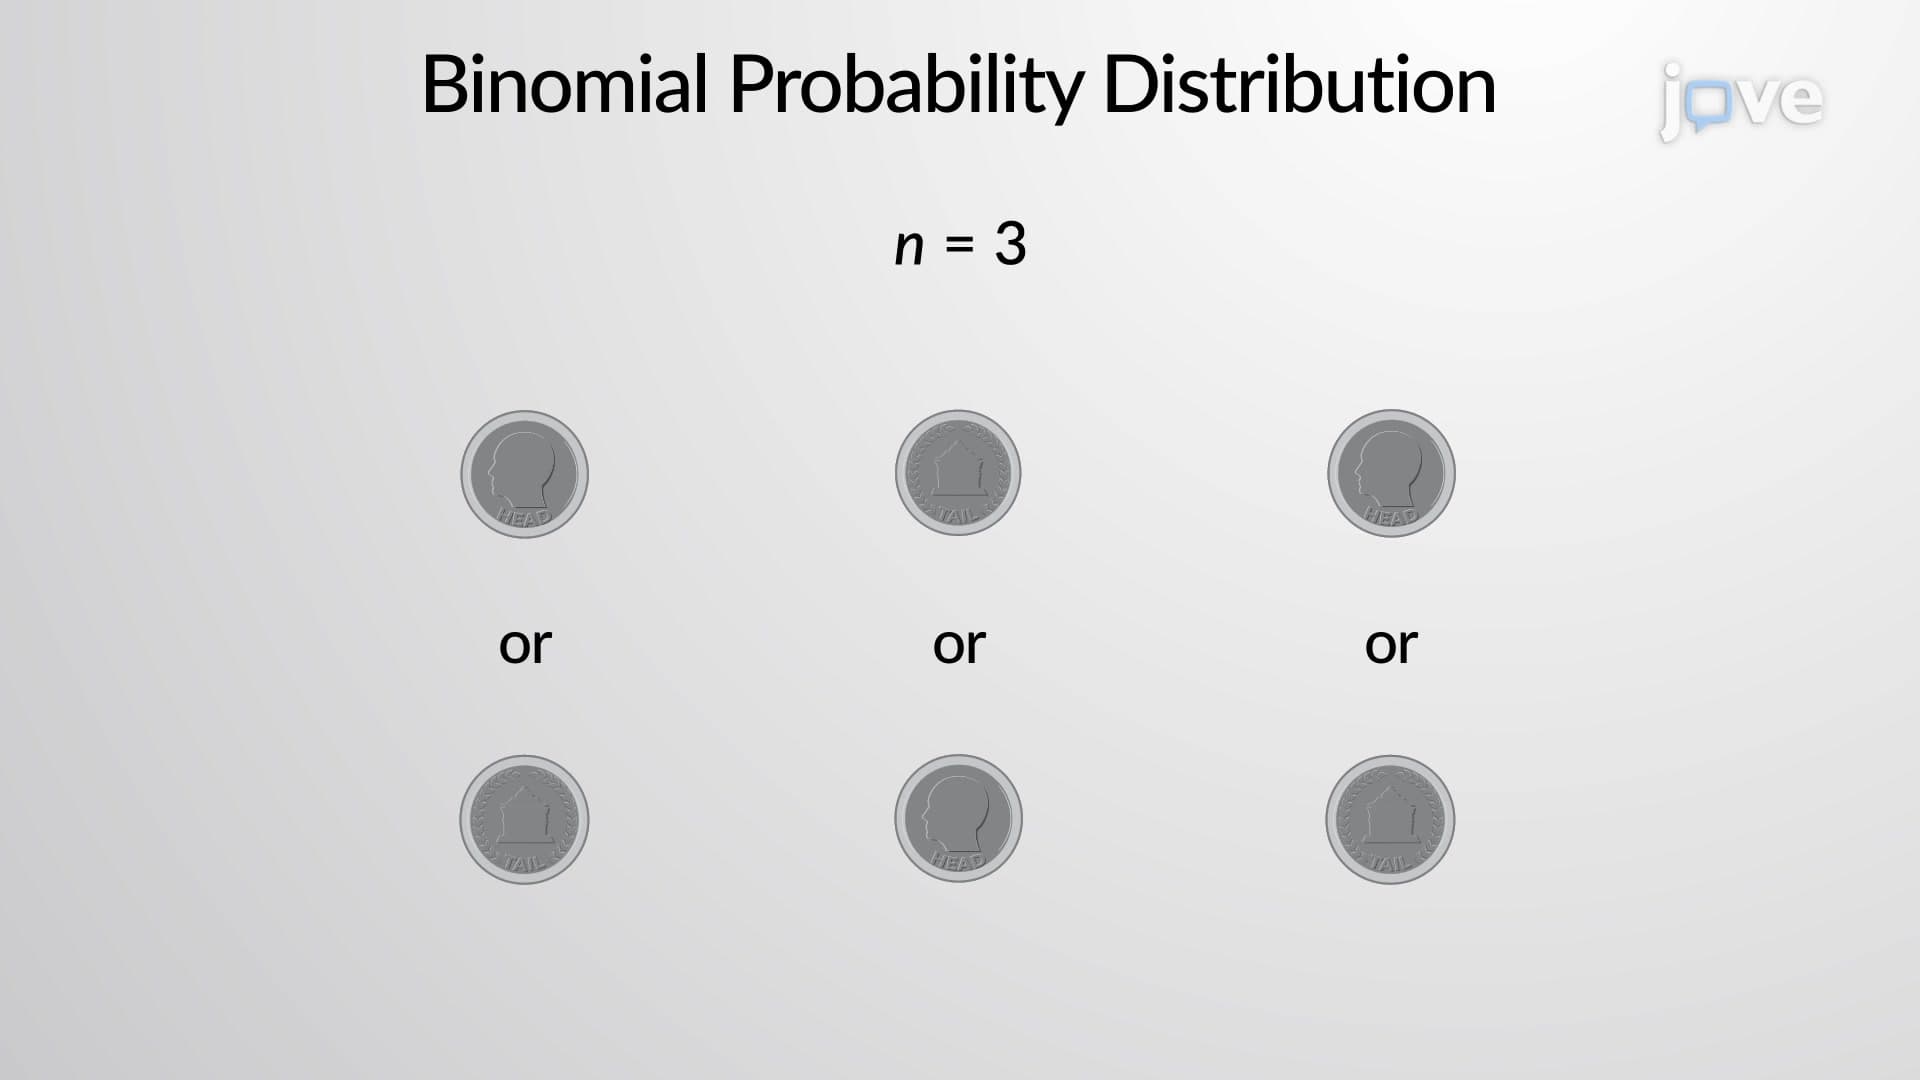
Binomial Probability Distribution

A binomial distribution is a probability distribution for a procedure with a fixed number of trials, where each trial can have only two outcomes.
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
McNemar's Test01:23

McNemar's Test

McNemar's Test is a nonparametric statistical test used to determine if there is a significant difference in proportions between two related groups when the outcome is binary (e.g., yes/no, success/failure). It is beneficial when we have paired data, such as pre-test/post-test designs, where the same subjects are measured under two different conditions. The test is named after the statistician Quinn McNemar, who introduced it in 1947. It is commonly used in situations where subjects are...
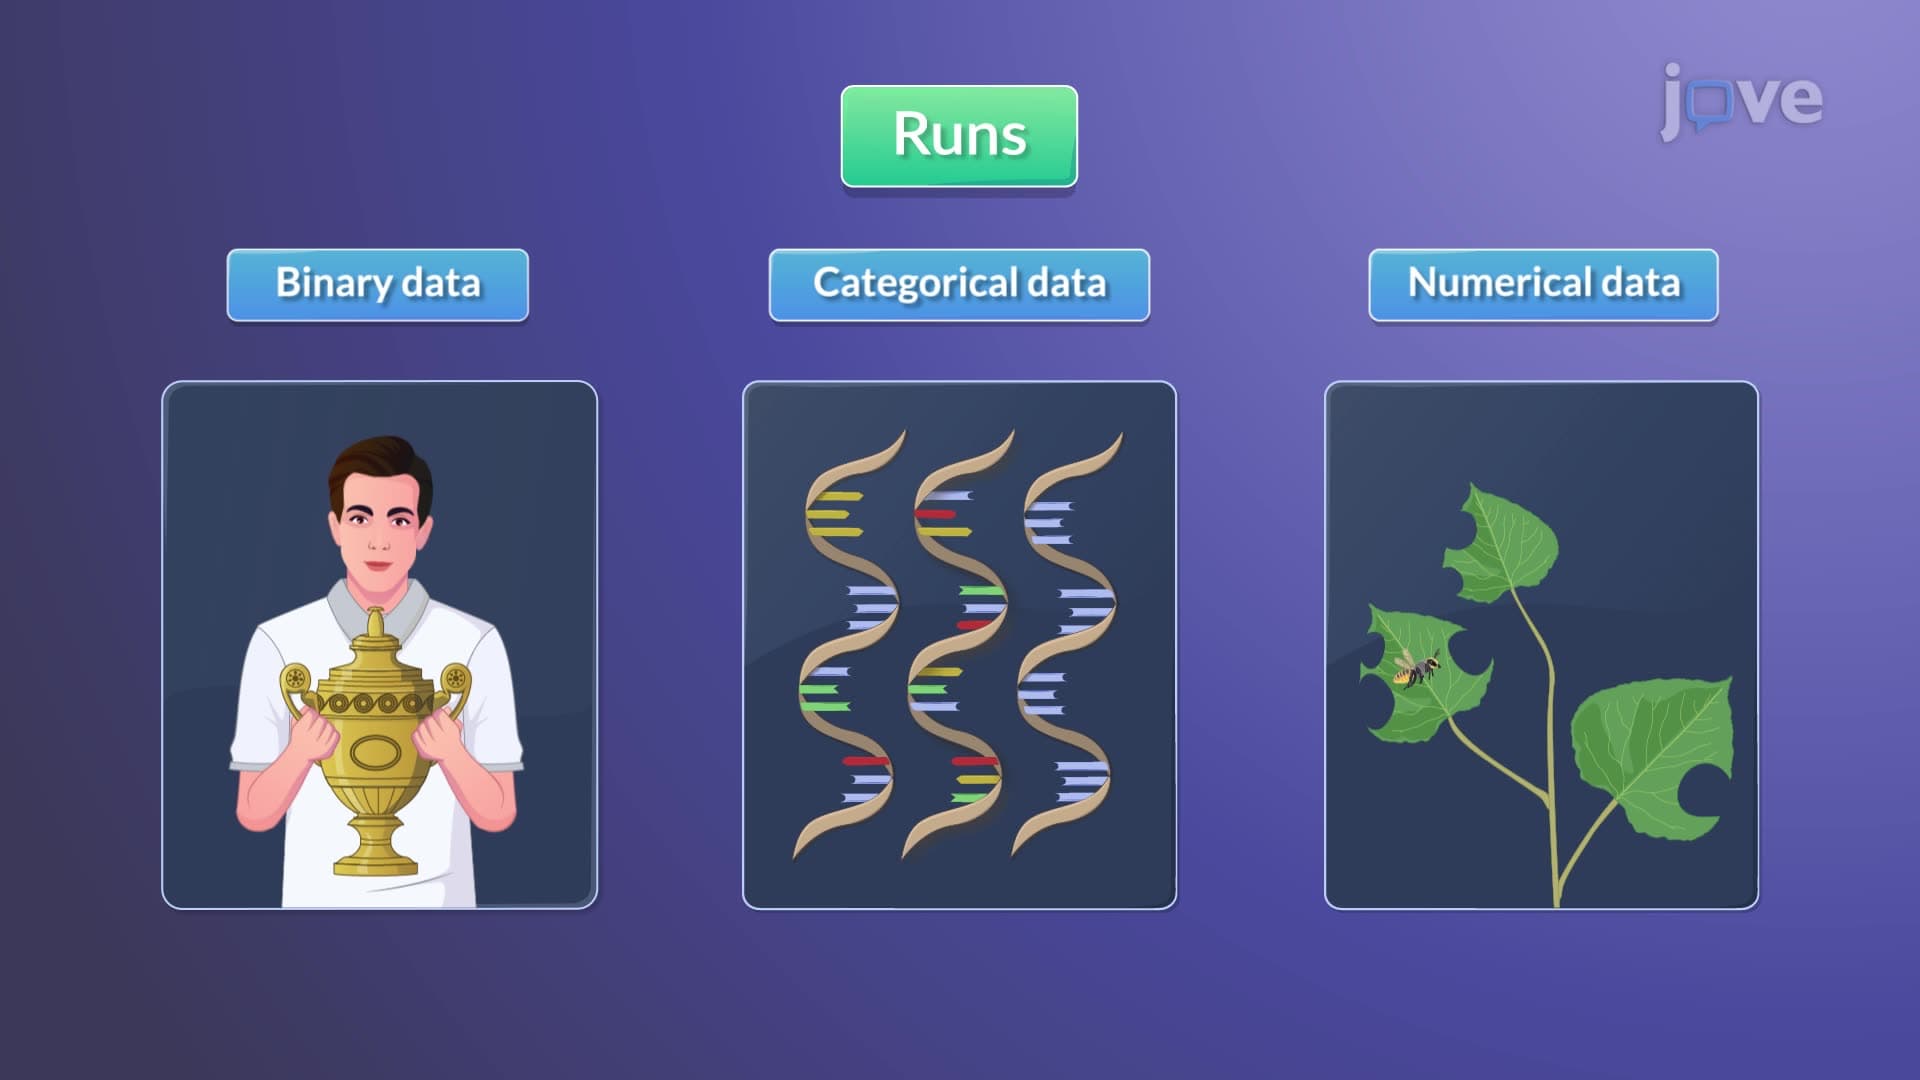
Wald-Wolfowitz Runs Test I01:17

Wald-Wolfowitz Runs Test I

The Wald-Wolfowitz test, also known as the runs test, is a nonparametric statistical test used to assess the randomness of a sequence of two different types of elements (e.g., positive/negative values, successes/failures). It examines whether the order of the elements in a sequence is random or if there is a pattern or trend present. This nonparametric test applies to any ordered data despite the population and sample data distribution, even if a higher sample size is available.
The test works...
Friedman Two-way Analysis of Variance by Ranks01:21

Friedman Two-way Analysis of Variance by Ranks

Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures from...