Sampling-theory approach to eigenwavefronts of imaging systems
Related Experiment Video
Updated: Aug 19, 2026
11:15
A Guide to Structured Illumination TIRF Microscopy at High Speed with Multiple Colors
Published on: May 30, 2016
1The Institute of Optics, University of Rochester, Rochester, New York 14627, USA. kedar@optics.rochester.edu

Abstract:
We present a direct method based on the sampling theorem for computing eigenwavefronts associated with linear space-invariant imaging systems (including aberrated imaging systems). A potential application of the eigenwavefronts to inverse problems in imaging is discussed. A noise-dependent measure for the information-carrying capacity of an imaging system is also proposed.
Related Concept Videos
 01:16
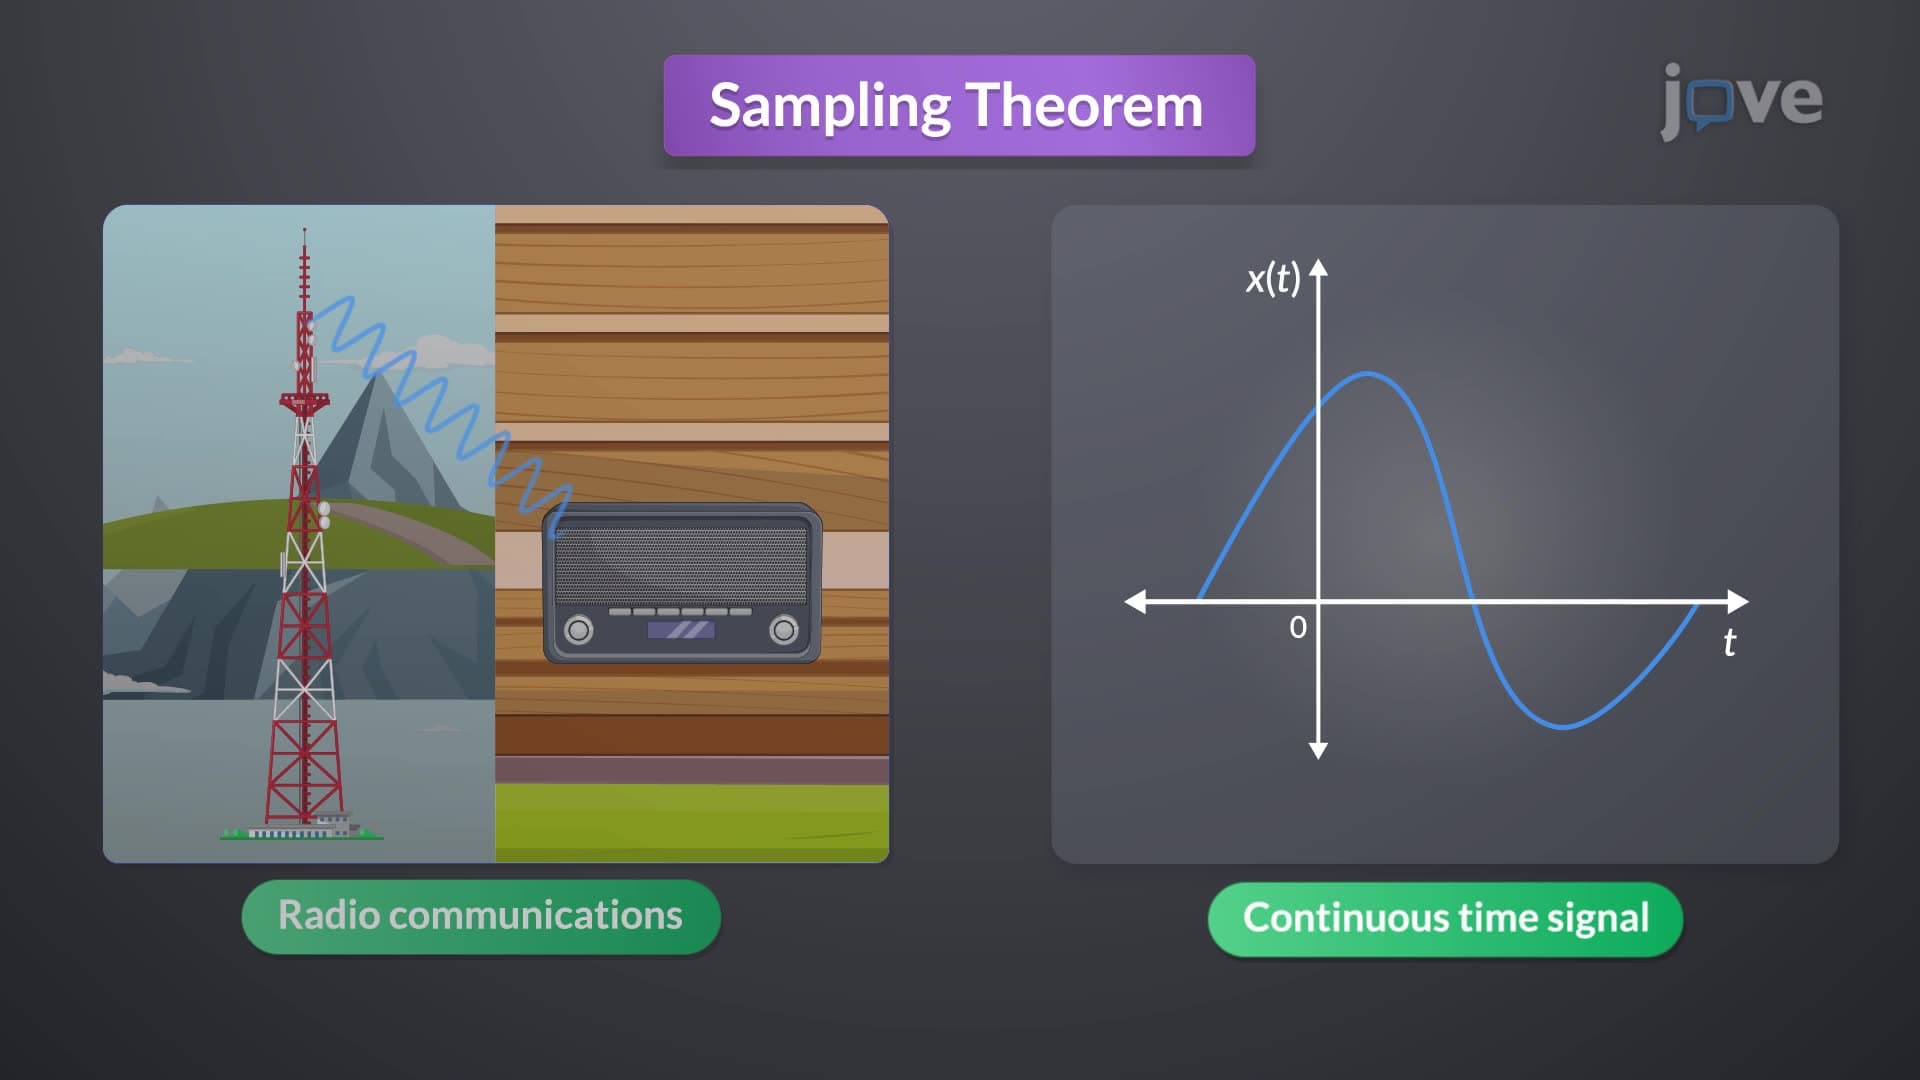
Sampling Theorem
In signal processing, the analysis of continuous-time signals, denoted as x(t), often involves sampling techniques to convert these signals into discrete-time signals. This process is essential for digital representation and manipulation. A critical component in sampling is the train of impulses, characterized by the sampling interval and the sampling frequency. The relationship between these parameters and the original signal's properties dictates the success of the sampling process.
 01:16
Contaminants and Errors
Effective sample preparation is crucial for accurate and reliable laboratory analysis. During this process, two significant sources of error can arise: concentration bias from improper sample splitting and contamination caused by methods used to reduce particle size, such as grinding or homogenization. Identifying and minimizing these potential errors is crucial to ensuring the validity of the analysis.
Another key consideration is determining the appropriate number of samples required to...
Another key consideration is determining the appropriate number of samples required to...
 01:18
Aliasing
Accurate signal sampling and reconstruction are crucial in various signal-processing applications. A time-domain signal's spectrum can be revealed using its Fourier transform. When this signal is sampled at a specific frequency, it results in multiple scaled replicas of the original spectrum in the frequency domain. The spacing of these replicas is determined by the sampling frequency.
If the sampling frequency is below the Nyquist rate, these replicas overlap, preventing the original signal...
If the sampling frequency is below the Nyquist rate, these replicas overlap, preventing the original signal...
 01:17
Wald-Wolfowitz Runs Test II
The Wald-Wolfowitz runs test, commonly referred to as the runs test, is a nonparametric test used to assess the randomness of ordered data. The test evaluates the number of runs, which are consecutive sequences of similar elements within the data. If the number of runs is significantly higher or lower than expected, the data is considered non-random, indicating a detectable pattern or structure.
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and 0s. In...
For binary data, runs are identified using symbols such as + and −, or equivalently, 1s and 0s. In...