Learning bounds for kernel regression using effective data dimensionality
Related Experiment Video
Updated: Aug 4, 2026

A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
1IBM T. J. Watson Research Center, Yorktown Heights, NY 10598, USA. tzhang@watson.ibm.com

Abstract:
Kernel methods can embed finite-dimensional data into infinite-dimensional feature spaces. In spite of the large underlying feature dimensionality, kernel methods can achieve good generalization ability. This observation is often wrongly interpreted, and it has been used to argue that kernel learning can magically avoid the "curse-of-dimensionality" phenomenon encountered in statistical estimation problems. This letter shows that although using kernel representation, one can embed data into an infinite-dimensional feature space; the effective dimensionality of this embedding, which determines the learning complexity of the underlying kernel machine, is usually small. In particular, we introduce an algebraic definition of a scale-sensitive effective dimension associated with a kernel representation. Based on this quantity, we derive upper bounds on the generalization performance of some kernel regression methods. Moreover, we show that the resulting convergent rates are optimal under various circumstances.
Related Concept Videos
 01:52
Regression Toward the Mean
 03:40
Dimensional Analysis
Conversion Factors and Dimensional Analysis
The unit...
 02:19
Dimensional Analysis
 01:23
Dimensional Analysis
Dimensional analysis allows us to analyze and compare physical quantities on a...
 01:08
Problem Solving: Dimensional Analysis
 01:27
Dimensional Analysis
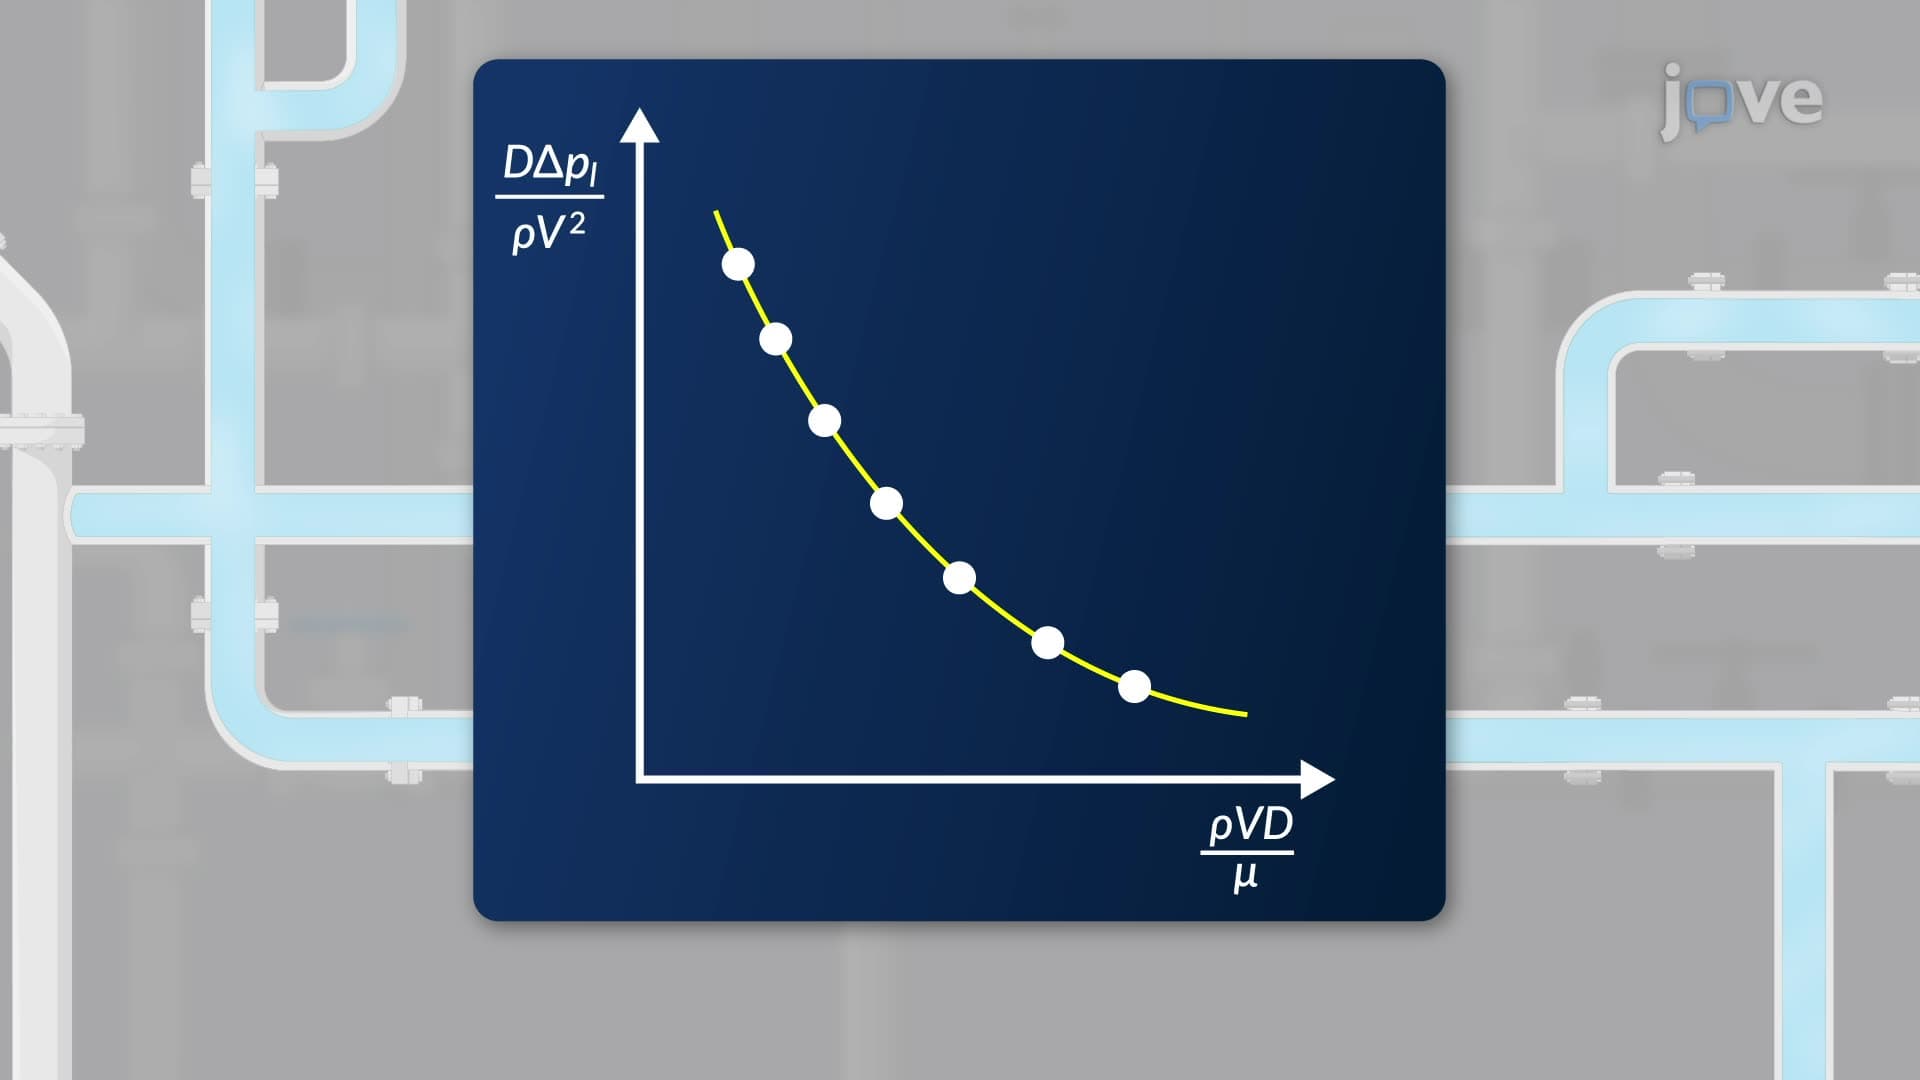
In fluid mechanics, dimensional...