Related Experiment Video
Updated: Aug 15, 2026
Deep Neural Networks for Image-Based Dietary Assessment
Published on: March 13, 2021
Learning curves for stochastic gradient descent in linear feedforward networks
Justin Werfel1, Xiaohui Xie, H Sebastian Seung
1Department of Electrical Engineering and Computer Science, Massachusetts Institute of Technology, Cambridge, MA 02139, USA. jkwerfel@mit.edu

Abstract:
Gradient-following learning methods can encounter problems of implementation in many applications, and stochastic variants are sometimes used to overcome these difficulties. We analyze three online training methods used with a linear perceptron: direct gradient descent, node perturbation, and weight perturbation. Learning speed is defined as the rate of exponential decay in the learning curves. When the scalar parameter that controls the size of weight updates is chosen to maximize learning speed, node perturbation is slower than direct gradient descent by a factor equal to the number of output units; weight perturbation is slower still by an additional factor equal to the number of input units. Parallel perturbation allows faster learning than sequential perturbation, by a factor that does not depend on network size. We also characterize how uncertainty in quantities used in the stochastic updates affects the learning curves. This study suggests that in practice, weight perturbation may be slow for large networks, and node perturbation can have performance comparable to that of direct gradient descent when there are few output units. However, these statements depend on the specifics of the learning problem, such as the input distribution and the target function, and are not universally applicable.
Related Concept Videos
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear.
 01:19
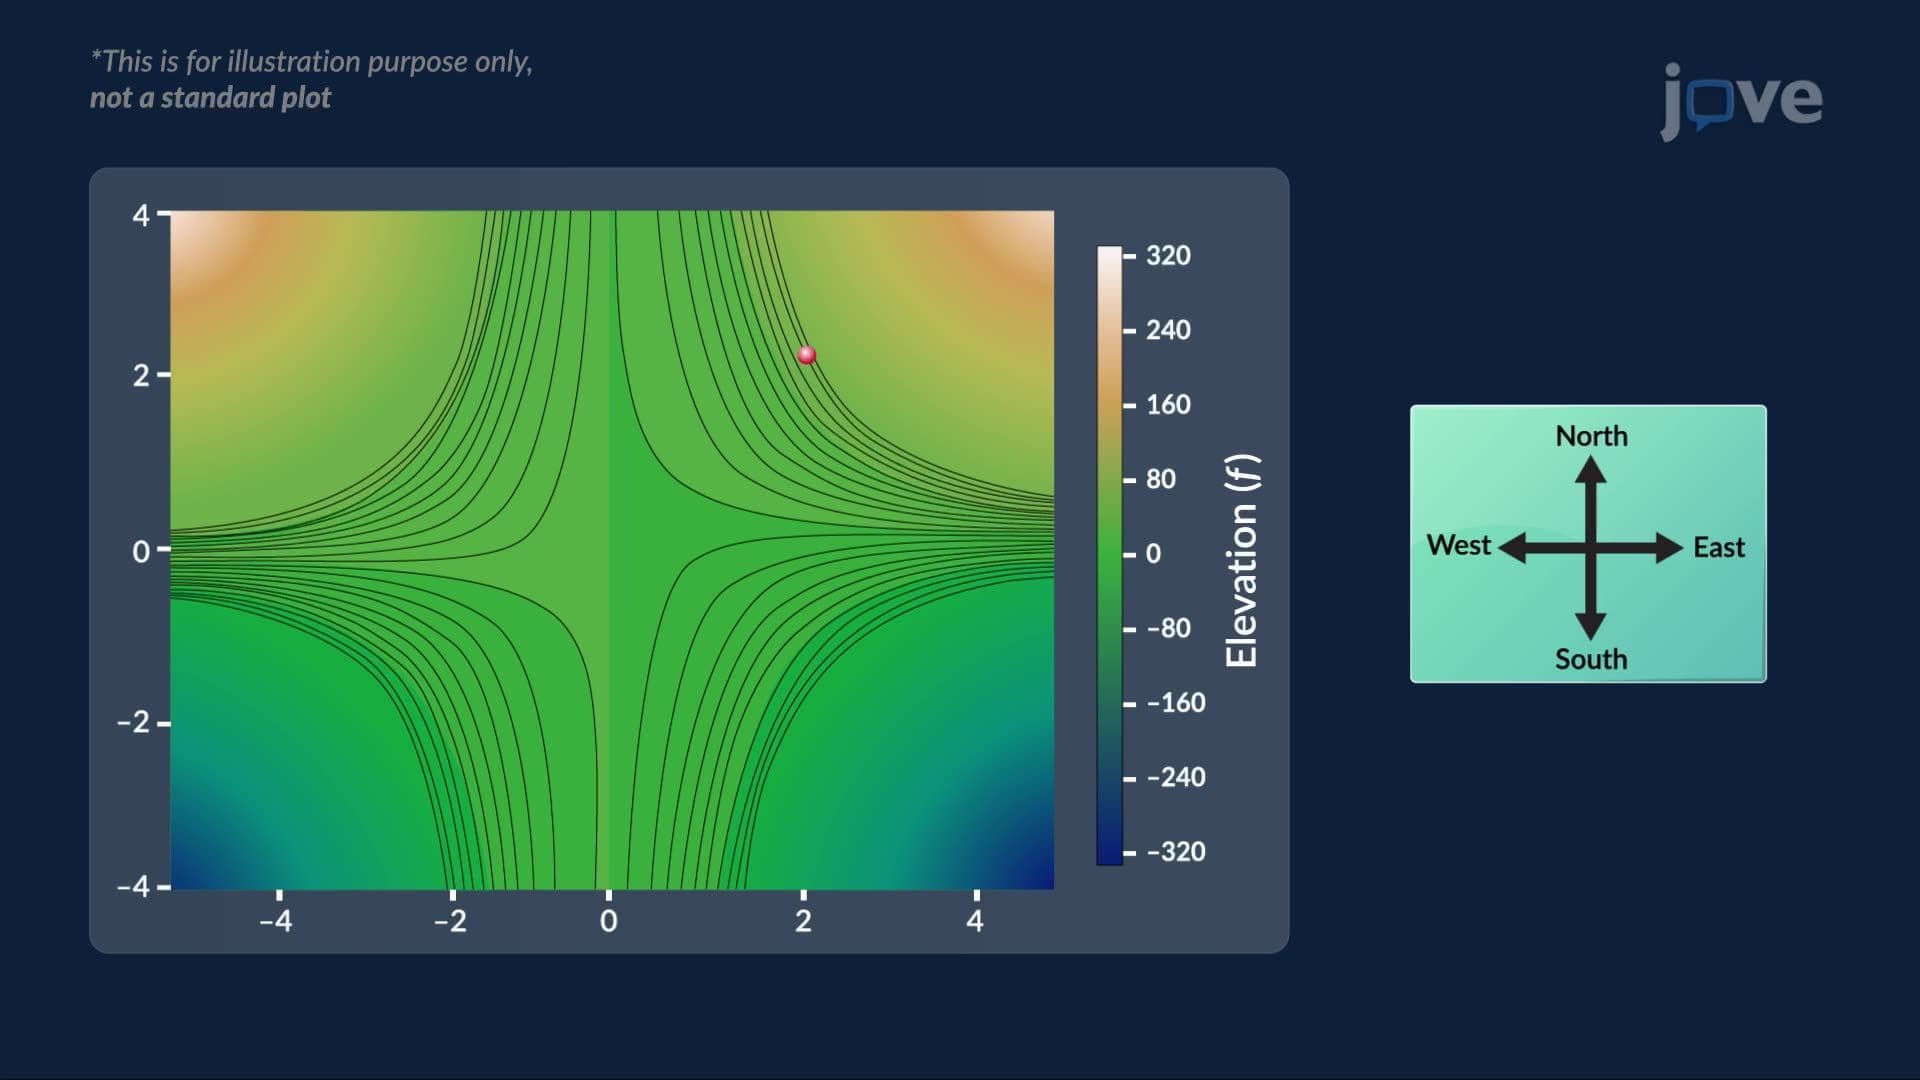
Gradient Vectors and Their Applications
 01:25
Maximizing the Directional Derivative
 01:13
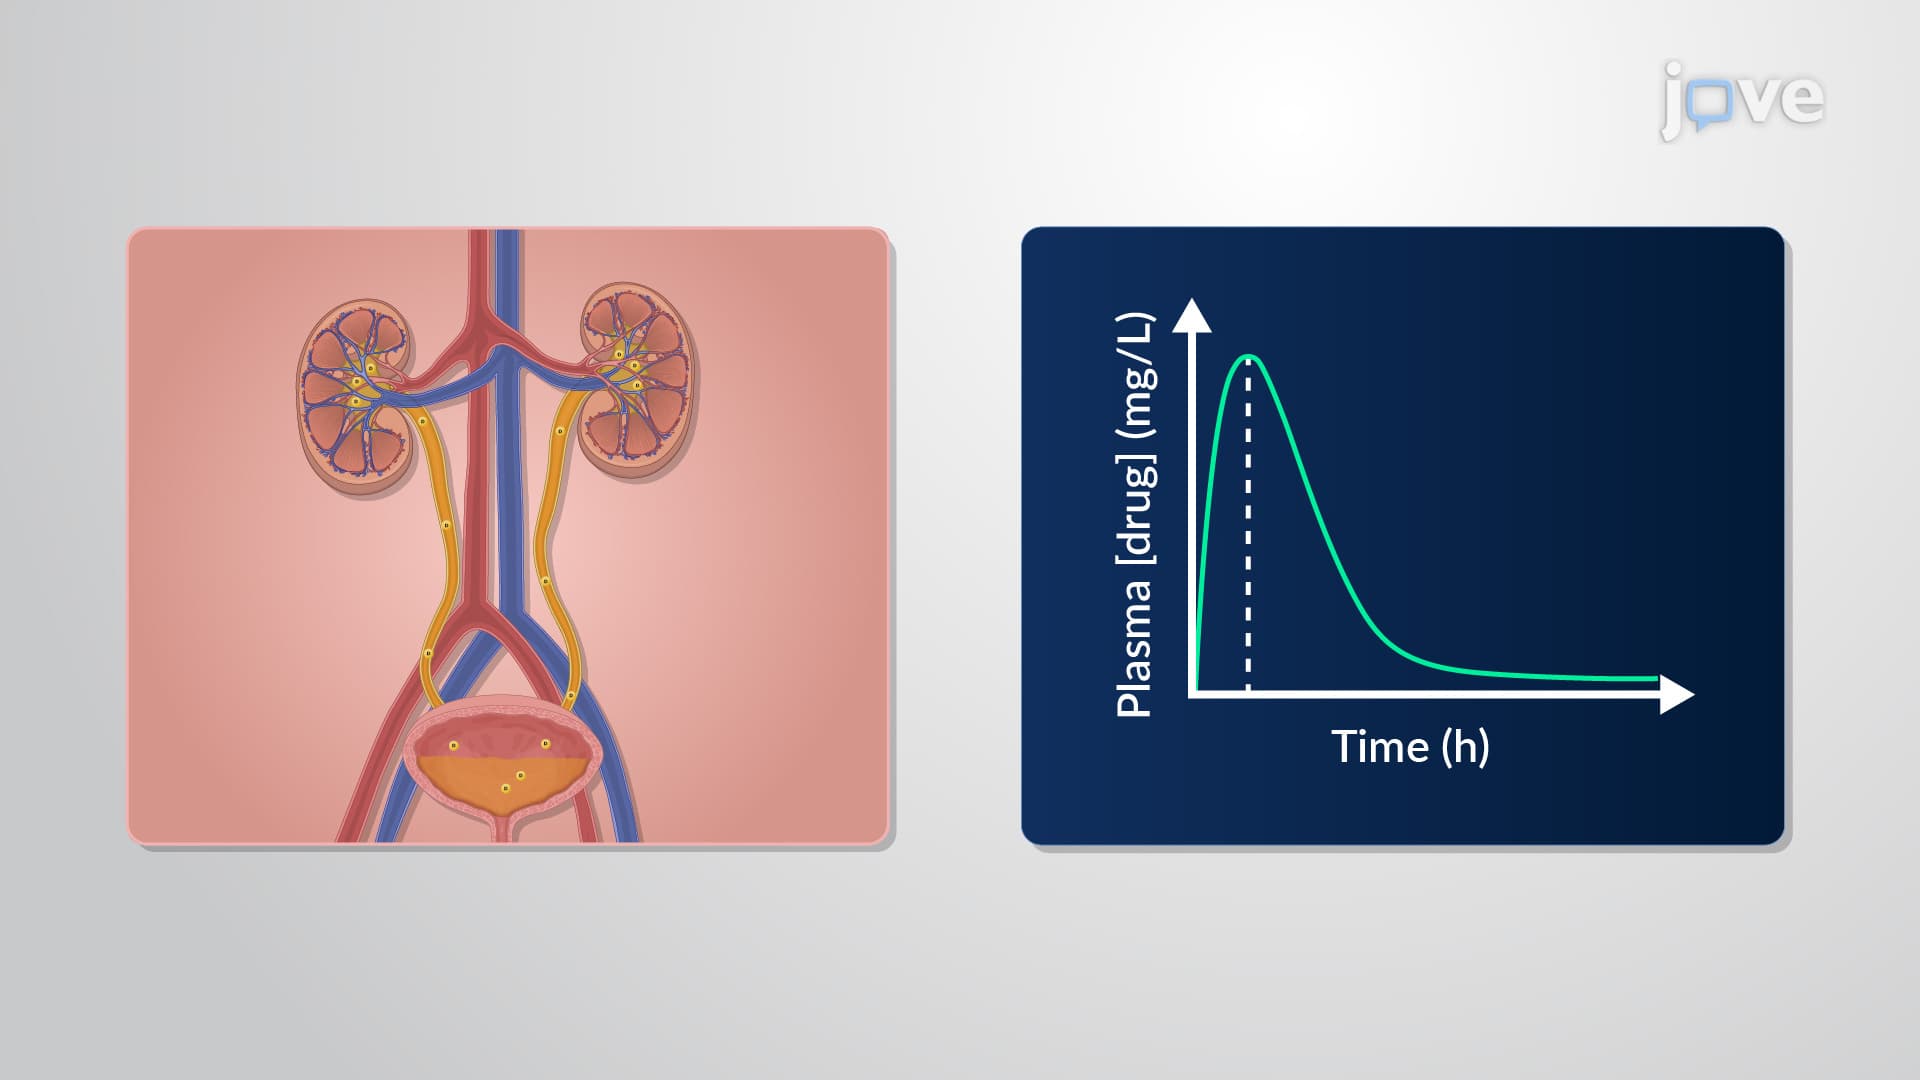
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
 01:27
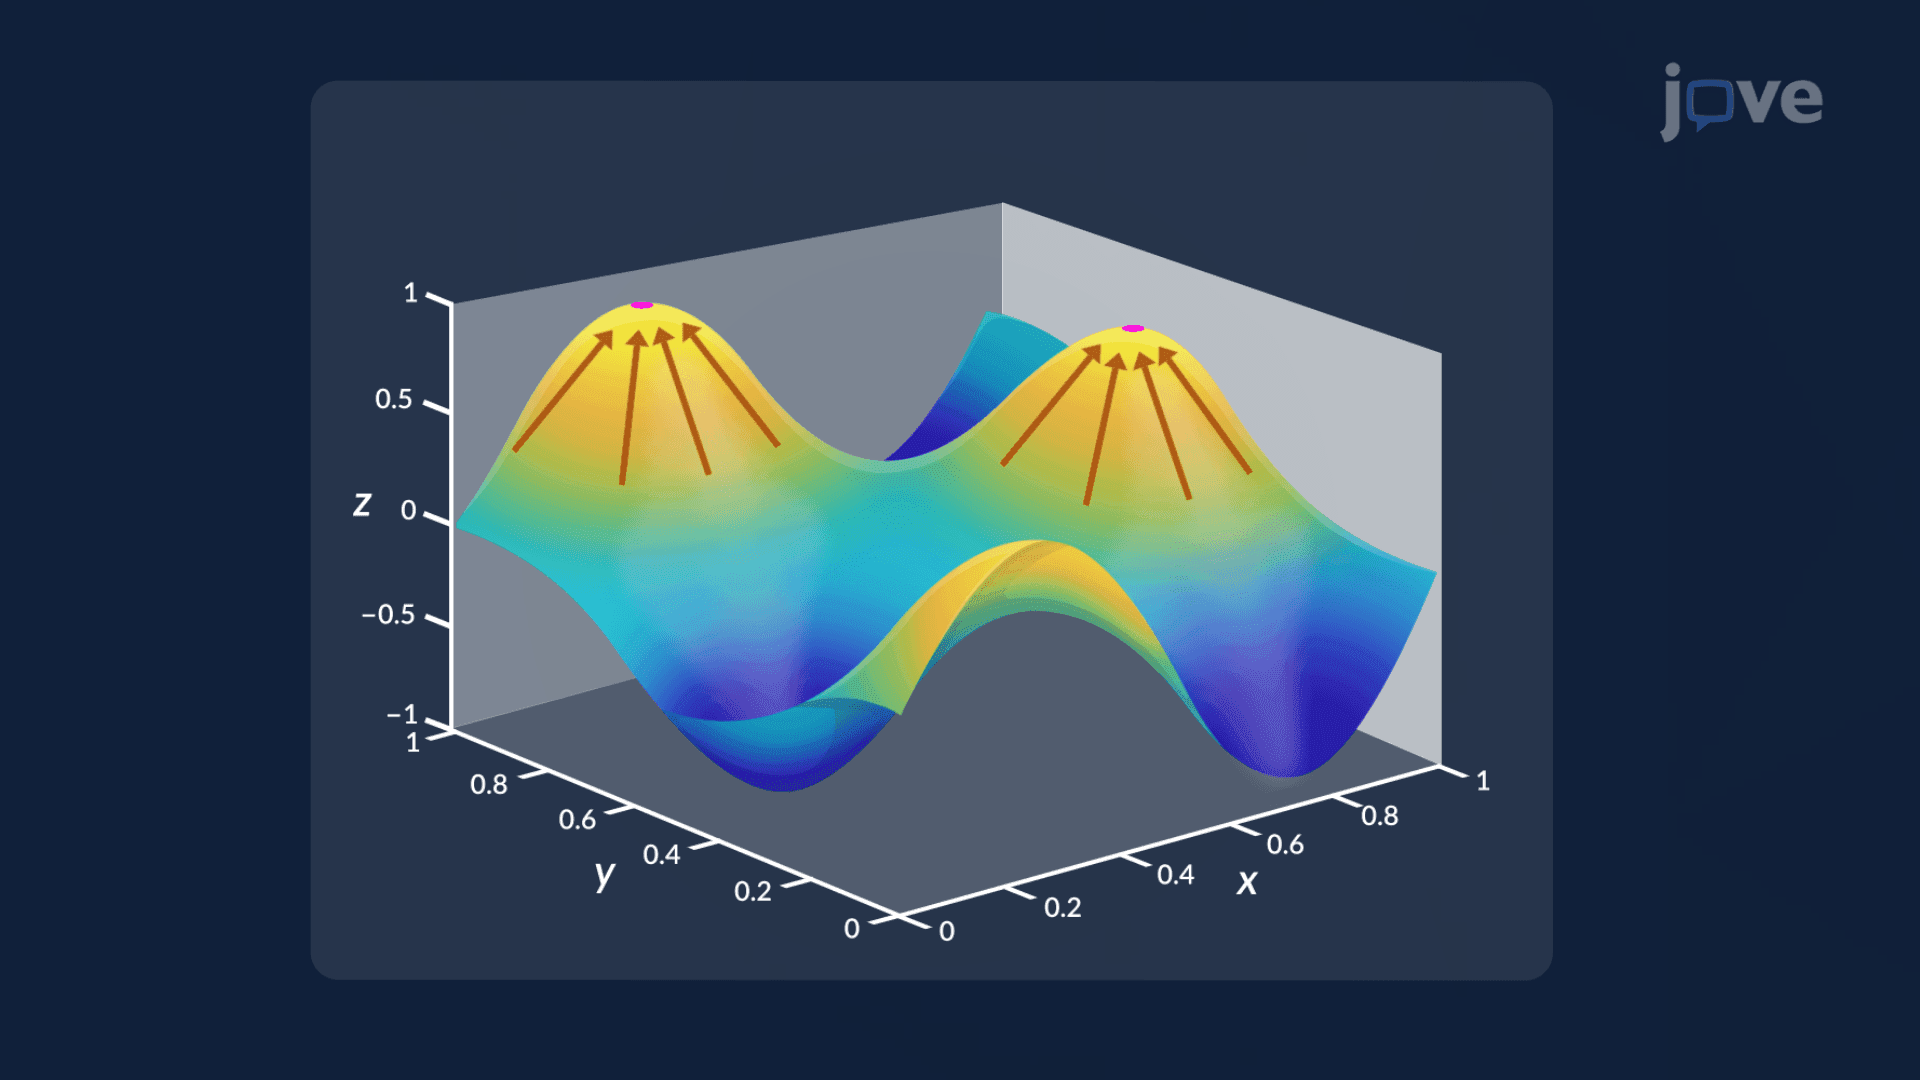
Significance of the Gradient Vector
 01:27
Linear Differential Equations