Related Experiment Video
Updated: Aug 14, 2026

An Integrated Approach for Microprotein Identification and Sequence Analysis
Published on: July 12, 2022
The evolution of peptide deformylase as a target: contribution of biochemistry, genetics and genomics
Zhengyu Yuan1, Richard J White
1Vicuron Pharmaceuticals Inc., 34790 Ardentech Court, Fremont, CA 94555, USA.

Abstract:
Although peptide deformylase (PDF, EC 3.5.1.27) was first described in 1968, the instability of enzyme preparations prevented it from being seriously considered as a target until this problem was finally solved in 1998. PDFs essentiality was first demonstrated in Escherichia coli in 1994. Genomic analyses have shown this enzyme to be present in all eubacteria. PDF homologs have also been found in eukaryotes including Homo sapiens. The function and relevance of the human chromosomal homolog to the safety of PDF inhibitors as therapeutic agents is not clear at this stage. Although there is considerable sequence variation between the different bacterial PDFs, there are three strongly conserved motifs that together constitute a critical metal binding site. The observation that PDF is a metalloenzyme has led to the design of inhibitors containing metal chelating pharmacophores. The most potent of these synthetic inhibitors are active against a range of clinically relevant respiratory tract pathogens in vitro and in vivo, including those resistant to current antibiotics. Mutants resistant to PDF inhibitors have been obtained in the laboratory; these resulted from mutations in the genes for transformylase (EC 2.1.2.9) or PDF. The mechanism involved and its frequency were pathogen-dependent. The two most advanced PDF inhibitor leads, which are both reverse hydroxamates, have progressed to phase 1 clinical trials and were well tolerated.
Related Concept Videos
 01:29
Pharmacogenomics: Identification of New Drug Targets
 02:11
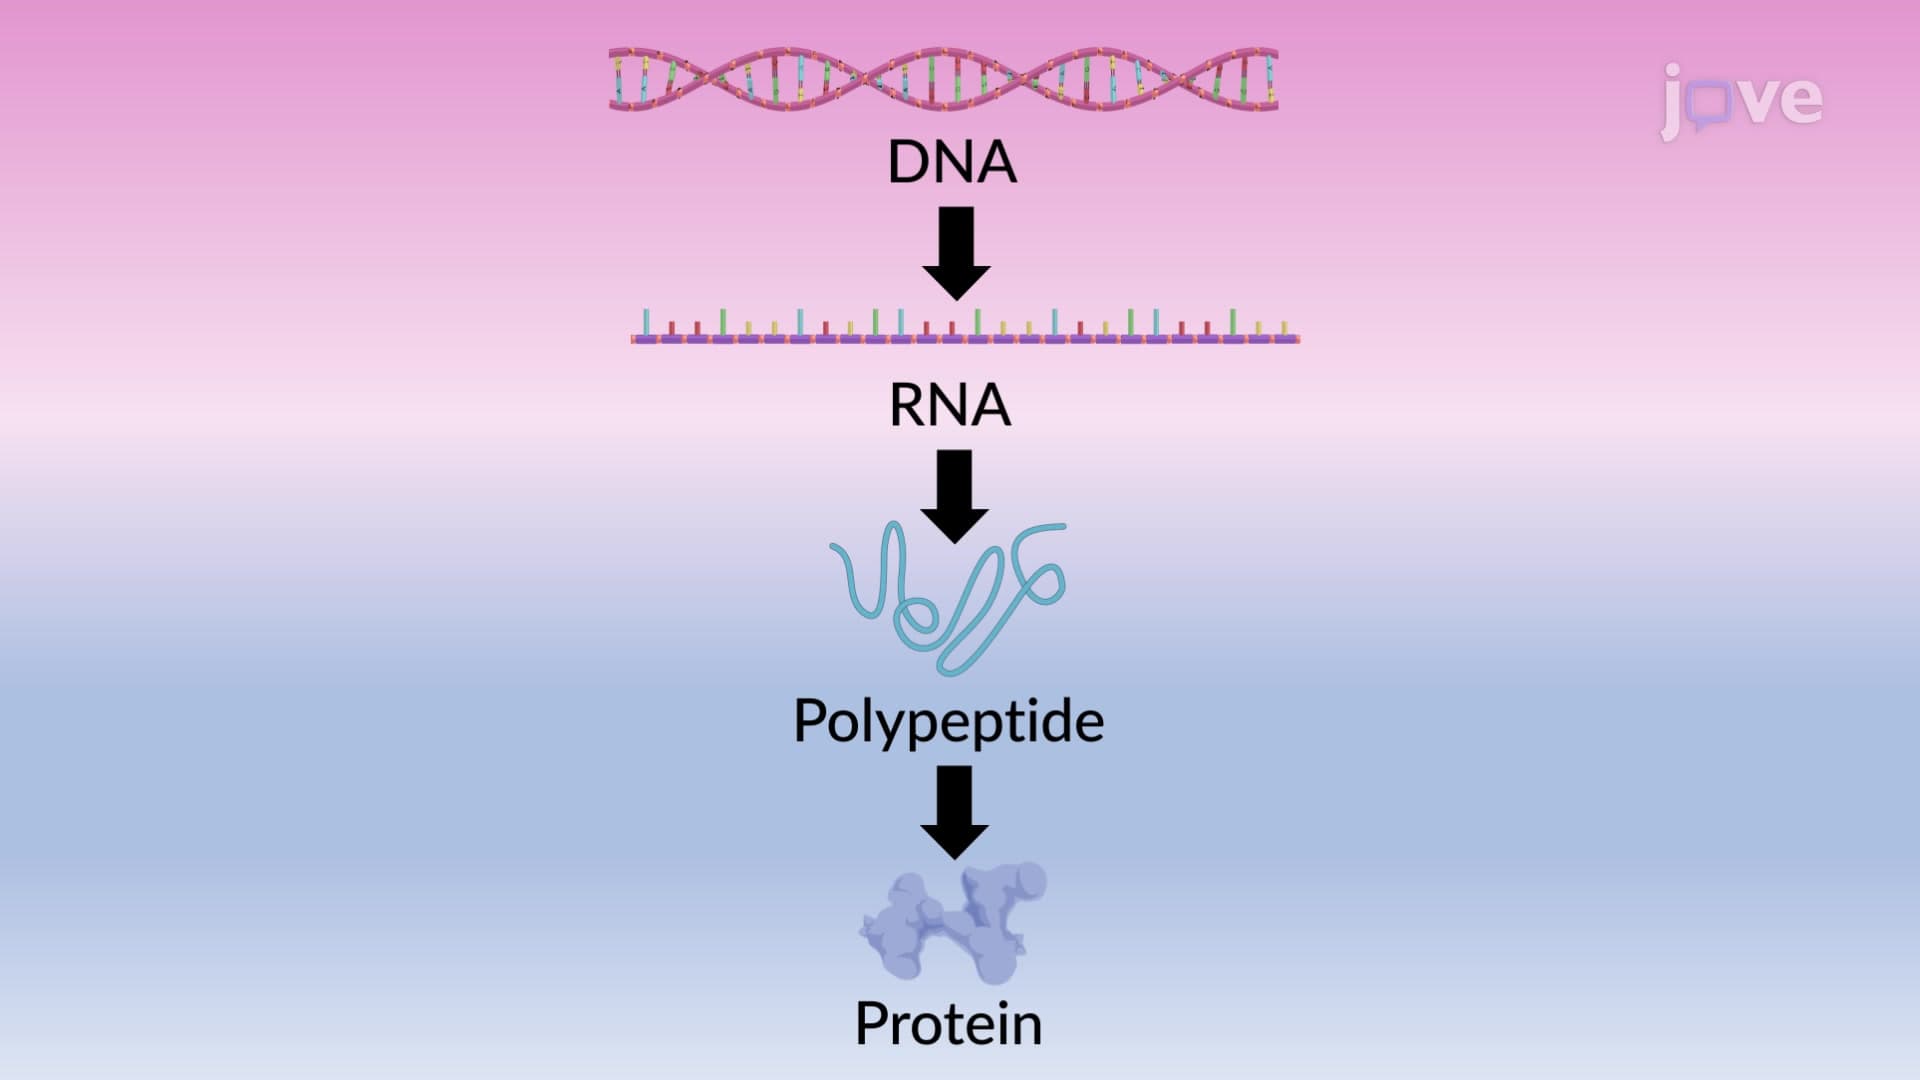
Proteins: From Genes to Degradation
Transcription is the synthesis of RNA molecules by RNA...
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:20
The Central Dogma
RNA is the Missing Link Between DNA and Proteins
In the early 1900s, scientists discovered that DNA stores all the information needed for cellular functions and that proteins perform most of these functions. However, the mechanisms of converting genetic information into functional proteins remained unknown for many years. Initially, it was believed that a single gene is...
 01:11
Pharmacogenetics of Drug Targets: β₂-Adrenergic Receptors, Apo E, Thymidylate Synthase
 01:17
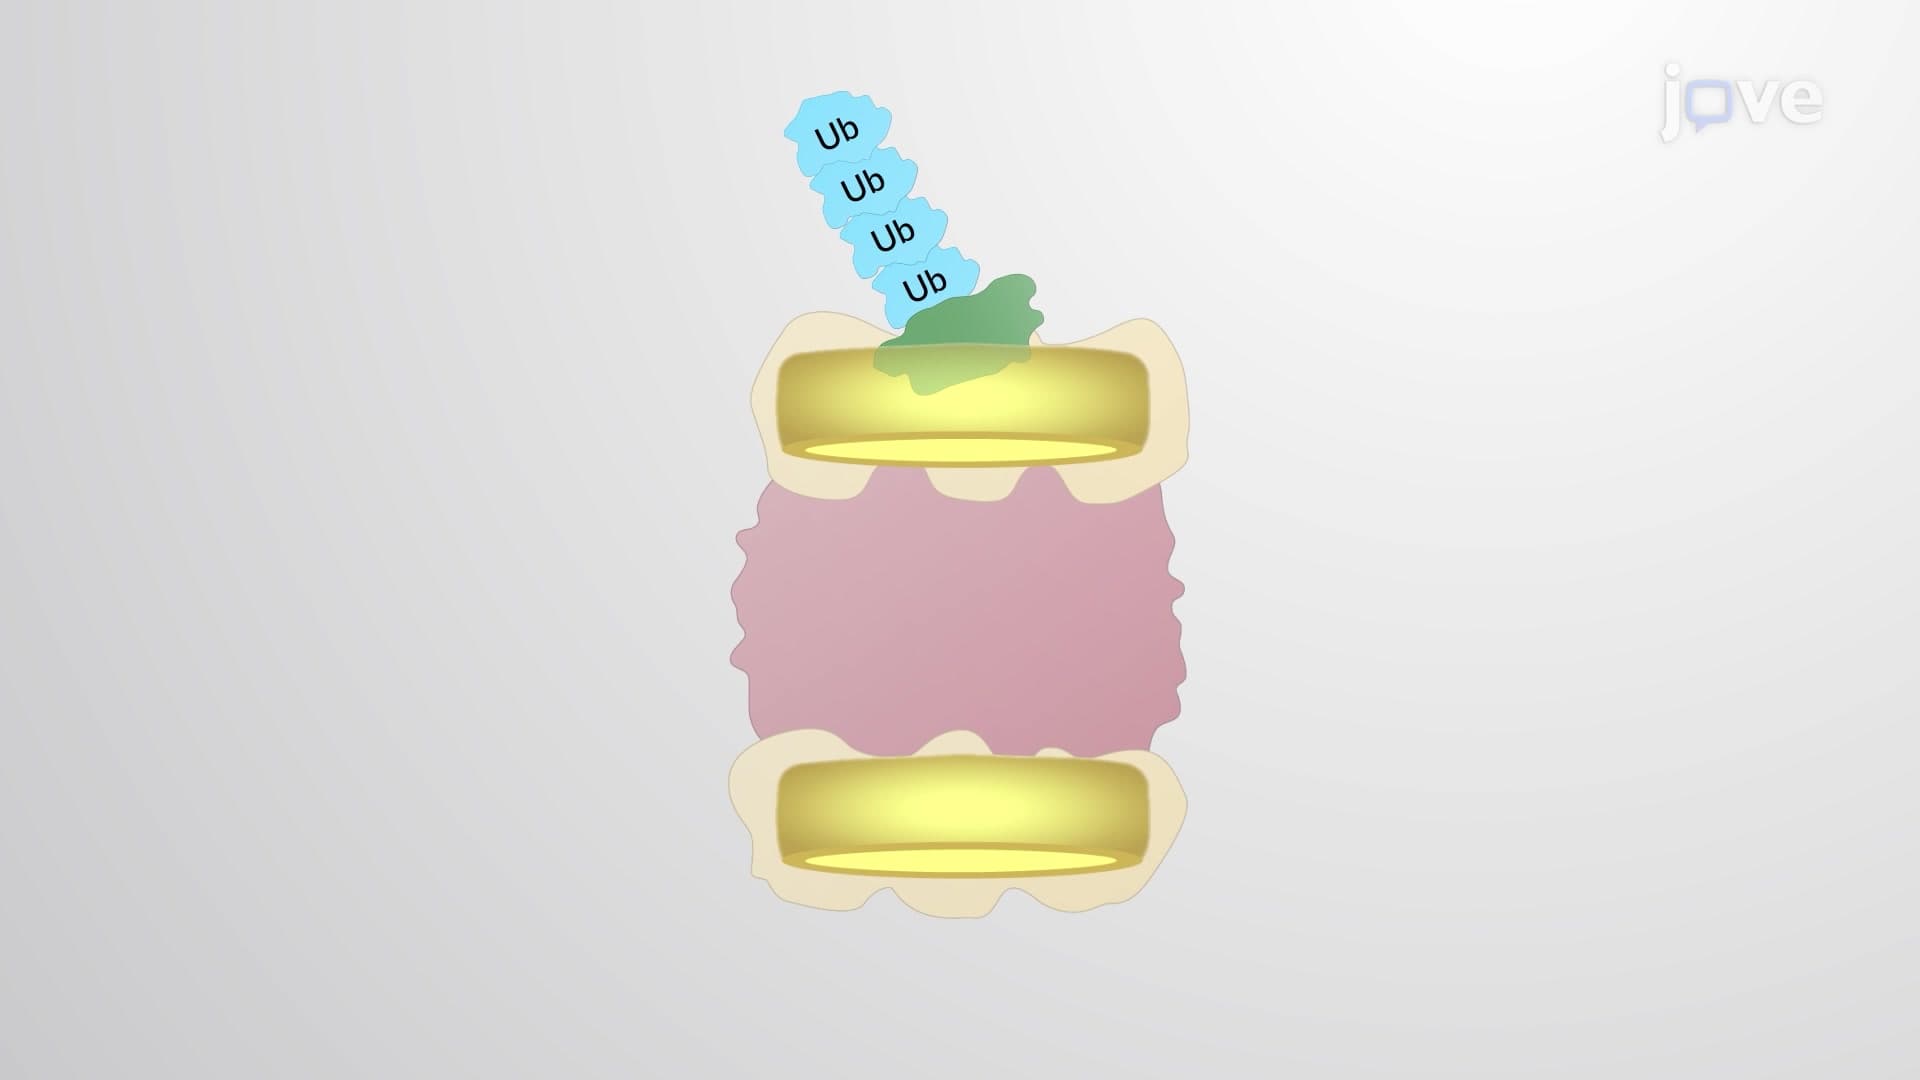
The Proteasome Structure
The proteasome is an...