Related Experiment Video
Updated: Jul 20, 2026


A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
A self-similarity model for the occupancy frequency distribution
1Spatial, Physiological and Conservation Ecology Group, Department of Conservation Ecology and Entomology, University of Stellenbosch, Private Bag X1, Matieland 7602, South Africa. chui@sun.ac.za

Abstract:
The shapes of interspecific range-size distributions at scales finer than the geographic range are highly variable. However, no numerical model has been developed as a basis for understanding this variation. Using self-similarity conditions, we present an occupancy probability transition (OPT) model to investigate the effect of sampling scale (i.e. sample grain) and species saturation (strongly positively correlated with the fractal dimension) on the shape of occupancy frequency distributions (fine scale expression of range-size distributions). In accordance with empirical observations, the model showed that core-modes are likely to be rare in occupancy frequency distributions. The modal occupancy shifted from core to satellite with an increase in sample grain (from coarse scale to fine scale) at a linear rate after log-transformation of occupancy. Saturation coefficients above a particular threshold generated multimodality. Bimodal distributions arose from a combination of different occupancy probability distributions (OPDs), with species-specific saturation coefficients generating occupancy frequency distributions of the shape commonly observed empirically, i.e. bimodal with a dominant satellite mode. This is a consequence of the statistical properties of the OPD, and is also largely insensitive to species richness. The OPT model thus provides a null model for the shape of occupancy frequency distributions. Furthermore, it demonstrates that the sample grain of a study, sampling adequacy (based on a linear sampling assumption) and the distribution of species saturation coefficients in a community are together largely able to explain the patterns observed in empirical occupancy frequency distributions.
Related Concept Videos
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 00:55
Relative Frequency Distribution
 01:17
Probability Histograms
 01:16
Goodness-of-Fit Test
 01:08
Determination of Expected Frequency
 01:15
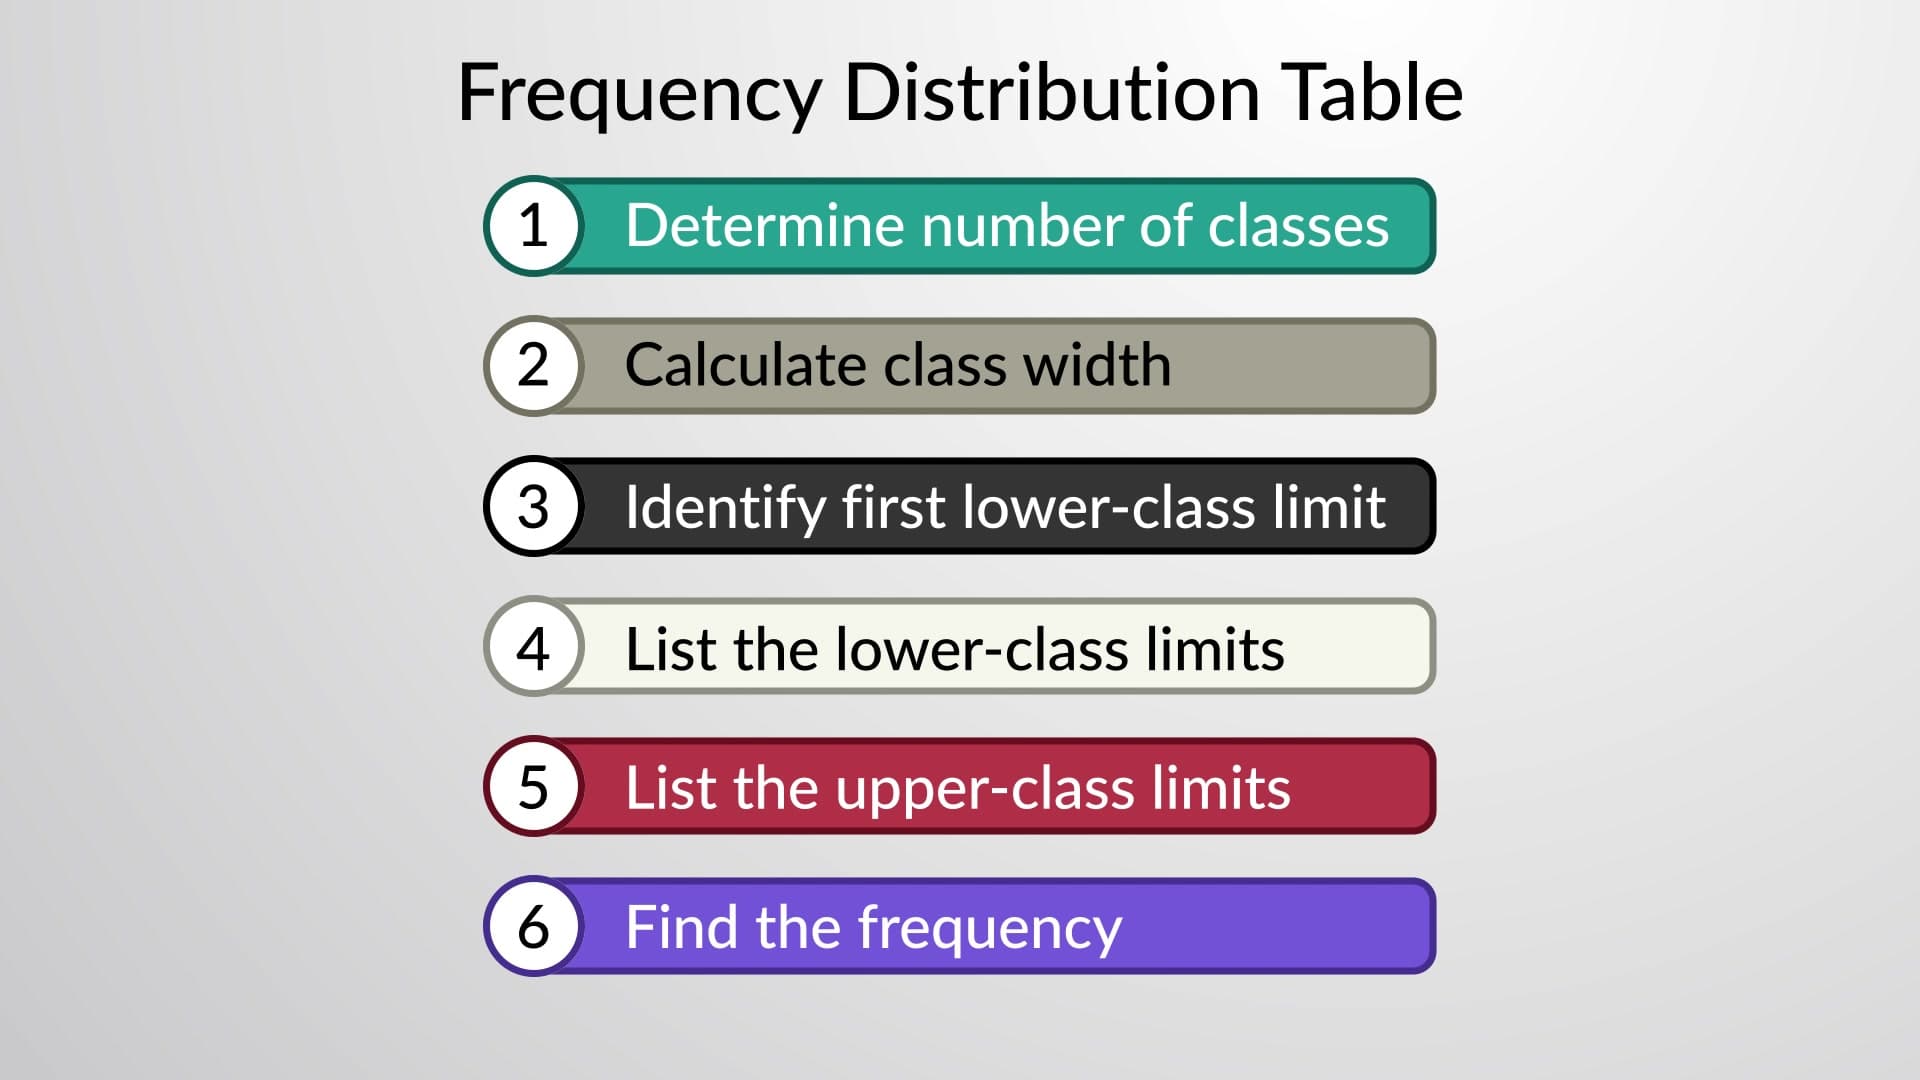
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is best to...