Computational basis of knowledge-based conformational probabilities derived from local- and long-range interactions in proteins
Related Experiment Video
Updated: Jul 19, 2026

Optimization of Synthetic Proteins: Identification of Interpositional Dependencies Indicating Structurally and/or Functionally Linked Residues
Published on: July 14, 2015
Lerzan Ormeci1, Attila Gursoy, Guzin Tunca
1College of Engineering, Koc University, Rumelifeneri Yolu, 34450 Sariyer, Istanbul, Turkey.

Abstract:
The probabilities of the various basins in Ramachandran maps are examined critically. The theoretical basis of probability calculations both from molecular computations and from protein libraries are discussed. The well-defined basins of the Ramachandran maps are treated as rotational isomeric states. Statistical independence and dependence of the states of different residues along the peptide chain are discussed. The Flory isolated pair hypothesis, near neighbor correlations, context effects, and long-range correlations are examined critically. A method of evaluating long-range correlations in helical and extended sequences is introduced in analogy with earlier polymer theory. Three different protein libraries are constructed where data is considered from residues in the (i) coiled regions, (ii) all regions, and (iii) only the helical and extended regions of proteins. Singlet and pairwise dependent probabilities calculated from these libraries are used to predict whether a given sequence is helical or extended. Predictions using pairwise dependence were not better than those using singlet probabilities. Modeling of long-range correlations improved the predictions significantly. Removal of the Chameleon sequences from the data set also improved the predictions, but to a lesser extent.


Related Concept Videos
 01:24
Protein Organization
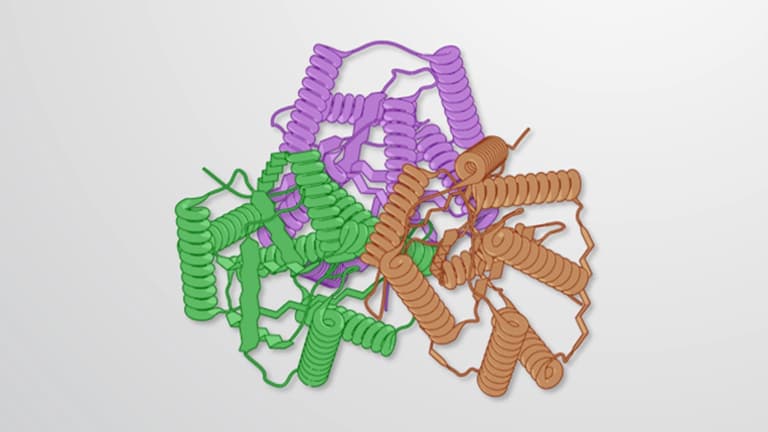
The primary structure of a protein is its amino acid sequence.
 01:13
Protein Organization
01:13Protein Organization
01:24Protein Organization
The primary structure of a protein is its amino acid sequence.
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
01:49Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...