Scalable data servers for large multivariate volume visualization
Related Experiment Video
Updated: Jul 19, 2026
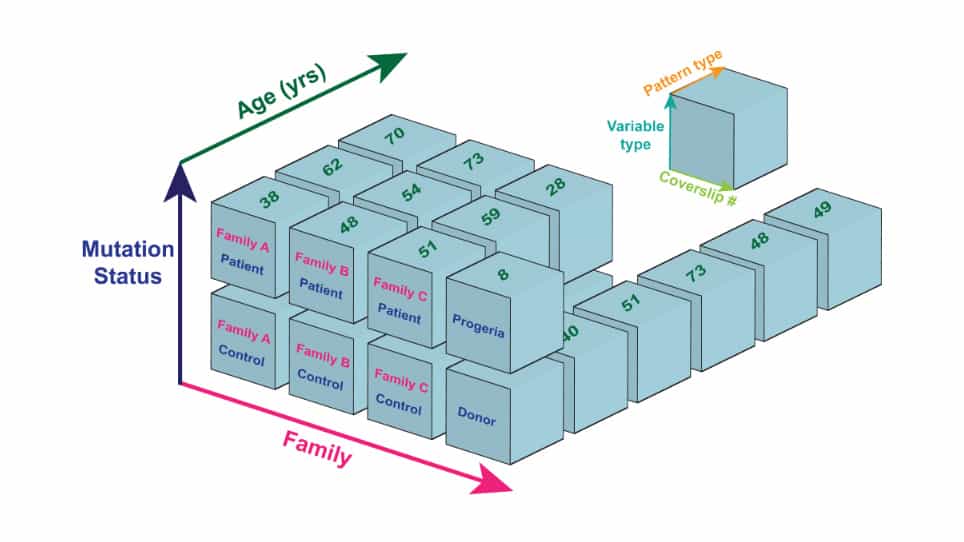
Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Markus Glatter1, Colin Mollenhour, Jian Huang
1The University of Tennessee, USA. glatter@cs.utk.edu

Abstract:
Volumetric datasets with multiple variables on each voxel over multiple time steps are often complex, especially when considering the exponentially large attribute space formed by the variables in combination with the spatial and temporal dimensions. It is intuitive, practical, and thus often desirable, to interactively select a subset of the data from within that high-dimensional value space for efficient visualization. This approach is straightforward to implement if the dataset is small enough to be stored entirely in-core. However, to handle datasets sized at hundreds of gigabytes and beyond, this simplistic approach becomes infeasible and thus, more sophisticated solutions are needed. In this work, we developed a system that supports efficient visualization of an arbitrary subset, selected by range-queries, of a large multivariate time-varying dataset. By employing specialized data structures and schemes of data distribution, our system can leverage a large number of networked computers as parallel data servers, and guarantees a near optimal load-balance. We demonstrate our system of scalable data servers using two large time-varying simulation datasets.
Related Concept Videos
 01:21
Introduction to Scalers
Scalar...
 01:10
Statgraphics
 01:23
GIS Software, Hardware, and Sources of GIS Data
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:26
Scaling
 01:14
Scale-Up Processes