Related Experiment Video
Updated: Jul 14, 2026


Applying an eMASS Customization Program as a Research Tool to Evaluate Consumer Benefits
Published on: September 27, 2019
Constructing second-order accurate confidence intervals for communalities in factor analysis
Masanori Ichikawa1, Sadanori Konishi
1Tokyo University of Foreign Studies, Japan. ichikawa.m@tufs.ac.jp

Abstract:
In an effort to find accurate alternatives to the usual confidence intervals based on normal approximations, this paper compares four methods of generating second-order accurate confidence intervals for non-standardized and standardized communalities in exploratory factor analysis under the normality assumption. The methods to generate the intervals employ, respectively, the Cornish-Fisher expansion and the approximate bootstrap confidence (ABC), and the bootstrap-t and the bias-corrected and accelerated bootstrap (BC(a)). The former two are analytical and the latter two are numerical. Explicit expressions of the asymptotic bias and skewness of the communality estimators, used in the analytical methods, are derived. A Monte Carlo experiment reveals that the performance of central intervals based on normal approximations is a consequence of imbalance of miscoverage on the left- and right-hand sides. The second-order accurate intervals do not require symmetry around the point estimates of the usual intervals and achieve better balance, even when the sample size is not large. The behaviours of the second-order accurate intervals were similar to each other, particularly for large sample sizes, and no method performed consistently better than the others.
Related Concept Videos
 01:19
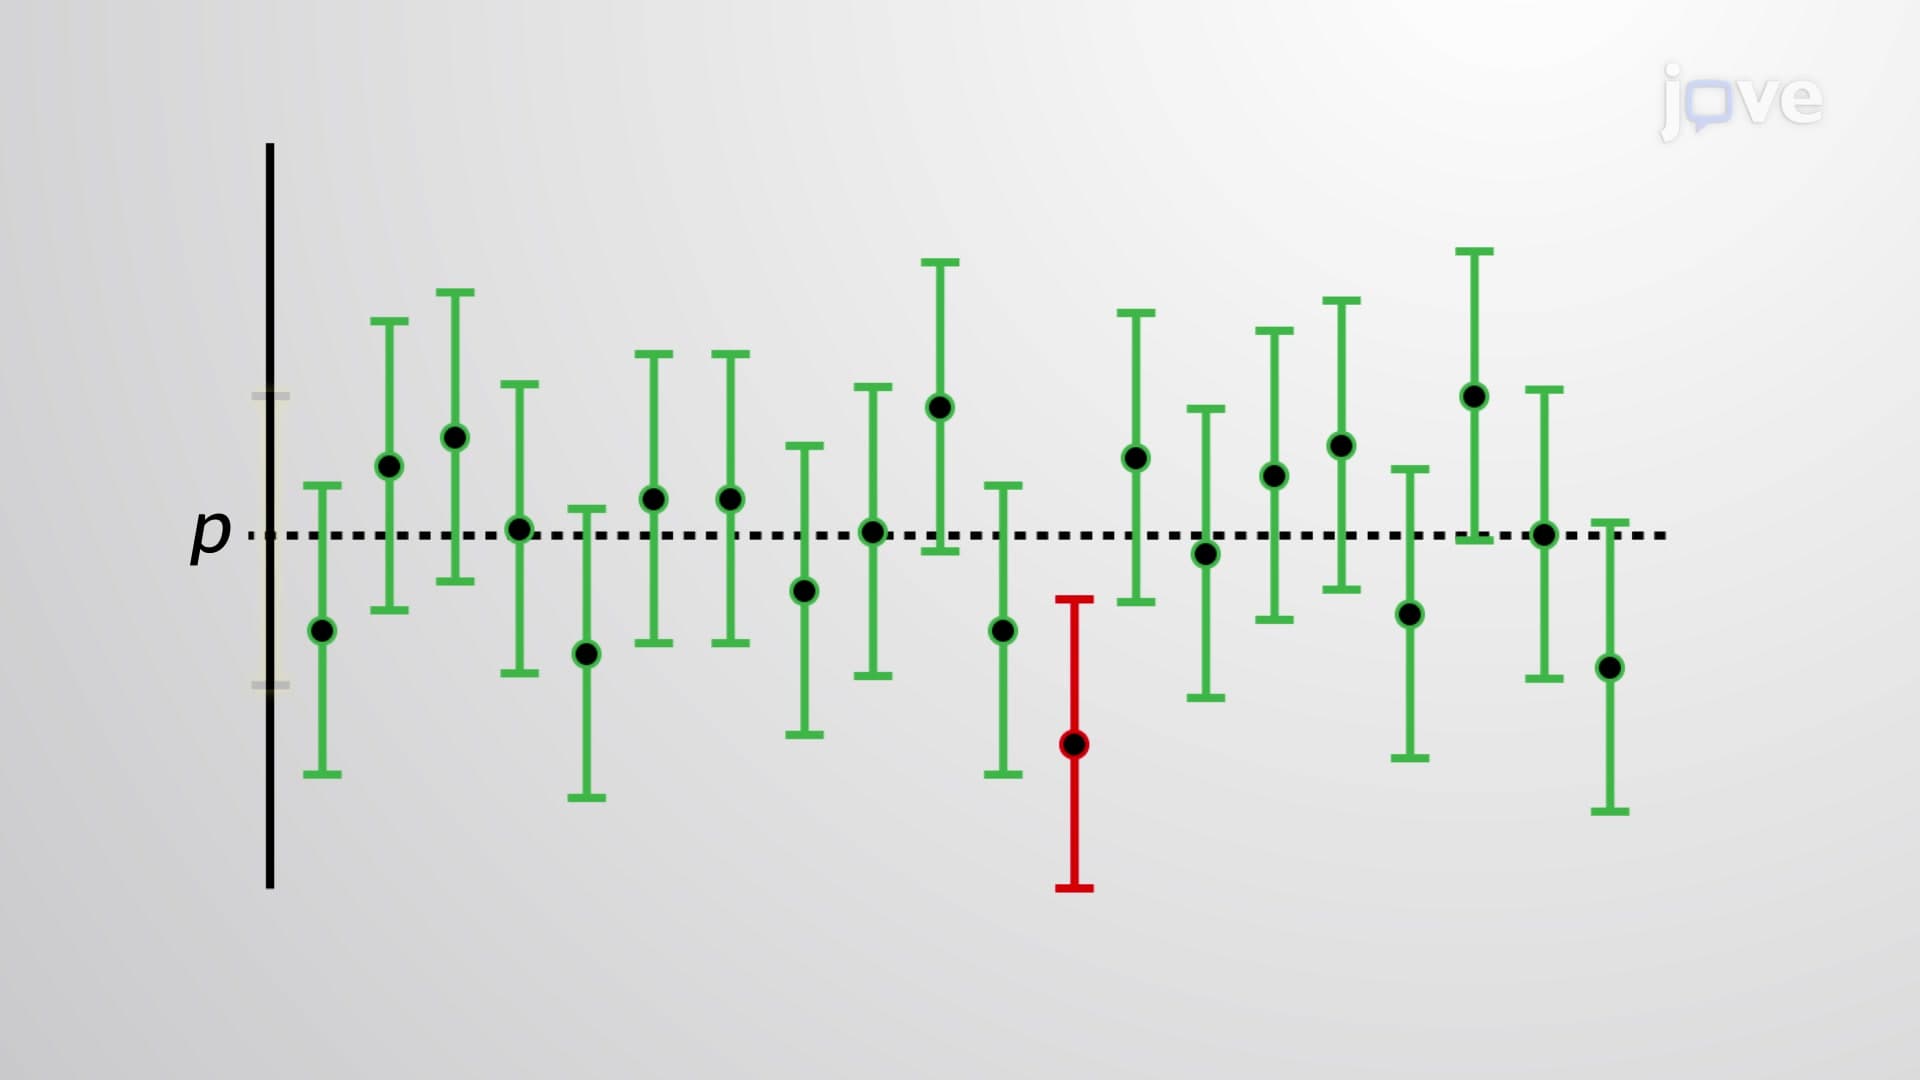
Interpretation of Confidence Intervals
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
 01:21
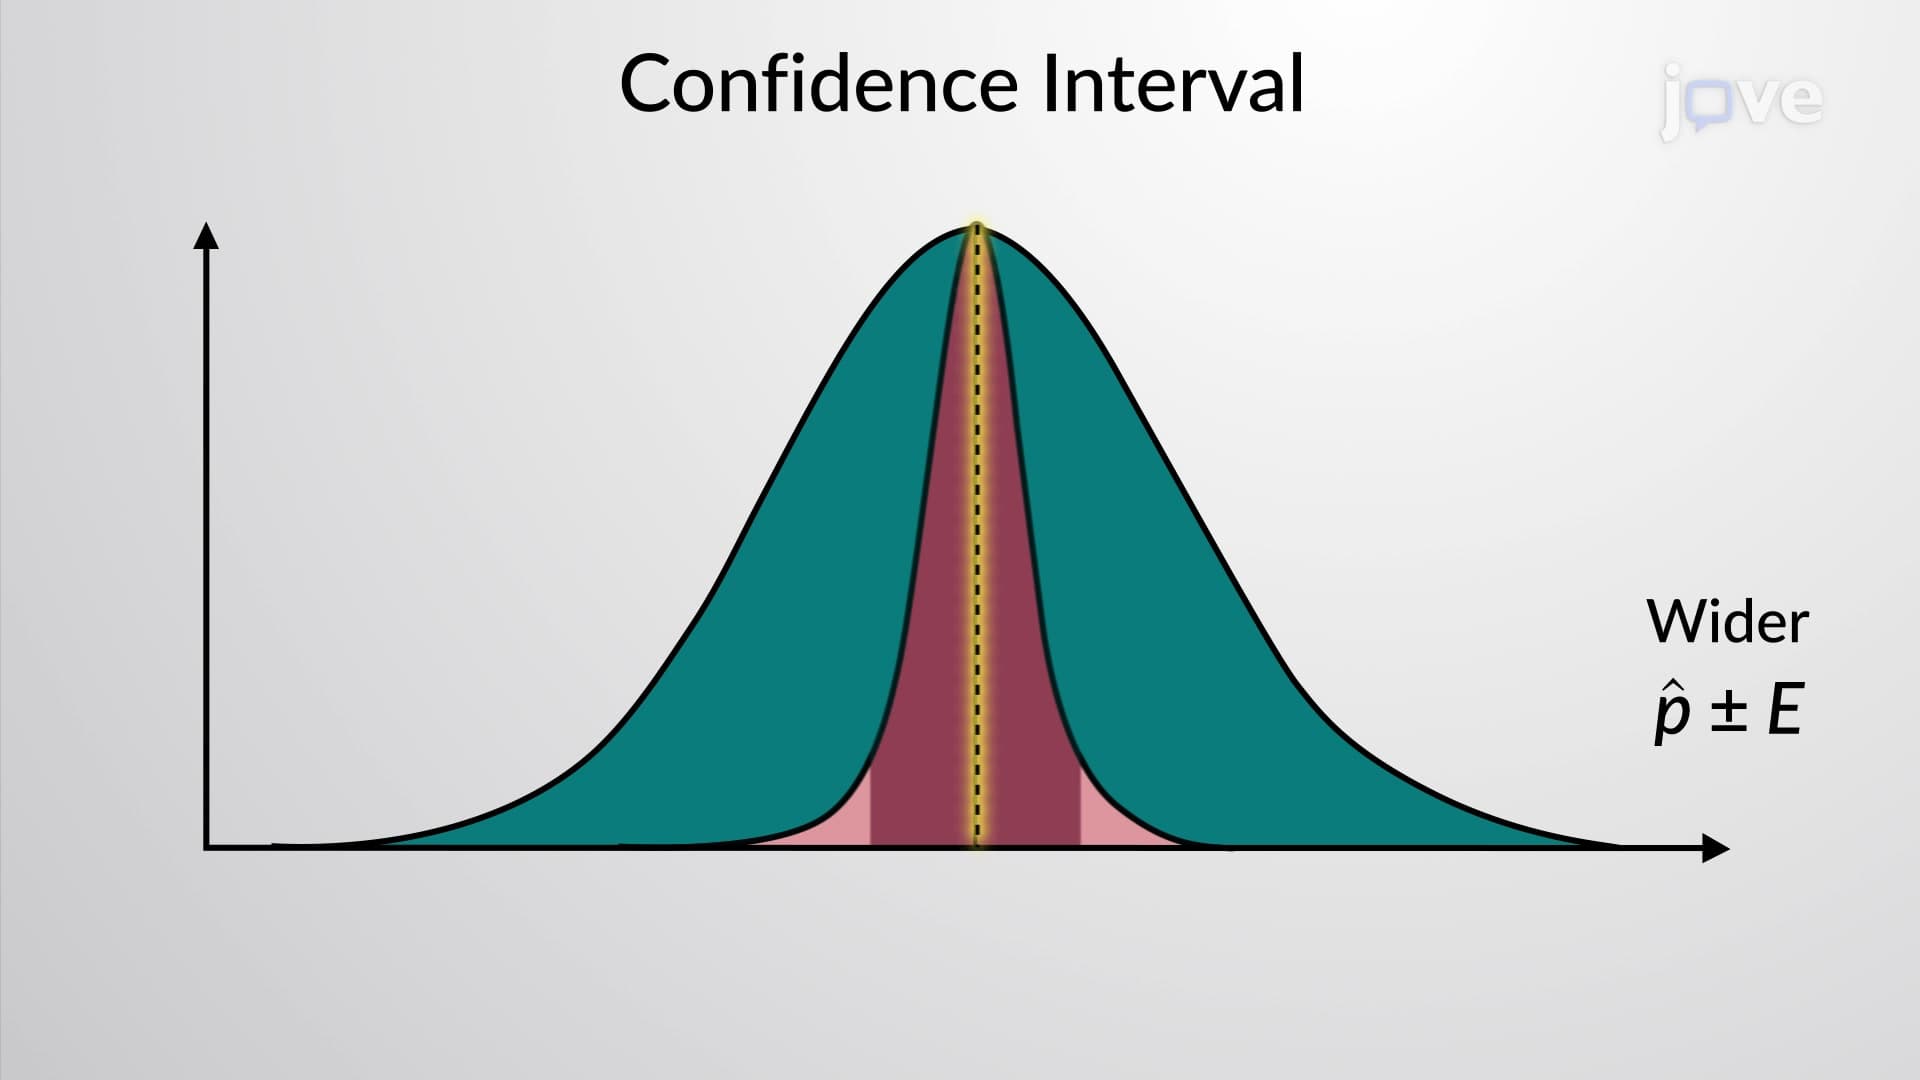
Confidence Intervals
A confidence...
 01:25
Confidence Interval for Estimating Population Mean
A confidence interval for the mean is a range of values that provides an estimate of the population mean. As the...
 01:24
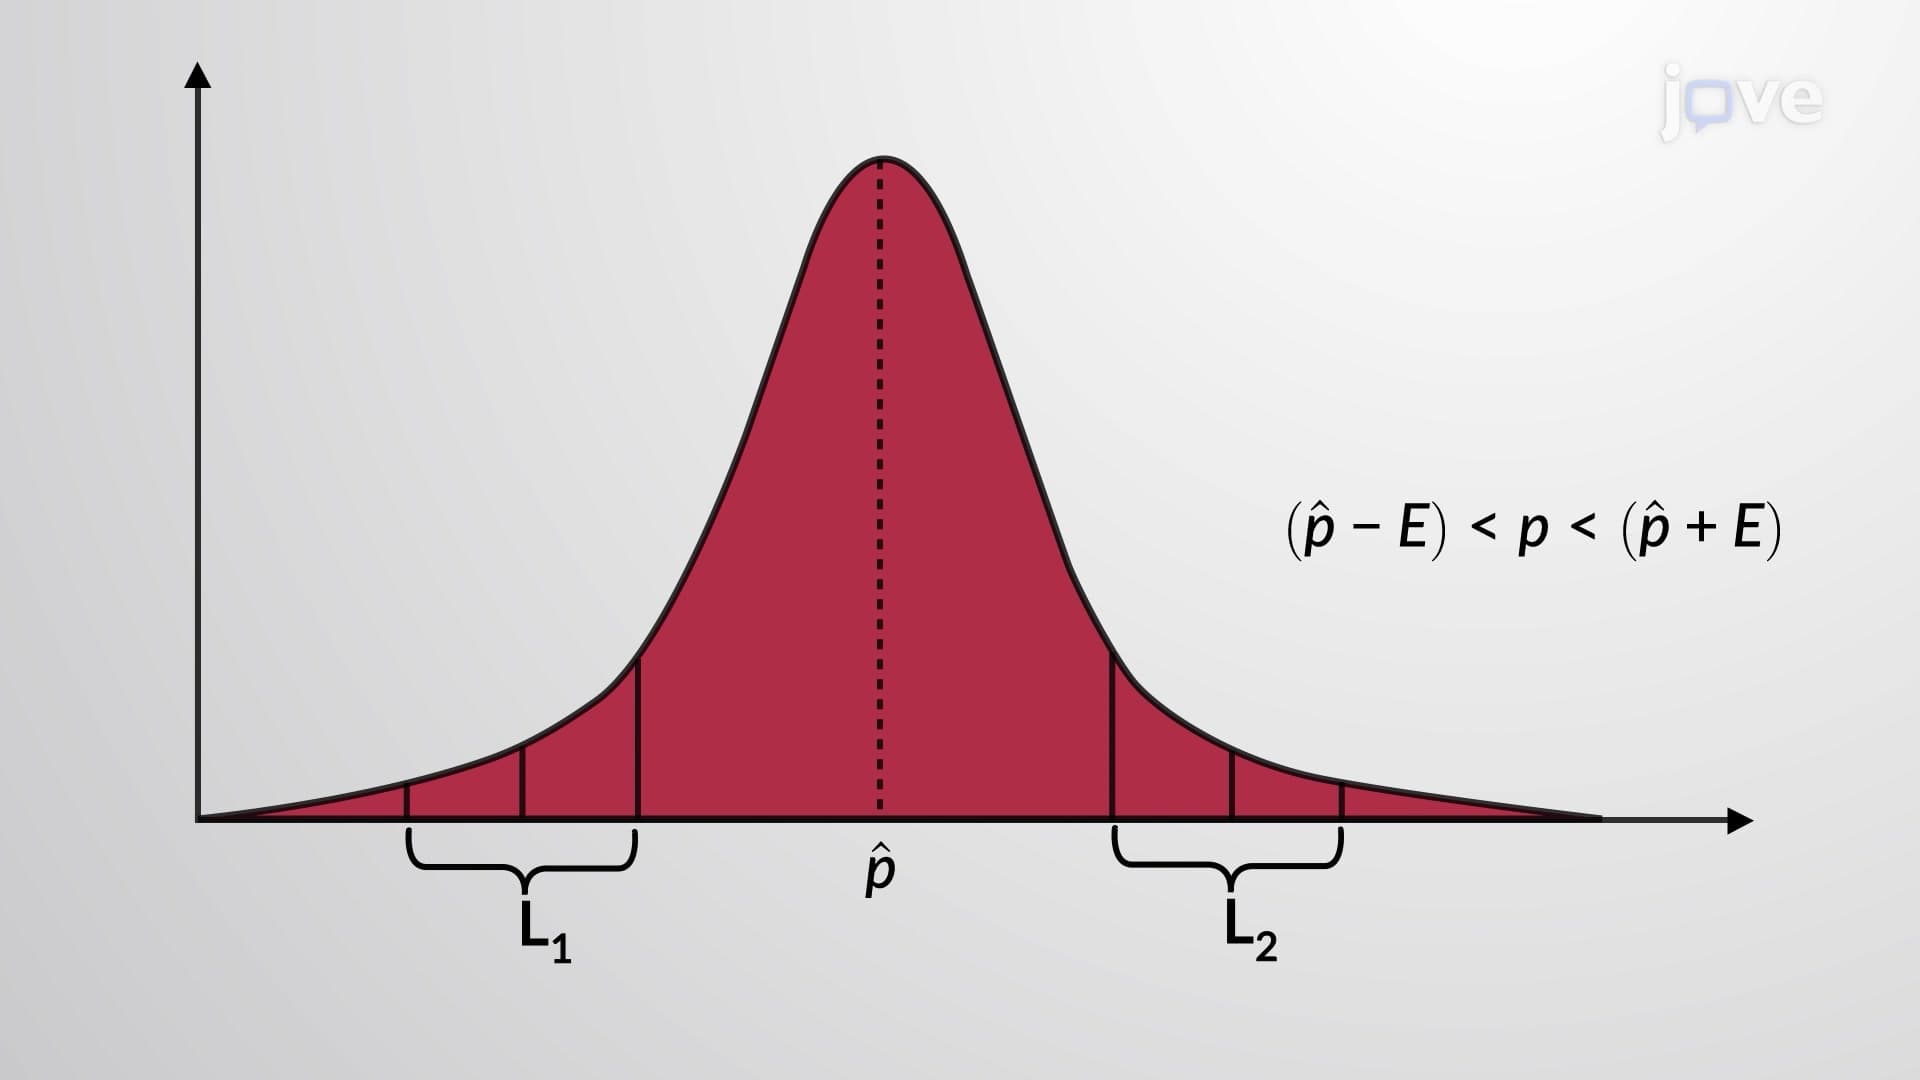
Confidence Coefficient
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:21
Friedman Two-way Analysis of Variance by Ranks