GeneSrF and varSelRF: a web-based tool and R package for gene selection and classification using random forest
Related Experiment Video
Updated: Jul 12, 2026

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
1Statistical Computing Team, Structural Biology and Biocomputing Programme, Spanish National Cancer Center (CNIO), Melchor Fernández Almagro 3, Madrid, 28029, Spain. rdiaz02@gmail.com

Background:
Microarray data are often used for patient classification and gene selection. An appropriate tool for end users and biomedical researchers should combine user friendliness with statistical rigor, including carefully avoiding selection biases and allowing analysis of multiple solutions, together with access to additional functional information of selected genes. Methodologically, such a tool would be of greater use if it incorporates state-of-the-art computational approaches and makes source code available.
Results:
We have developed GeneSrF, a web-based tool, and varSelRF, an R package, that implement, in the context of patient classification, a validated method for selecting very small sets of genes while preserving classification accuracy. Computation is parallelized, allowing to take advantage of multicore CPUs and clusters of workstations. Output includes bootstrapped estimates of prediction error rate, and assessments of the stability of the solutions. Clickable tables link to additional information for each gene (GO terms, PubMed citations, KEGG pathways), and output can be sent to PaLS for examination of PubMed references, GO terms, KEGG and and Reactome pathways characteristic of sets of genes selected for class prediction. The full source code is available, allowing to extend the software. The web-based application is available from http://genesrf2.bioinfo.cnio.es. All source code is available from Bioinformatics.org or The Launchpad. The R package is also available from CRAN.
Conclusion:
varSelRF and GeneSrF implement a validated method for gene selection including bootstrap estimates of classification error rate. They are valuable tools for applied biomedical researchers, specially for exploratory work with microarray data. Because of the underlying technology used (combination of parallelization with web-based application) they are also of methodological interest to bioinformaticians and biostatisticians.
More Related Videos
 07:13
Comparison of Predictive Performance of Three Lymph Node Staging Systems in Colorectal Signet Ring Cell Carcinoma Based on Machine Learning Model
Published on: April 18, 2025
 06:46
Competing-Risk Nomogram for Predicting Cancer-Specific Survival in Multiple Primary Colorectal Cancer Patients after Surgery
Published on: September 27, 2024
Related Concept Videos
 01:11
Introduction to R
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:16
Response Surface Methodology
The process of RSM involves several key steps:
 01:09
Random Variables
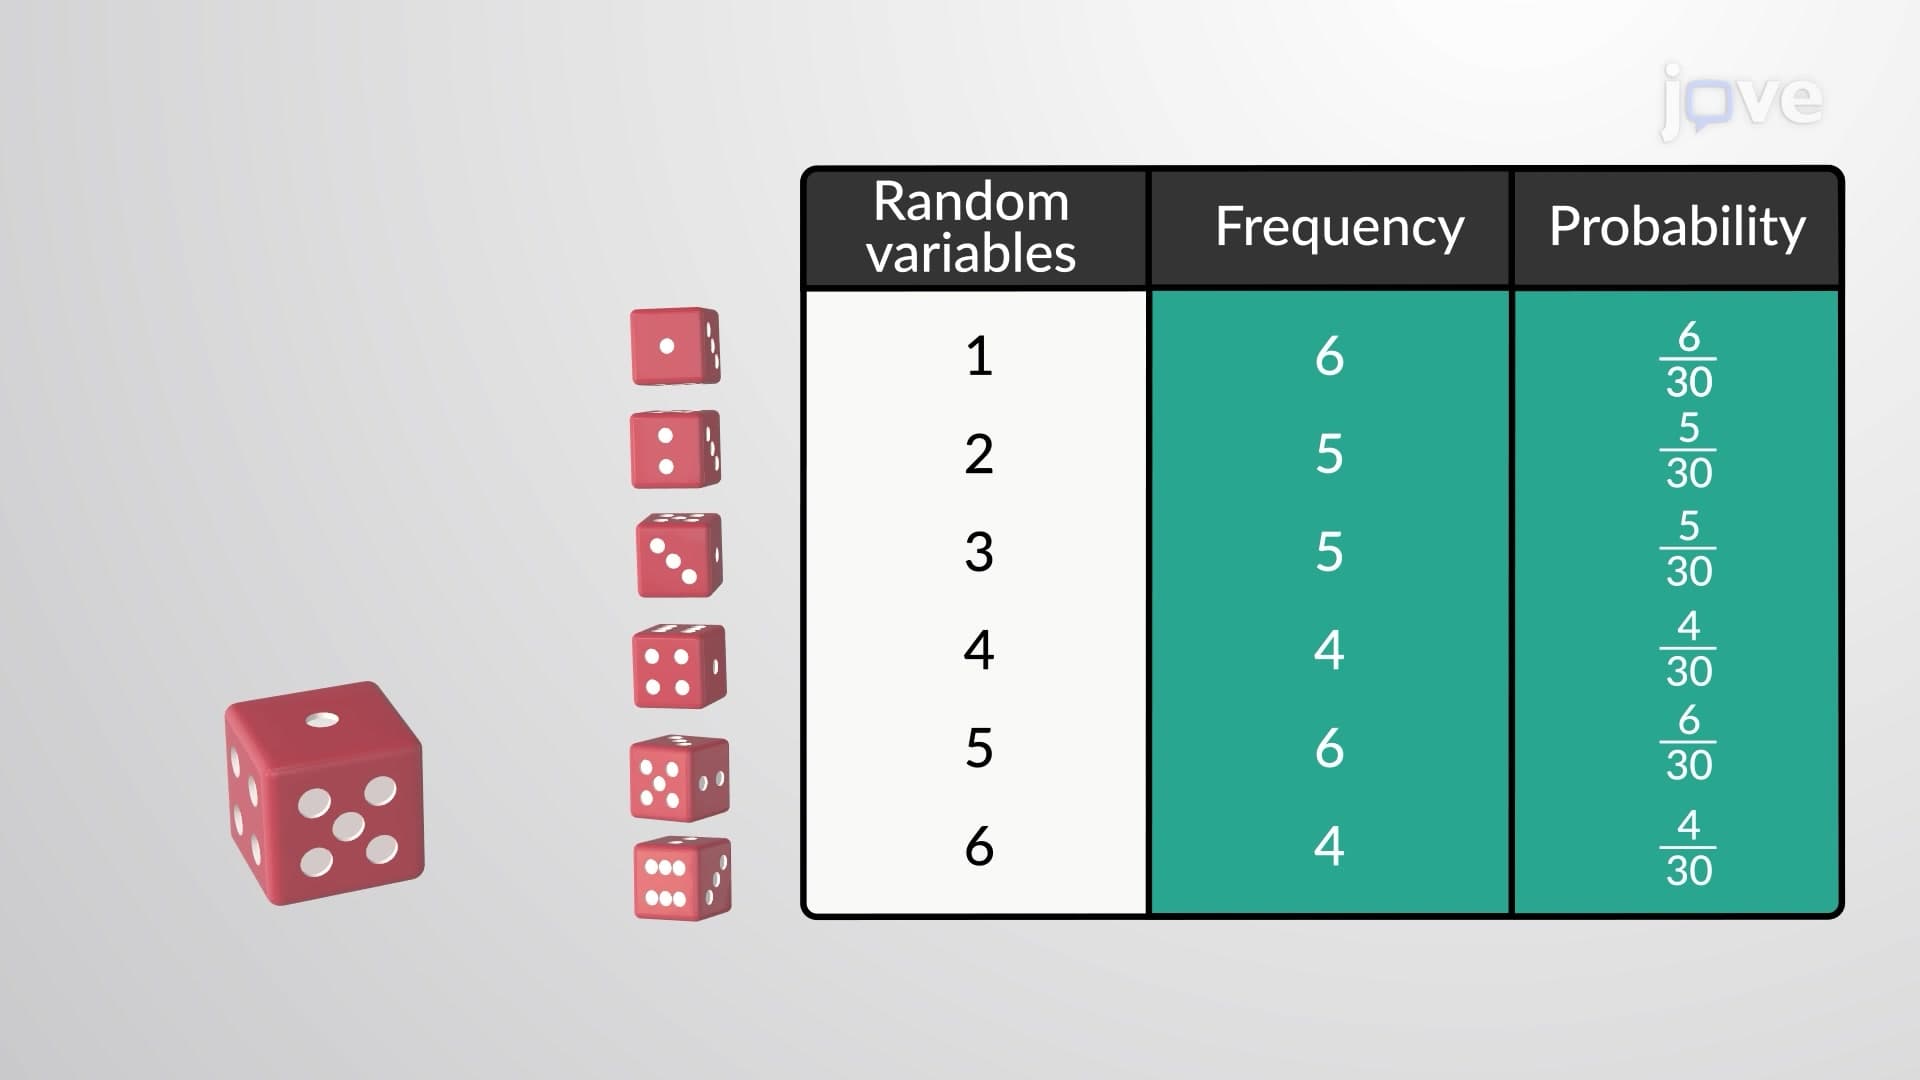
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...