Predicting transmembrane helix pair configurations with knowledge-based distance-dependent pair potentials
Related Experiment Video
Updated: Jul 11, 2026

Computational Prediction of Amino Acid Preferences of Potentially Multispecific Peptide-Binding Domains Involved in Protein-Protein Interactions
Published on: January 26, 2024
Christina Wendel1, Holger Gohlke
1Department of Biological Sciences, Molecular Bioinformatics Group, J. W. Goethe-University, Frankfurt, Germany.

Abstract:
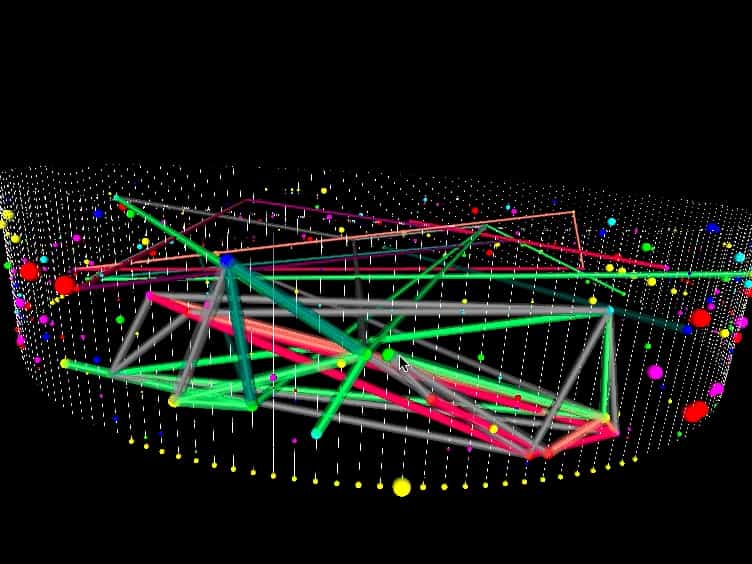
As a first step toward a novel de novo structure prediction approach for alpha-helical membrane proteins, we developed coarse-grained knowledge-based potentials to score the mutual configuration of transmembrane (TM) helices. Using a comprehensive database of 71 known membrane protein structures, pairwise potentials depending solely on amino acid types and distances between C(alpha)-atoms were derived. To evaluate the potentials, they were used as an objective function for the rigid docking of 442 TM helix pairs. This is by far the largest test data set reported to date for that purpose. After clustering 500 docking runs for each pair and considering the largest cluster, we found solutions with a root mean squared (RMS) deviation <2 A for about 30% of all helix pairs. Encouragingly, if only clusters that contain at least 20% of all decoys are considered, a success rate >71% (with a RMS deviation <2 A) is obtained. The cluster size thus serves as a measure of significance to identify good docking solutions. In a leave-one-protein-family-out cross-validation study, more than 2/3 of the helix pairs were still predicted with an RMS deviation <2.5 A (if only clusters that contain at least 20% of all decoys are considered). This demonstrates the predictive power of the potentials in general, although it is advisable to further extend the knowledge base to derive more robust potentials in the future. When compared to the scoring function of Fleishman and Ben-Tal, a comparable performance is found by our cross-validated potentials. Finally, well-predicted "anchor helix pairs" can be reliably identified for most of the proteins of the test data set. This is important for an extension of the approach towards TM helix bundles because these anchor pairs will act as "nucleation sites" to which more helices will be added subsequently, which alleviates the sampling problem.

Related Concept Videos
 02:27
Predicting Molecular Geometry
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 01:28
Ionic Association
 01:09
Multi-pass Transmembrane Proteins and β-barrels
α-Helix containing multi-pass transmembrane proteins
Multi-pass transmembrane proteins such as G-protein-linked receptors (GPCRs) and...
 01:13
Force and Potential Energy in One Dimension
 02:04
Protein-protein Interfaces