Related Experiment Video
Updated: Jul 7, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Evolved feature weighting for random subspace classifier

Abstract:
The problem addressed in this letter concerns the multiclassifier generation by a random subspace method (RSM). In the RSM, the classifiers are constructed in random subspaces of the data feature space. In this letter, we propose an evolved feature weighting approach: in each subspace, the features are multiplied by a weight factor for minimizing the error rate in the training set. An efficient method based on particle swarm optimization (PSO) is here proposed for finding a set of weights for each feature in each subspace. The performance improvement with respect to the state-of-the-art approaches is validated through experiments with several benchmark data sets.
Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:09
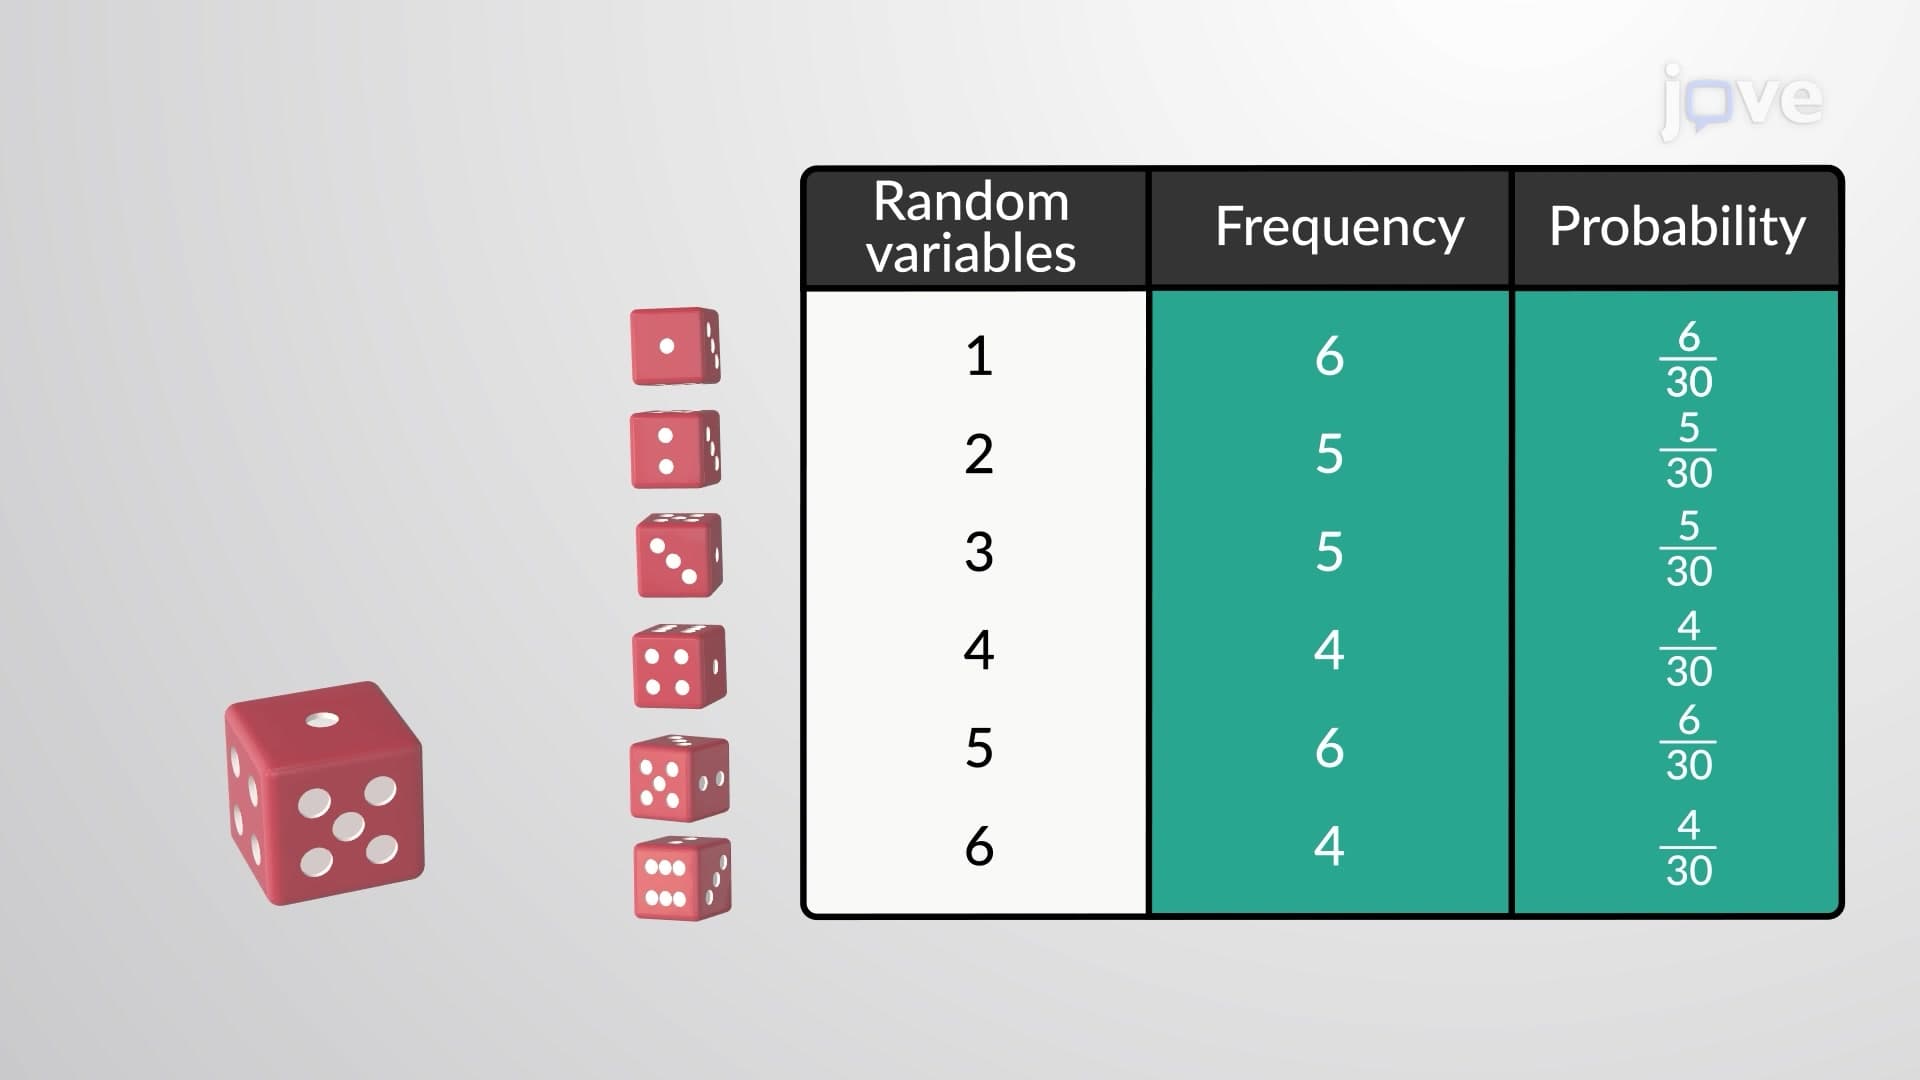
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:52
Regression Toward the Mean