Related Experiment Video
Updated: Aug 3, 2026
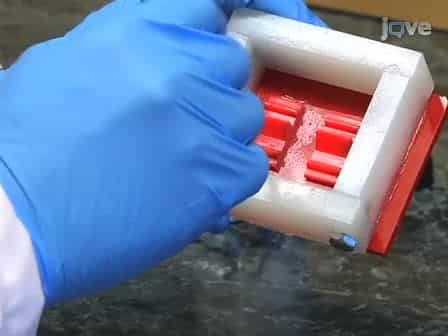

Synthetic, Multi-Layer, Self-Oscillating Vocal Fold Model Fabrication
Published on: December 2, 2011
Development and testing of artificial low-frequency speech codes
C M Reed1, M H Power, N I Durlach
1Research Laboratory of Electronics, Massachusetts Institute of Technology, Cambridge 02139.

Abstract:
In a new approach to the frequency-lowering of speech, artificial codes were developed for 24 consonants (C) and 15 vowels (V) for two values of lowpass cutoff frequency F (300 and 500 Hz). Each individual phoneme was coded by a unique, nonvarying acoustic signal confined to frequencies less than or equal to F. Stimuli were created through variations in spectral content, amplitude, and duration of tonal complexes or bandpass noise. For example, plosive and fricative sounds were constructed by specifying the duration and relative amplitude of bandpass noise with various center frequencies and bandwidths, while vowels were generated through variations in the spectral shape and duration of a ten-tone harmonic complex. The ability of normal-hearing listeners to identify coded Cs and Vs in fixed-context syllables was compared to their performance on single-token sets of natural speech utterances lowpass filtered to equivalent values of F. For a set of 24 consonants in C-/a/ context, asymptotic performance on coded sounds averaged 90 percent correct for F = 500 Hz and 65 percent for F = 300 Hz, compared to 75 percent and 40 percent for lowpass filtered speech. For a set of 15 vowels in /b/-V-/t/ context, asymptotic performance on coded sounds averaged 85 percent correct for F = 500 Hz and 65 percent for F = 300 Hz, compared to 85 percent and 50 percent for lowpass filtered speech. Identification of coded signals for F = 500 Hz was also examined in CV syllables where C was selected at random from the set of 24 Cs and V was selected at random from the set of 15 Vs. Asymptotic performance of roughly 67 percent correct and 71 percent correct was obtained for C and V identification, respectively. These scores are somewhat lower than those obtained in the fixed-context experiments. Finally, results were obtained concerning the effect of token variability on the identification of lowpass filtered speech. These results indicate a systematic decrease in percent-correct score as the number of tokens representing each phoneme in the identification tests increased from one to nine.
Related Concept Videos
 01:23
Design Example
 01:18
Aliasing
If the sampling frequency is below the Nyquist rate, these replicas overlap, preventing the original signal...
 01:27
Air-entraining Agents
 01:29
Non-Verbal Cues