Related Experiment Video
Updated: Jun 29, 2026

Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
Forward selection of explanatory variables
F Guillaume Blanchet1, Pierre Legendre, Daniel Borcard
1Départment de Sciences Biologiques, Université de Montréal, C.P. 6128, Succursale Centre-ville, Montréal, Québec H3C 3J7, Canada. gblanche@ualberta.ca

Abstract:
This paper proposes a new way of using forward selection of explanatory variables in regression or canonical redundancy analysis. The classical forward selection method presents two problems: a highly inflated Type I error and an overestimation of the amount of explained variance. Correcting these problems will greatly improve the performance of this very useful method in ecological modeling. To prevent the first problem, we propose a two-step procedure. First, a global test using all explanatory variables is carried out. If, and only if, the global test is significant, one can proceed with forward selection. To prevent overestimation of the explained variance, the forward selection has to be carried out with two stopping criteria: (1) the usual alpha significance level and (2) the adjusted coefficient of multiple determination (Ra(2)) calculated using all explanatory variables. When forward selection identifies a variable that brings one or the other criterion over the fixed threshold, that variable is rejected, and the procedure is stopped. This improved method is validated by simulations involving univariate and multivariate response data. An ecological example is presented using data from the Bryce Canyon National Park, Utah, U.S.A.
Related Concept Videos
 01:19
Survival Tree
Building a Survival Tree
Constructing a survival tree begins...
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
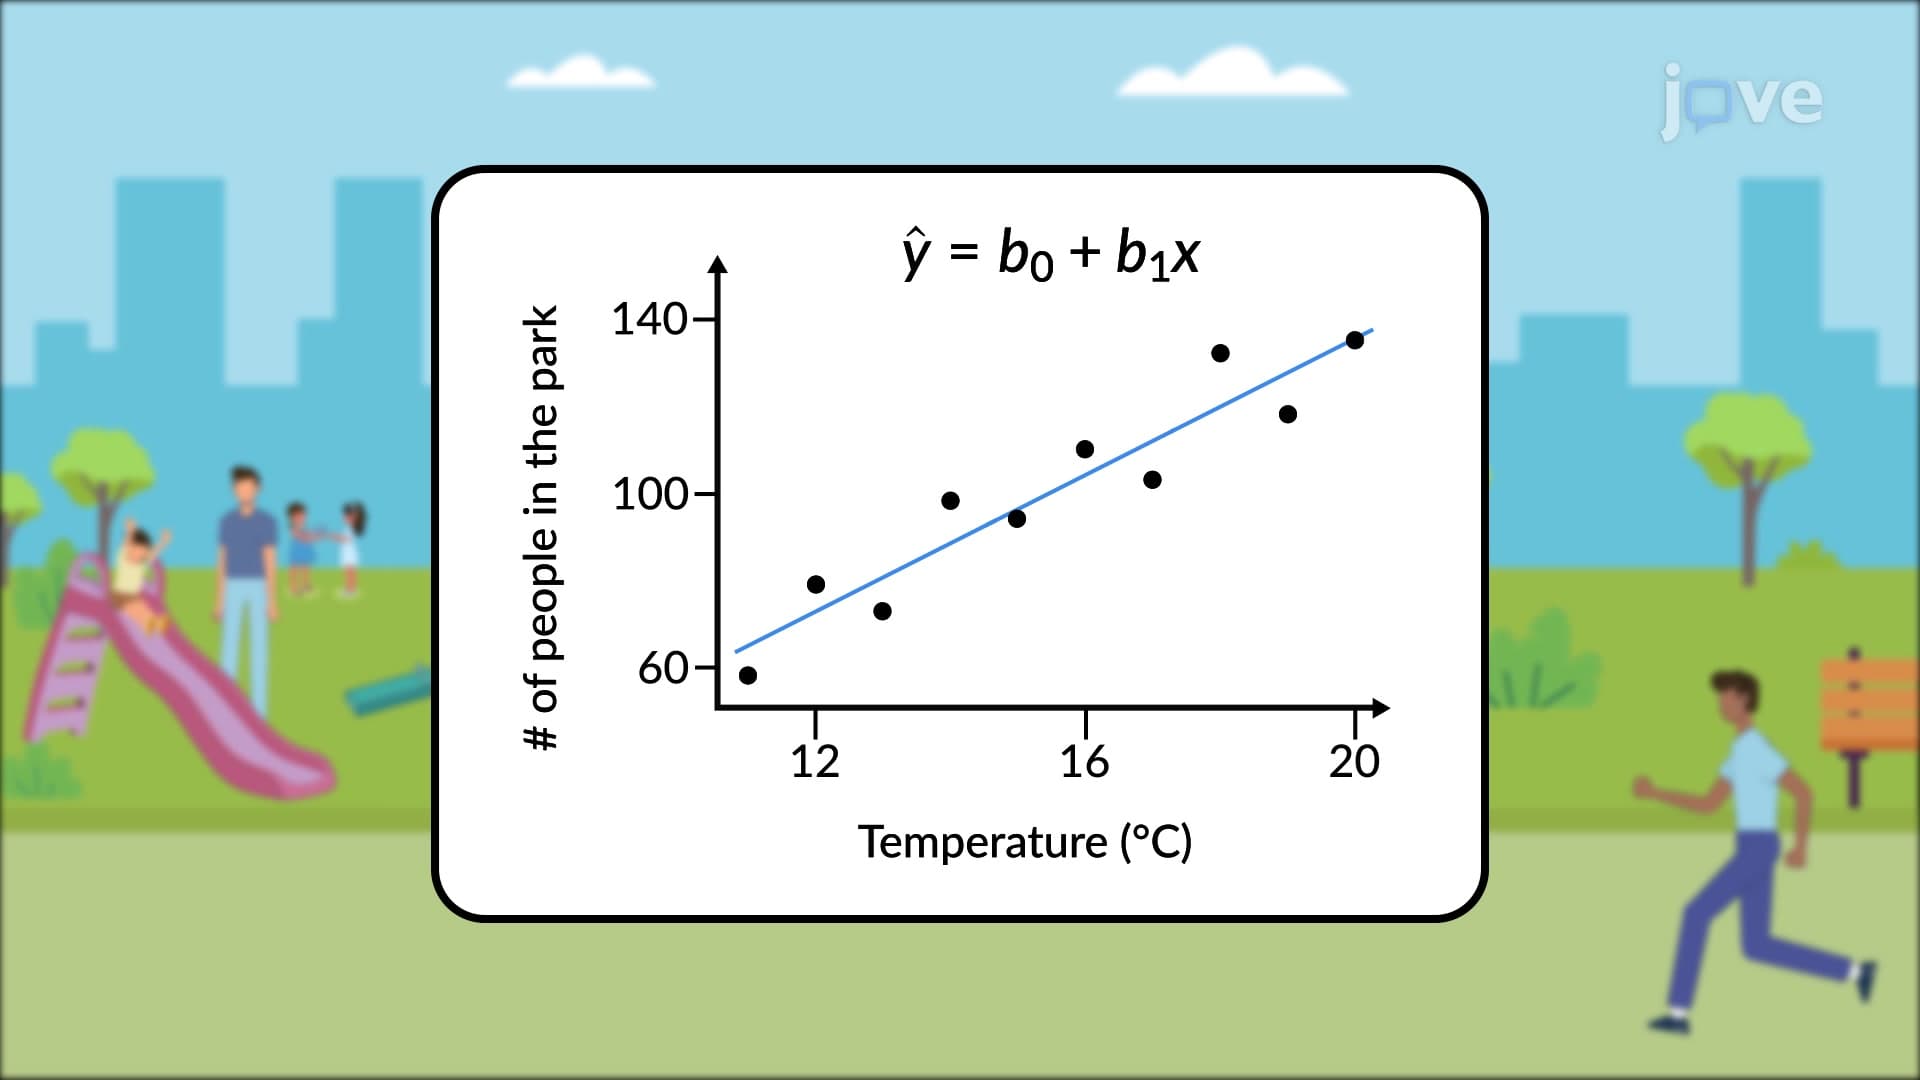
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:46
Types of Selection
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:21
Friedman Two-way Analysis of Variance by Ranks