Arbitrary norm support vector machines
Related Experiment Videos
Kaizhu Huang1, Danian Zheng, Irwin King
1Department of Computer Science and Engineering, Chinese University of Hong Kong, Shatin, Hong Kong. kzhuang@cse.cuhk.edu.hk

Abstract:
Support vector machines (SVM) are state-of-the-art classifiers. Typically L2-norm or L1-norm is adopted as a regularization term in SVMs, while other norm-based SVMs, for example, the L0-norm SVM or even the L(infinity)-norm SVM, are rarely seen in the literature. The major reason is that L0-norm describes a discontinuous and nonconvex term, leading to a combinatorially NP-hard optimization problem. In this letter, motivated by Bayesian learning, we propose a novel framework that can implement arbitrary norm-based SVMs in polynomial time. One significant feature of this framework is that only a sequence of sequential minimal optimization problems needs to be solved, thus making it practical in many real applications. The proposed framework is important in the sense that Bayesian priors can be efficiently plugged into most learning methods without knowing the explicit form. Hence, this builds a connection between Bayesian learning and the kernel machines. We derive the theoretical framework, demonstrate how our approach works on the L0-norm SVM as a typical example, and perform a series of experiments to validate its advantages. Experimental results on nine benchmark data sets are very encouraging. The implemented L0-norm is competitive with or even better than the standard L2-norm SVM in terms of accuracy but with a reduced number of support vectors, -9.46% of the number on average. When compared with another sparse model, the relevance vector machine, our proposed algorithm also demonstrates better sparse properties with a training speed over seven times faster.
Related Concept Videos
 01:27
The Normal and Binormal Vectors
 01:09
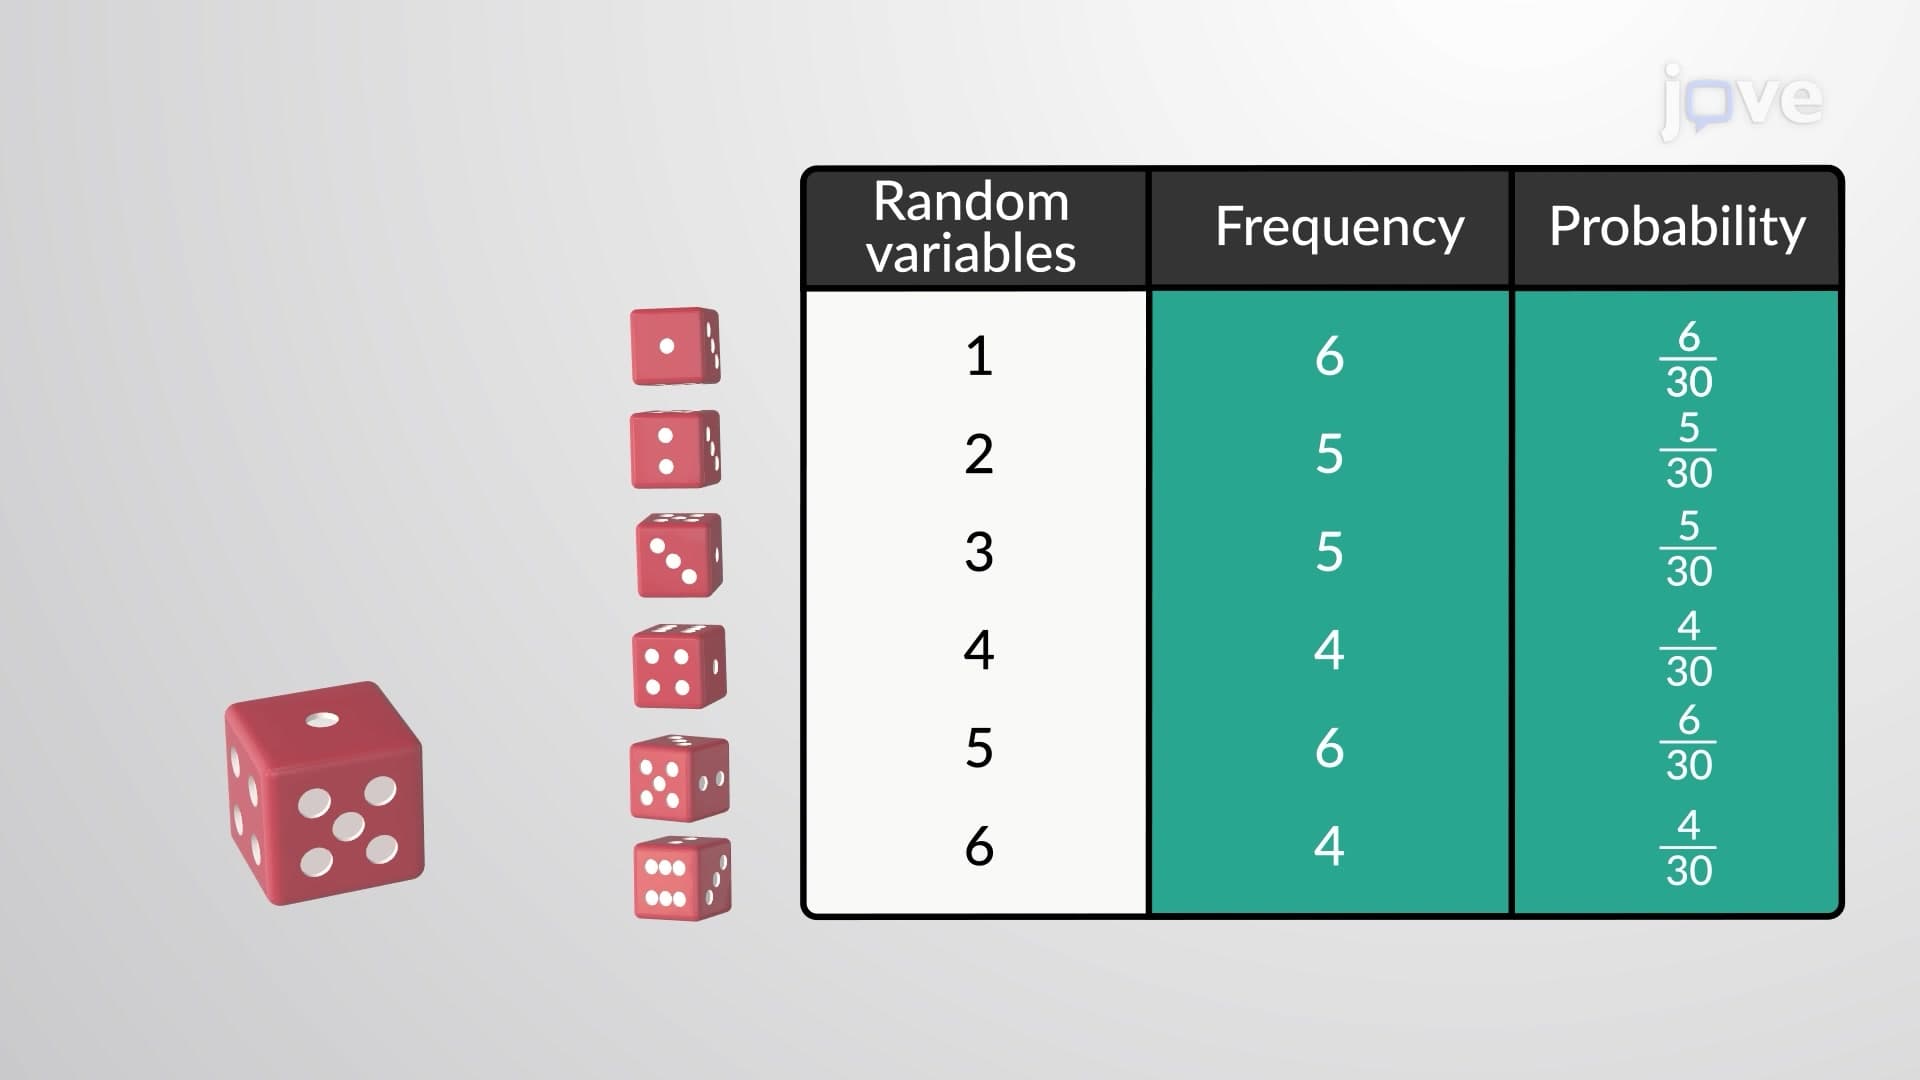
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:13
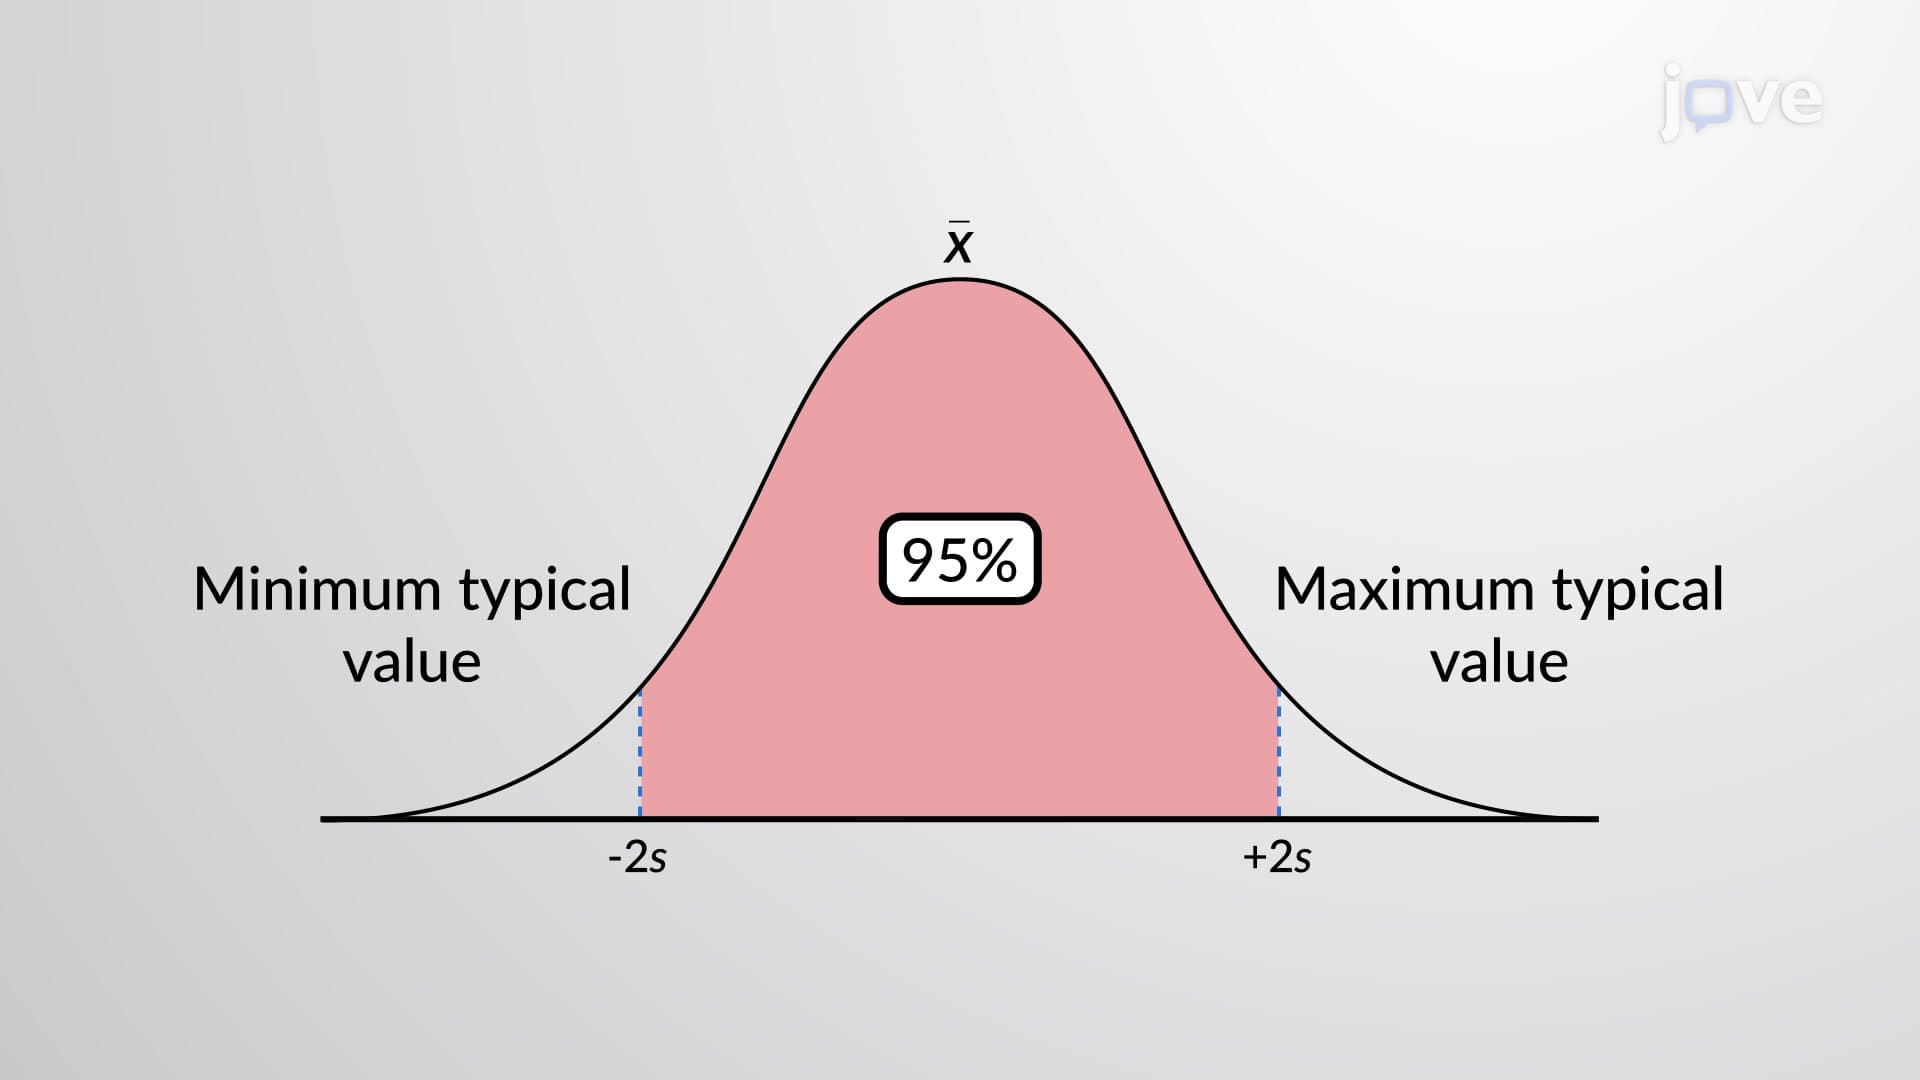
Range Rule of Thumb to Interpret Standard Deviation
For instance, the range rule of thumb can be used to find the tallest and the shortest student in a class, given the mean student height and standard deviation. If the mean student height is 1.6 m and the standard deviation, s is 0.05 m, the height of...
 01:52
Regression Toward the Mean
 01:13
Mean Absolute Deviation
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
 01:09
Empirical Method to Interpret Standard Deviation
This rule is used widely in statistics to calculate the proportion of data values...