Related Experiment Video
Updated: Jun 22, 2026

Isokinetic Robotic Device to Improve Test-Retest and Inter-Rater Reliability for Stretch Reflex Measurements in Stroke Patients with Spasticity
Published on: June 12, 2019
Local independence and residual covariance: a study of olympic figure skating ratings
114525 SW Millikan Way, #27615, Beaverton, OR 97005-2343, USA. john@winsteps.com

Abstract:
Rasch fit analysis has focused on tests of global fit and tests of the fit of individual parameter estimates. Critics have noted that slight, but pervasive, patterns of misfit to a Rasch model within the data may escape detection using these approaches. These patterns contradict the Rasch axiom of local independence, and so degrade measurement and may bias measures. Misfit to a Rasch model is captured in the observation residuals. Traces of pervasive, but faint, secondary dimensions within the observations may be identified using factor analytic techniques. To illustrate these techniques, the ratings awarded during the Pairs Figure Skating competition at the 2002 Winter Olympic Games are examined. The intention is to detect analytically the patterns of rater bias admitted publicly after the event. It is seen that the one-parameter-at-a-time fit statistics and differential item functioning approaches fail to detect the crucial misfit patterns. Factor analytic methods do. In fact, the competition was held in two stages. Factor analytic techniques already detect the rater bias after the first stage. This suggests that remedial rater retraining or other rater-related actions could be taken before the final ratings are collected.


Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:52
Regression Toward the Mean
 01:19
Variation
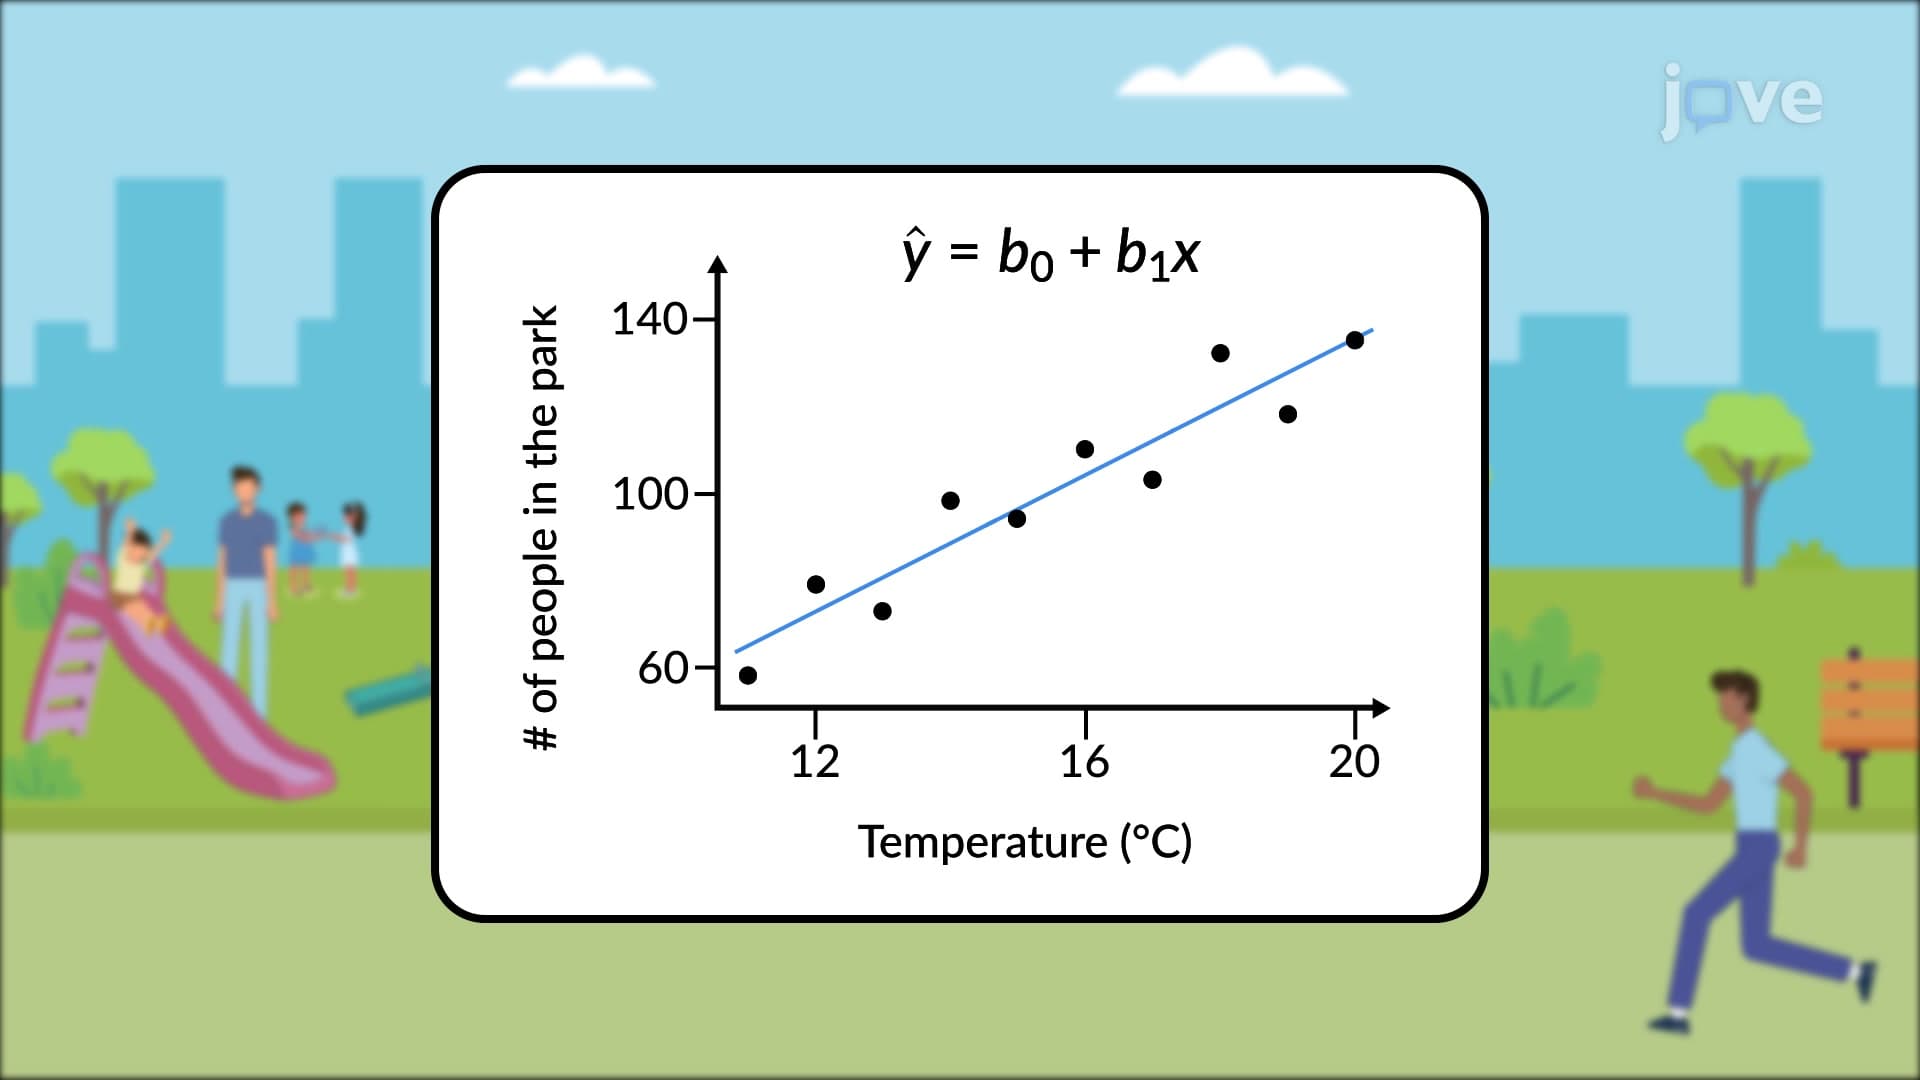
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the strength of the linear...
 01:21
Introduction to Test of Independence
The test statistic for a test of independence is similar to that of a goodness-of-fit test: