PyMix--the python mixture package--a tool for clustering of heterogeneous biological data
Related Experiment Video
Updated: Jun 17, 2026
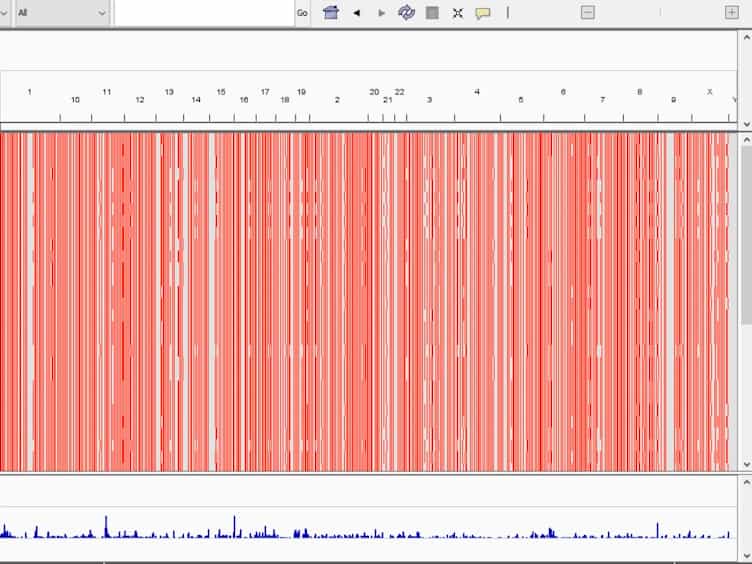
A Fast and Quantitative Method for Post-translational Modification and Variant Enabled Mapping of Peptides to Genomes
Published on: May 22, 2018
Benjamin Georgi1, Ivan Gesteira Costa, Alexander Schliep
1Max Planck Institute for Molecular Genetics, Dept, of Computational Molecular Biology, Ihnestrasse 73, 14195 Berlin. bgeorgi@mail.med.upenn.edu

Background:
Cluster analysis is an important technique for the exploratory analysis of biological data. Such data is often high-dimensional, inherently noisy and contains outliers. This makes clustering challenging. Mixtures are versatile and powerful statistical models which perform robustly for clustering in the presence of noise and have been successfully applied in a wide range of applications.
Results:
PyMix - the Python mixture package implements algorithms and data structures for clustering with basic and advanced mixture models. The advanced models include context-specific independence mixtures, mixtures of dependence trees and semi-supervised learning. PyMix is licenced under the GNU General Public licence (GPL). PyMix has been successfully used for the analysis of biological sequence, complex disease and gene expression data.
Conclusions:
PyMix is a useful tool for cluster analysis of biological data. Due to the general nature of the framework, PyMix can be applied to a wide range of applications and data sets.
