Motif Enrichment Analysis: a unified framework and an evaluation on ChIP data
Related Experiment Video
Updated: Jun 14, 2026
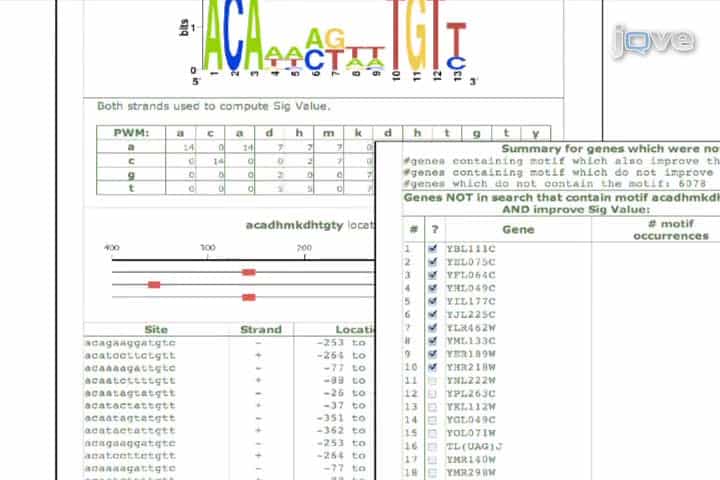
Using SCOPE to Identify Potential Regulatory Motifs in Coregulated Genes
Published on: May 31, 2011
Robert C McLeay1, Timothy L Bailey
1Institute for Molecular Bioscience, The University of Queensland, Brisbane, Queensland 4072, Australia.

Background:
A major goal of molecular biology is determining the mechanisms that control the transcription of genes. Motif Enrichment Analysis (MEA) seeks to determine which DNA-binding transcription factors control the transcription of a set of genes by detecting enrichment of known binding motifs in the genes' regulatory regions. Typically, the biologist specifies a set of genes believed to be co-regulated and a library of known DNA-binding models for transcription factors, and MEA determines which (if any) of the factors may be direct regulators of the genes. Since the number of factors with known DNA-binding models is rapidly increasing as a result of high-throughput technologies, MEA is becoming increasingly useful. In this paper, we explore ways to make MEA applicable in more settings, and evaluate the efficacy of a number of MEA approaches.
Results:
We first define a mathematical framework for Motif Enrichment Analysis that relaxes the requirement that the biologist input a selected set of genes. Instead, the input consists of all regulatory regions, each labeled with the level of a biological signal. We then define and implement a number of motif enrichment analysis methods. Some of these methods require a user-specified signal threshold, some identify an optimum threshold in a data-driven way and two of our methods are threshold-free. We evaluate these methods, along with two existing methods (Clover and PASTAA), using yeast ChIP-chip data. Our novel threshold-free method based on linear regression performs best in our evaluation, followed by the data-driven PASTAA algorithm. The Clover algorithm performs as well as PASTAA if the user-specified threshold is chosen optimally. Data-driven methods based on three statistical tests-Fisher Exact Test, rank-sum test, and multi-hypergeometric test--perform poorly, even when the threshold is chosen optimally. These methods (and Clover) perform even worse when unrestricted data-driven threshold determination is used.
Conclusions:
Our novel, threshold-free linear regression method works well on ChIP-chip data. Methods using data-driven threshold determination can perform poorly unless the range of thresholds is limited a priori. The limits implemented in PASTAA, however, appear to be well-chosen. Our novel algorithms--AME (Analysis of Motif Enrichment)-are available at http://bioinformatics.org.au/ame/.
More Related Videos
 08:51
Application of Unsupervised Multi-Omic Factor Analysis to Uncover Patterns of Variation and Molecular Processes Linked to Cardiovascular Disease
Published on: September 20, 2024
 09:16
A Spin-Tip Enrichment Strategy for Simultaneous Analysis of N-Glycopeptides and Phosphopeptides from Human Pancreatic Tissues
Published on: May 4, 2022