Related Experiment Video
Updated: Jun 4, 2026
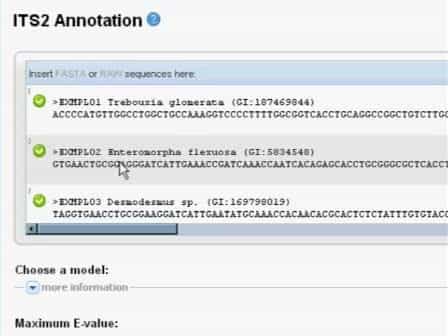
The ITS2 Database
Published on: March 12, 2012

Abstract:
INTRODUCTIONDatabase similarity search programs tend to produce large volumes of output. It can become difficult to screen this volume of material and to assess whether the more remotely related sequences are really related to the query sequence. Thus, it is important to limit the sequence output; there are some relatively simple procedures that may be followed for each program, as described in this article. For searches of protein databases, avoid repetitive alignments with the same sequence by limiting searches to the protein sequence databases that are well curated, such as SwissProt and PIR, or to a specific genome, as opposed to the entire set of translated GenBank sequences (the GenPept database).
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 01:29
Modern Molecular Taxonomy
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while microarray-based...
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features.
 01:57
Sanger Sequencing