Related Experiment Video
Updated: May 25, 2026
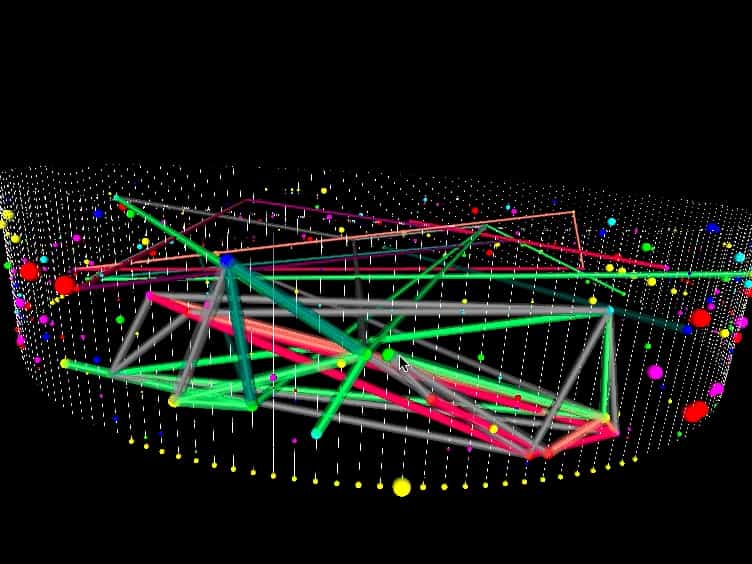
Optimization of Synthetic Proteins: Identification of Interpositional Dependencies Indicating Structurally and/or Functionally Linked Residues
Published on: July 14, 2015
An improved scoring method for protein residue conservation and multiple sequence alignment
1Department of Information Technology, Clayton State University, Morrow, GA 30260, USA. knguyen@clayton.edu

Abstract:
One of the most fundamental operation in biological sequence analysis is multiple sequence alignment (MSA). Optimally aligning multiple sequences is an intractable problem; however, it is a critical tool for biologists to identify the relationships between species and also possibly predict the structure and functionality of biological sequences. The most fundamental step of assembling MSA results is identifying the best location to place the sequence residues. And the accuracy of the sequence assembly depends heavily on the reliability of a scoring function used. With an appropriate scoring function, an MSA program can boost its accuracy of multiple sequence alignment up to 25%. In this study, we present a new, fast, and biologically reliable scoring method, hierarchical expected matching probability (HEP), to use in protein multiple sequence alignment. The new scoring method eliminates the burden of gap cost selection process. And it has consistently proven to be more biologically reliable than all other tested scoring methods through all tests on four different theoretical and experimental benchmarks, Valdar's theoretical conservation benchmark, RT-OSM, BAliBASE3.0, and PREFAB4.0. An implementation of our new scoring method into progressive multiple sequence alignment, resembling the alignment algorithm in PIMA, ClustalW, and T-COFFEE, has shown an accuracy improvement up to 7% on BAliBASE3.0 and up to 5% on PREFAB4.0 benchmarks.
Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
02:26Conservation of Protein Domains
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
01:49Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 01:29
Protein Folding Quality Check in the RER