Network-based H.264/AVC whole frame loss visibility model and frame dropping methods
Related Experiment Videos

Abstract:
We examine the visual effect of whole frame loss by different decoders. Whole frame losses are introduced in H.264/AVC compressed videos which are then decoded by two different decoders with different common concealment effects: frame copy and frame interpolation. The videos are seen by human observers who respond to each glitch they spot. We found that about 39% of whole frame losses of B frames are not observed by any of the subjects, and over 58% of the B frame losses are observed by 20% or fewer of the subjects. Using simple predictive features which can be calculated inside a network node with no access to the original video and no pixel level reconstruction of the frame, we developed models which can predict the visibility of whole B frame losses. The models are then used in a router to predict the visual impact of a frame loss and perform intelligent frame dropping to relieve network congestion. Dropping frames based on their visual scores proves superior to random dropping of B frames.
Related Concept Videos
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...
 01:21
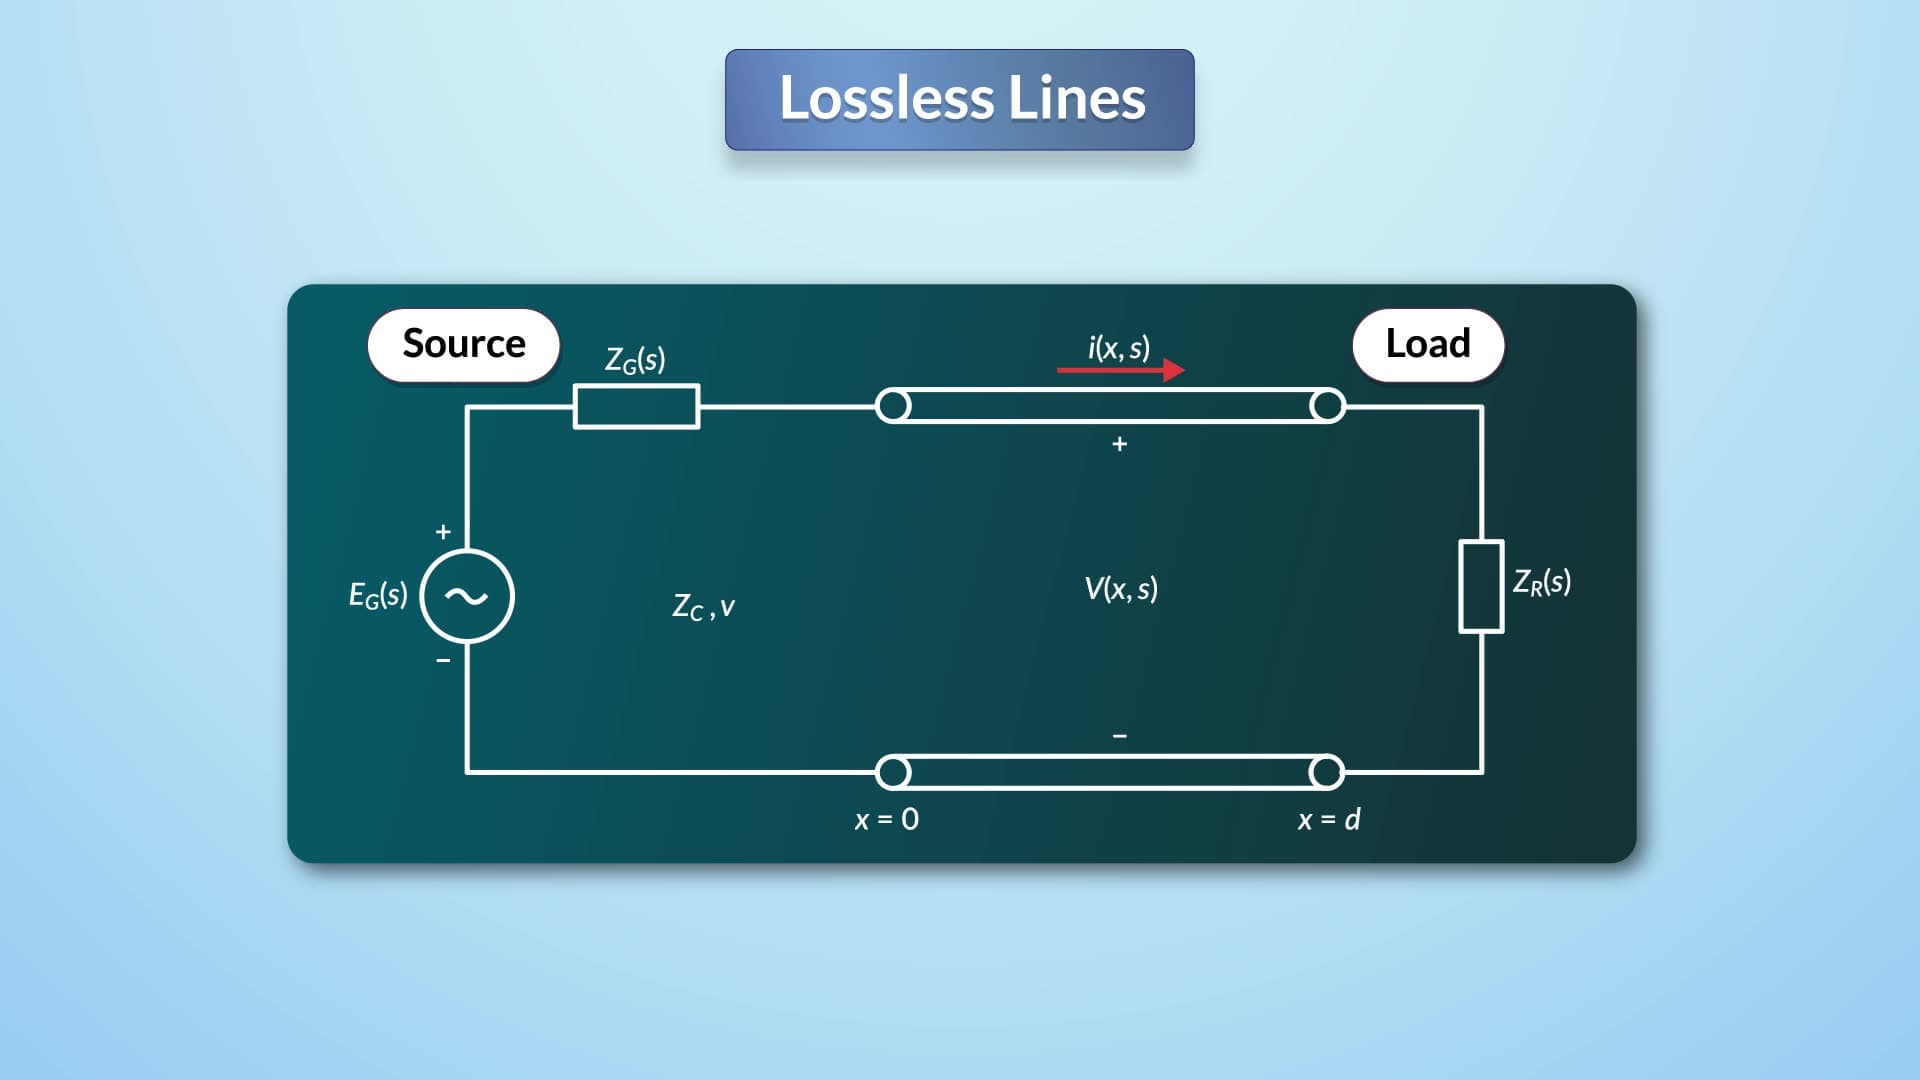
Boundary Conditions: Lossless Lines
At the receiving end, the boundary condition states that the voltage equals the product of the receiving-end impedance and current. This relationship is expressed as a function of the incident and...
 01:10
Line Loss
Line loss impacts power delivery efficiency in a balanced three-phase circuit. The symmetry in such a circuit simplifies the...
 01:27
Uniform Depth Channel Flow
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...