Variation in the input: a case study of manner class frequencies
Related Experiment Video
Updated: May 17, 2026
Using the Race Model Inequality to Quantify Behavioral Multisensory Integration Effects
Published on: May 10, 2019
1UCLA Department of Linguistics.

Abstract:
ABSTRACT What are the sources of variation in the input, and how much do they matter for language acquisition? This study examines frequency variation in manner-of-articulation classes in child and adult input. The null hypothesis is that segmental frequency distributions of language varieties are unigram (modelable by stationary, ergodic processes), and that languages are unitary (modelable as a single language variety). Experiment I showed that English segments are not unigram; they exhibit a 'bursty' distribution in which the local frequency varies more than expected by chance alone. Experiment II showed the English segments are approximately unitary: the natural background variation in segmental frequencies that arises within a single language variety is much larger than numerical differences across varieties. Variation in segmental frequencies seems to be driven by variation in discourse topic; topic-associated words cause bursts/lulls in local segmental frequencies. The article concludes with some methodological recommendations for comparing language samples.
Related Concept Videos
 01:15
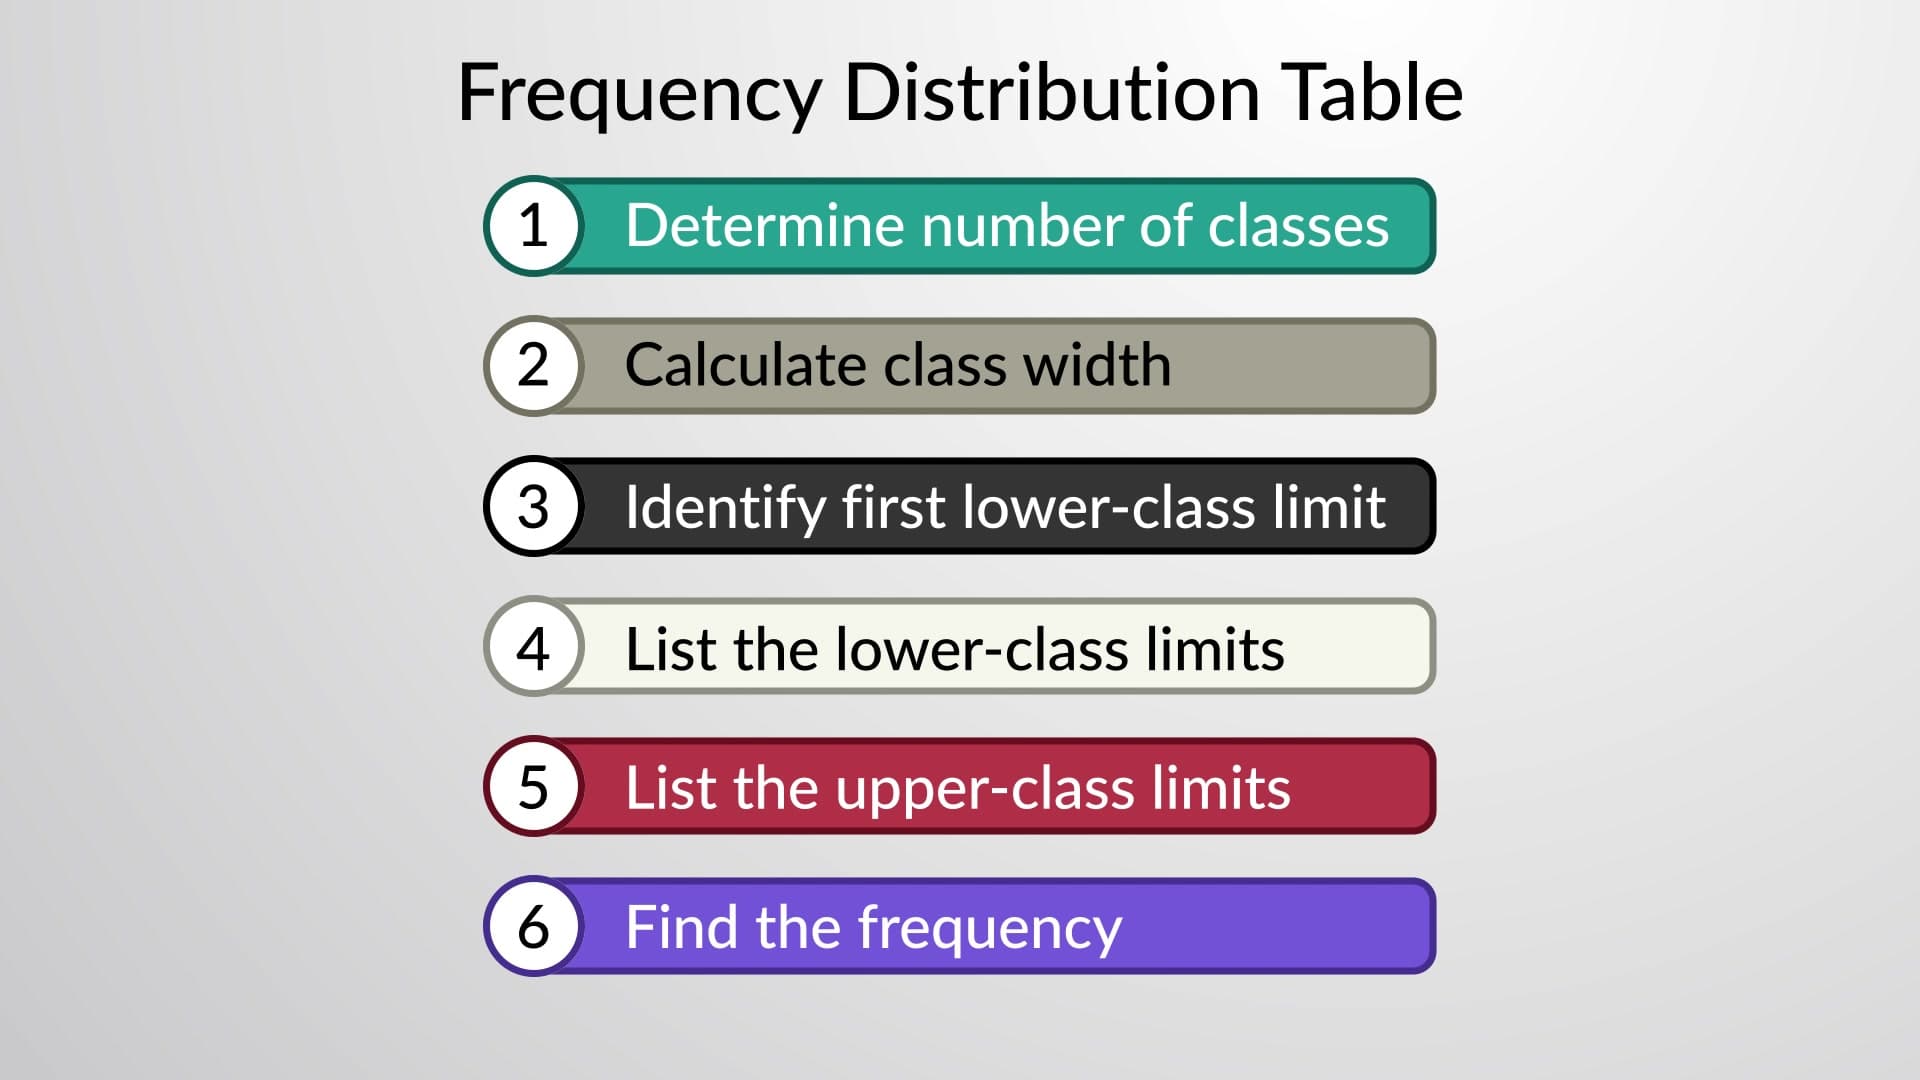
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is best to...
 01:07
What is a Mode?
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 00:51
What is a Frequency Distribution
 01:11
Mean From a Frequency Distribution
When such a data set is encountered, the...
 01:21
Frequency-dependent Selection