Related Experiment Video
Updated: May 15, 2026

Doppler Ultrasound-Based Leg Blood Flow Assessment During Single-Leg Knee-Extensor Exercise in an Uncontrolled Setting
Published on: December 15, 2023
Influences of response rate and distribution on the calculation of interobserver reliability scores
Natalie U Rolider1, Brian A Iwata, Christopher E Bullock
1Kennedy Krieger Institute, USA.

Abstract:
We examined the effects of several variations in response rate on the calculation of total, interval, exact-agreement, and proportional reliability indices. Trained observers recorded computer-generated data that appeared on a computer screen. In Study 1, target responses occurred at low, moderate, and high rates during separate sessions so that reliability results based on the four calculations could be compared across a range of values. Total reliability was uniformly high, interval reliability was spuriously high for high-rate responding, proportional reliability was somewhat lower for high-rate responding, and exact-agreement reliability was the lowest of the measures, especially for high-rate responding. In Study 2, we examined the separate effects of response rate per se, bursting, and end-of-interval responding. Response rate and bursting had little effect on reliability scores; however, the distribution of some responses at the end of intervals decreased interval reliability somewhat, proportional reliability noticeably, and exact-agreement reliability markedly.
Related Concept Videos
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:09
Odds Ratio
 01:25
Choosing Between z and t Distribution
 01:12
Sampling Distribution
 01:19
F Distribution
 01:11
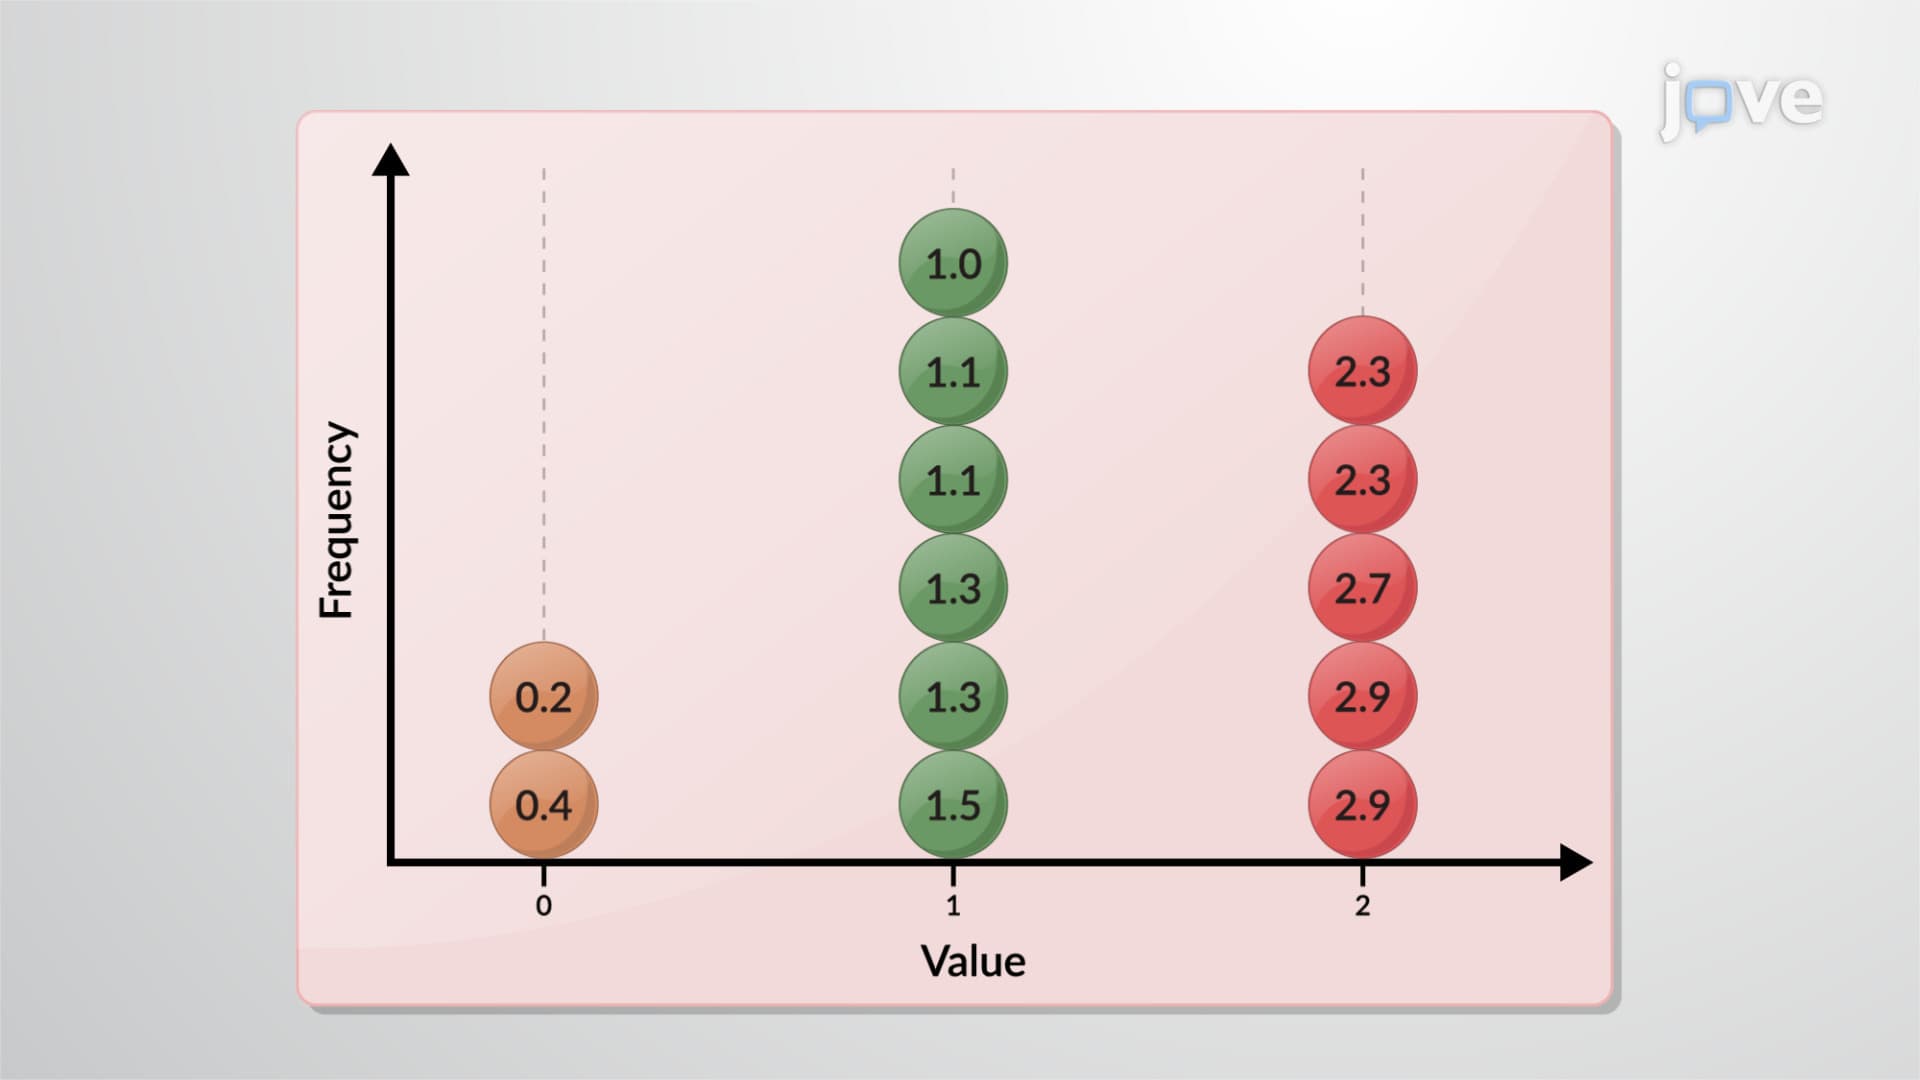
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...