Accelerating read mapping with FastHASH
Related Experiment Video
Updated: May 14, 2026
Active Probe Atomic Force Microscopy with Quattro-Parallel Cantilever Arrays for High-Throughput Large-Scale Sample Inspection
Published on: June 13, 2023
Hongyi Xin1, Donghyuk Lee, Farhad Hormozdiari
1Depts. of Computer Science and Electrical and Computer Engineering, Carnegie Mellon University, Pittsburgh, PA 15213, USA.

Abstract:
With the introduction of next-generation sequencing (NGS) technologies, we are facing an exponential increase in the amount of genomic sequence data. The success of all medical and genetic applications of next-generation sequencing critically depends on the existence of computational techniques that can process and analyze the enormous amount of sequence data quickly and accurately. Unfortunately, the current read mapping algorithms have difficulties in coping with the massive amounts of data generated by NGS.We propose a new algorithm, FastHASH, which drastically improves the performance of the seed-and-extend type hash table based read mapping algorithms, while maintaining the high sensitivity and comprehensiveness of such methods. FastHASH is a generic algorithm compatible with all seed-and-extend class read mapping algorithms. It introduces two main techniques, namely Adjacency Filtering, and Cheap K-mer Selection.We implemented FastHASH and merged it into the codebase of the popular read mapping program, mrFAST. Depending on the edit distance cutoffs, we observed up to 19-fold speedup while still maintaining 100% sensitivity and high comprehensiveness.
Related Concept Videos
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 02:35
RACE - Rapid Amplification of cDNA Ends
Since the...
 02:28
Leaky Scanning
 01:10
Fast Fourier Transform
The computational efficiency of the FFT becomes...
 01:08
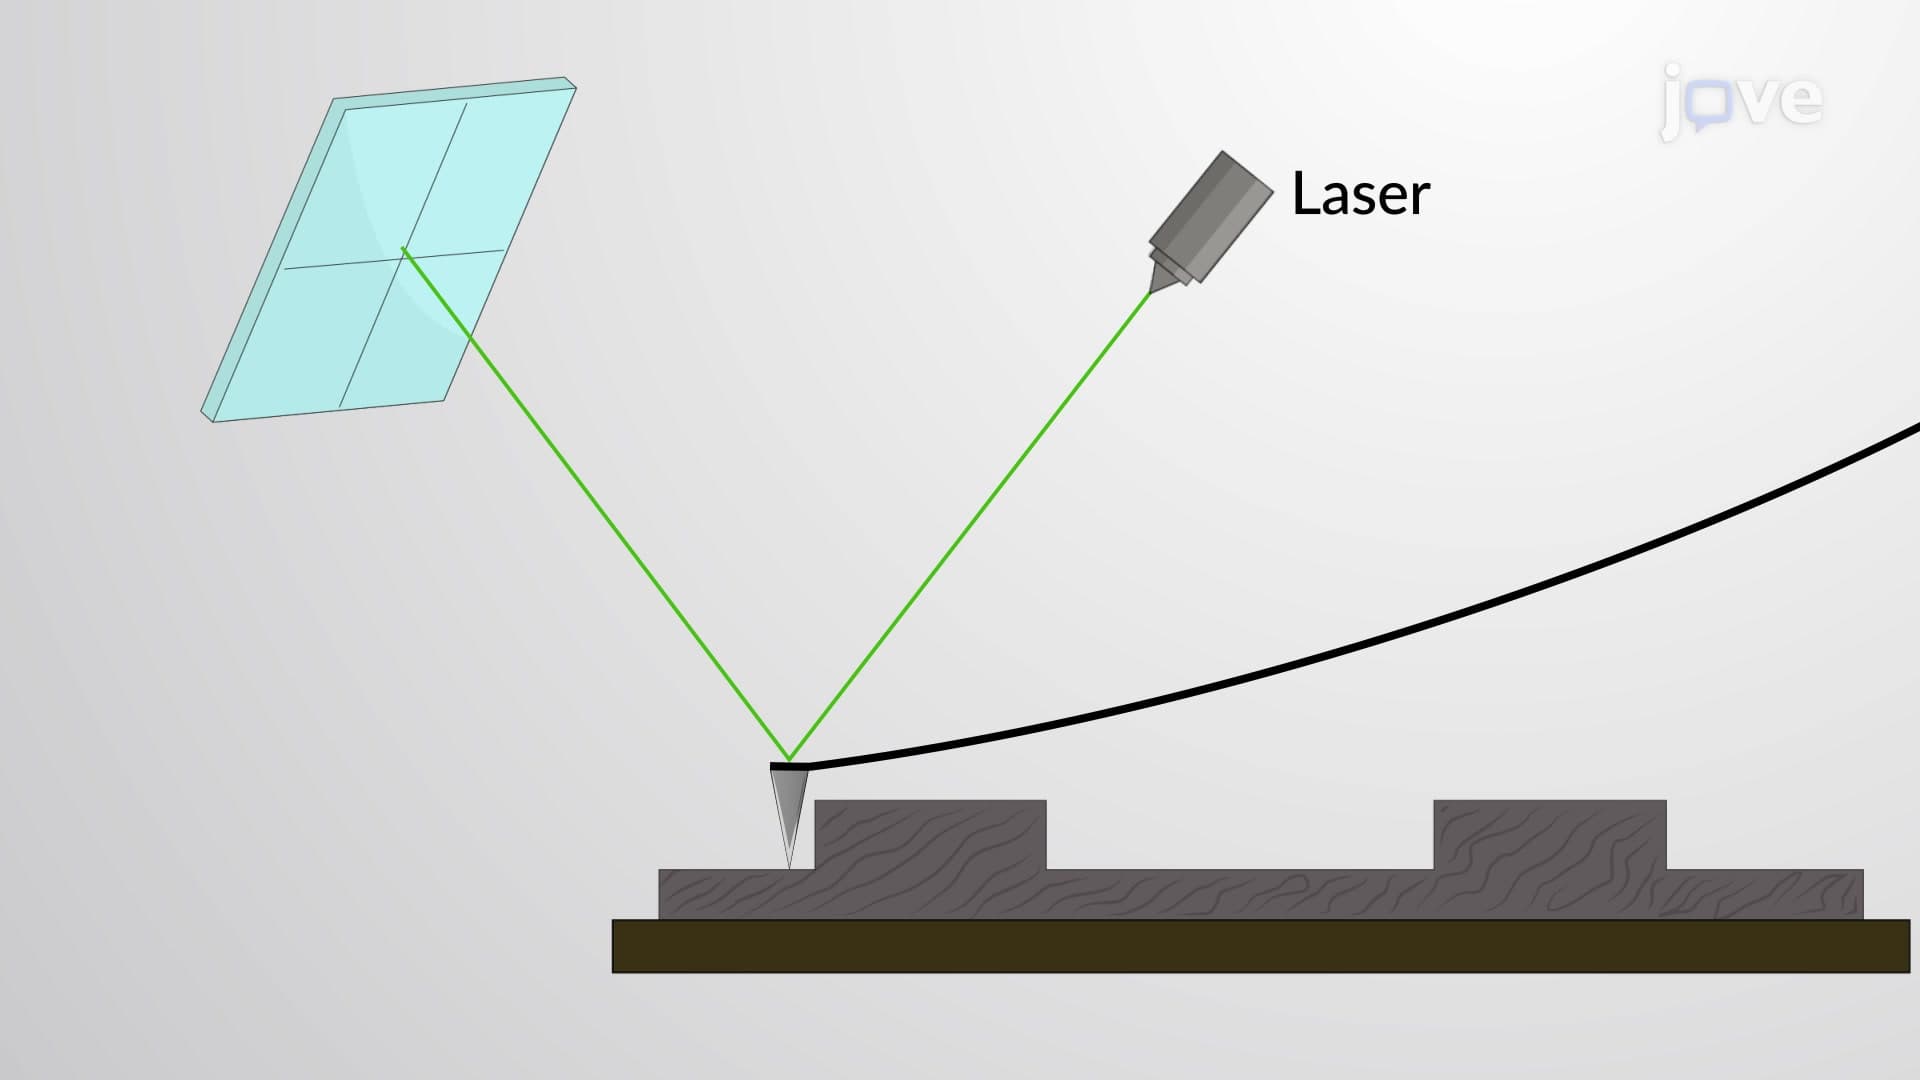
Atomic Force Microscopy
The AFM Probe
The probe is regarded as the heart of any AFM setup and comprises the...