Comparison of imputation methods for missing laboratory data in medicine
Related Experiment Videos
Akbar K Waljee1, Ashin Mukherjee, Amit G Singal
1Department of Internal Medicine, University of Michigan, Ann Arbor, Michigan, USA.

Objectives:
Missing laboratory data is a common issue, but the optimal method of imputation of missing values has not been determined. The aims of our study were to compare the accuracy of four imputation methods for missing completely at random laboratory data and to compare the effect of the imputed values on the accuracy of two clinical predictive models.
Design:
Retrospective cohort analysis of two large data sets.
Setting:
A tertiary level care institution in Ann Arbor, Michigan.
Participants:
The Cirrhosis cohort had 446 patients and the Inflammatory Bowel Disease cohort had 395 patients.
Methods:
Non-missing laboratory data were randomly removed with varying frequencies from two large data sets, and we then compared the ability of four methods-missForest, mean imputation, nearest neighbour imputation and multivariate imputation by chained equations (MICE)-to impute the simulated missing data. We characterised the accuracy of the imputation and the effect of the imputation on predictive ability in two large data sets.
Results:
MissForest had the least imputation error for both continuous and categorical variables at each frequency of missingness, and it had the smallest prediction difference when models used imputed laboratory values. In both data sets, MICE had the second least imputation error and prediction difference, followed by the nearest neighbour and mean imputation.
Conclusions:
MissForest is a highly accurate method of imputation for missing laboratory data and outperforms other common imputation techniques in terms of imputation error and maintenance of predictive ability with imputed values in two clinical predicative models.
Related Concept Videos
 01:24
Kaplan-Meier Approach
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:26
Pharmacokinetic Models: Comparison and Selection Criterion
Physiological models take a detailed approach by considering specific molecular processes. They can predict drug distribution, metabolism, and elimination changes, providing a comprehensive understanding of how drugs interact with the body.
 01:16
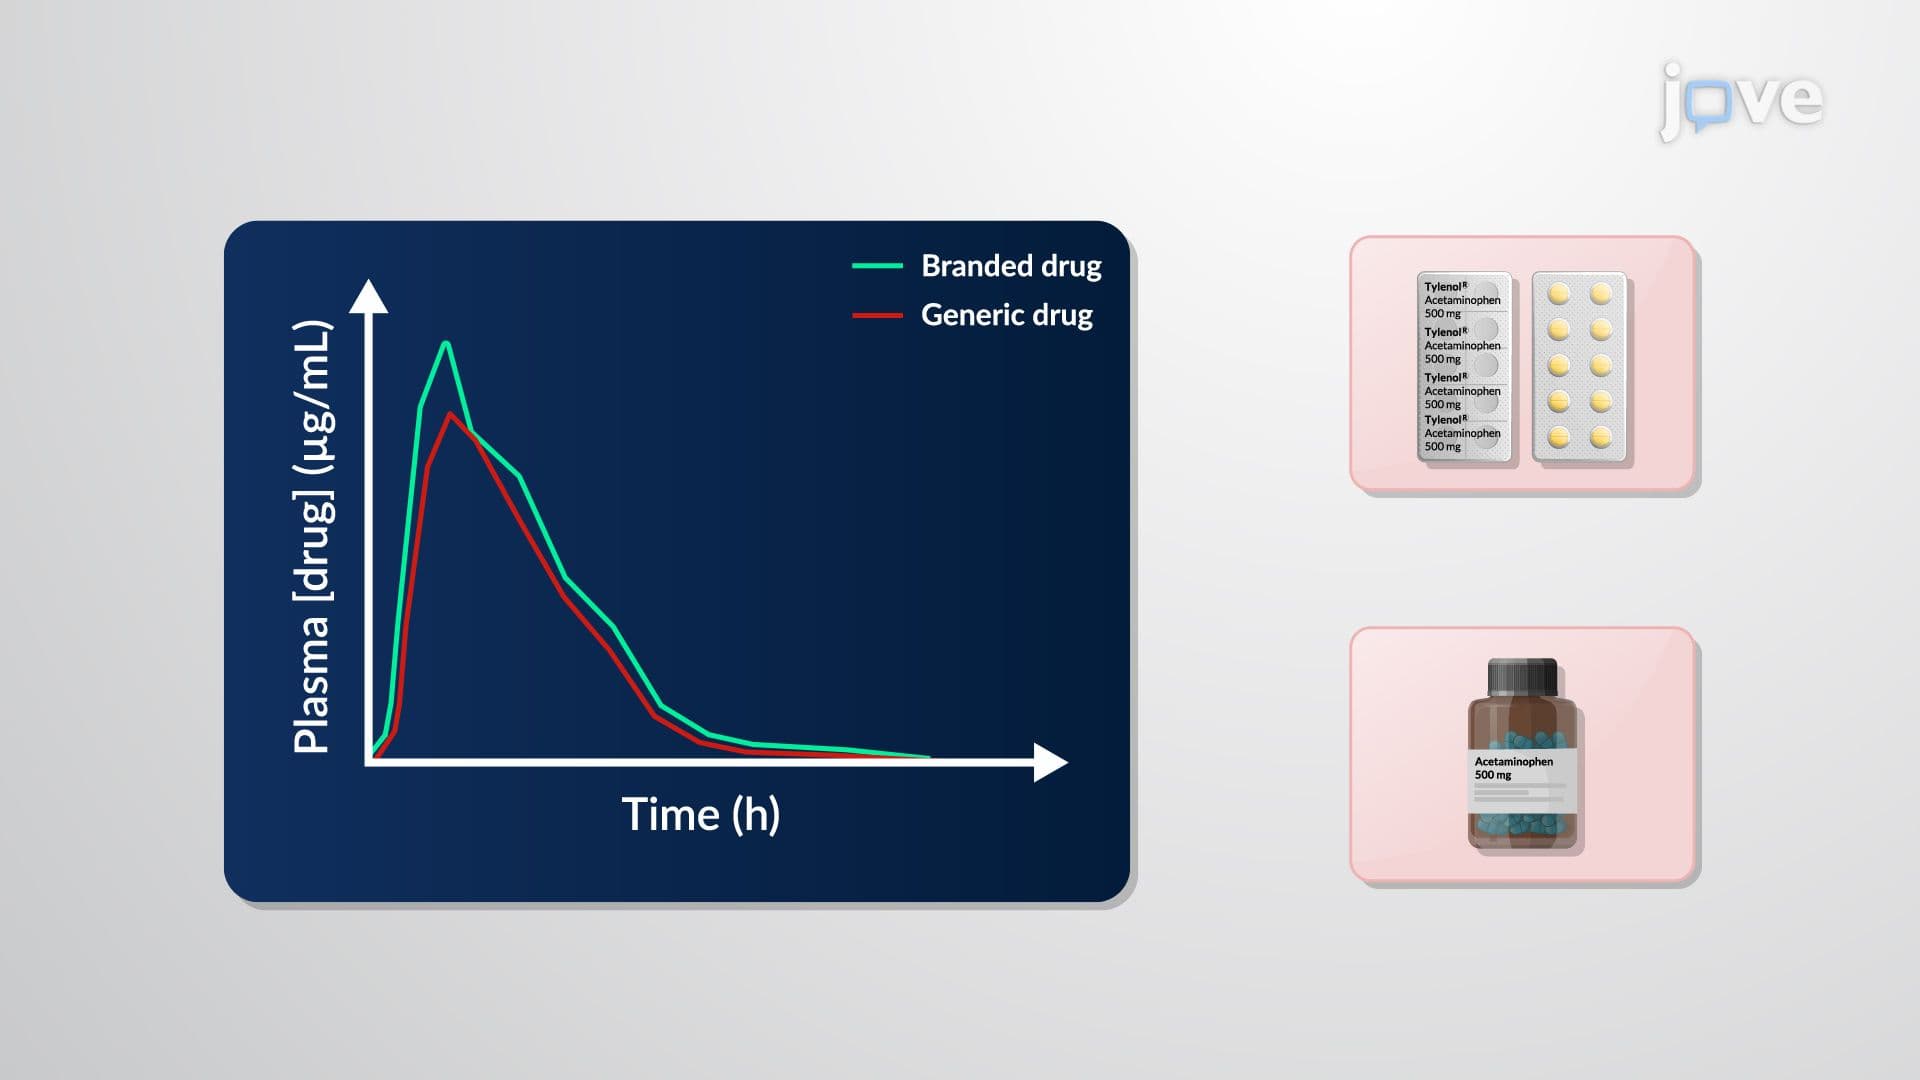
Bioequivalence Data: Statistical Interpretation
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...